Title: Capybara: Dynamic Load Balancing with Microsecond-Scale TCP Migration
Authors: Inho Choi, Guangda Sun, Jialin Li (National University of Singapore); Nimish Wadekar (ETH Zürich); Raj Joshi (Red Hat / Harvard University); Joshua Fried, Omar S. Navarro Leija (University of Pennsylvania); Dan R. K. Ports, Irene Zhang (Microsoft Research)
Scribe: Xiaoqiang Zheng (Xiamen University)
Introduction:
Traditional L4 load balancers assign each TCP connection to one server and cannot move it later. This is safe for TCP, but long-lived connections with skewed workloads can overload a few servers and sharply increase tail latency. L7 proxies can rebalance requests, yet they are application-specific and may become bottlenecks.
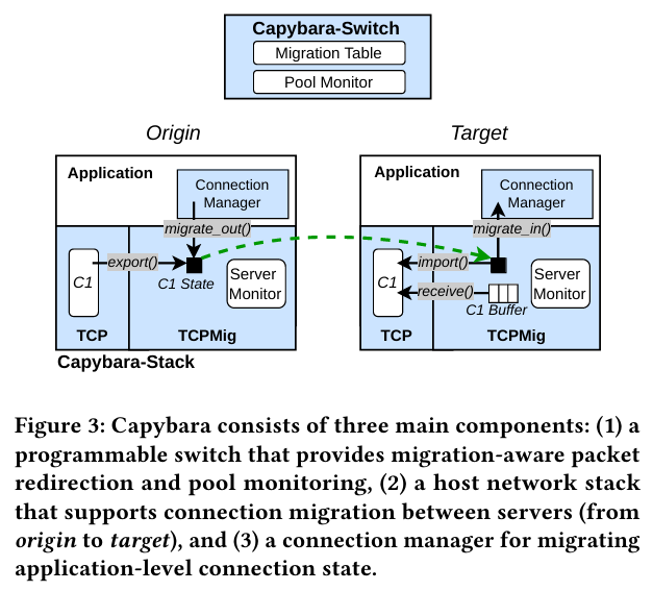
Capybara enables dynamic migration of established TCP connections. It combines a programmable switch, a host network stack that migrates TCP state, and an application interface for moving connection-local state. The goal is microsecond-scale rebalancing that remains transparent to clients and supports HTTP, Redis, and TLS.
Key idea and contribution:
Capybara-Switch assigns new connections, monitors server load, and redirects packets after migration. Capybara-Stack adds TCP migration to a kernel-bypass stack. Its two-phase protocol first prepares a buffer at the target and redirects packets atomically; it then transfers TCP state and releases buffered packets. This prevents TCP resets and allows migration at any point in a stream.
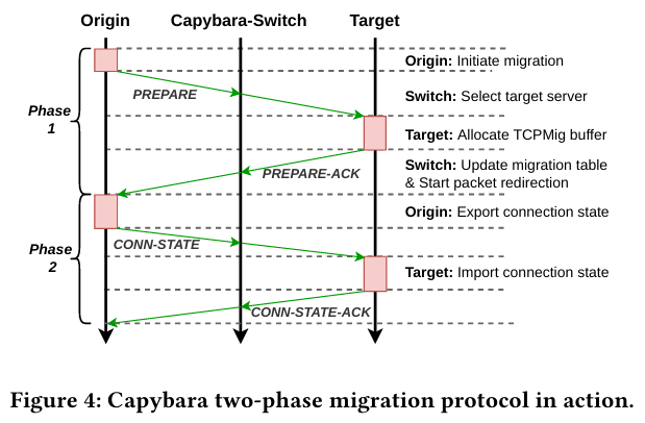
Because an L4 switch cannot understand application state, Capybara provides a connection-manager interface for exporting and importing HTTP or TLS state. Proactive migration responds to pool-wide imbalance, while reactive migration responds to local queue growth. The architecture therefore keeps the switch application-agnostic while supporting correct higher-level semantics.
The main contribution is lossless, in-network-assisted migration for dynamic L4 load balancing, without terminating connections at a proxy. By coordinating the programmable switch with the host network stack, Capybara can rebalance established connections while remaining transparent to clients and preserving TCP correctness.
Evaluation:
The prototype uses a Tofino programmable switch and a Rust host stack integrated with Demikernel. Tests cover HTTP, read-only Redis, and TLS on up to 12 servers with uniform and Zipf-skewed traffic. Migration adds less than 3 microseconds of host CPU overhead and completes in under 15 microseconds for default TCP state.
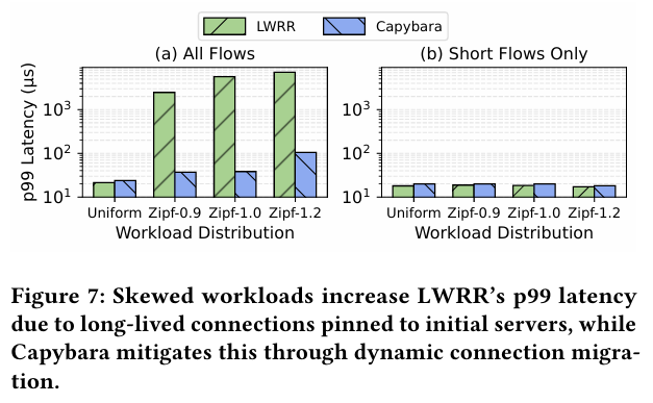
Under skewed workloads, Capybara reduces p99 latency by up to 149 times relative to Load-aware Weighted Round Robin. For Redis at 60% utilization, it reduces p99 latency by 74 times to around 100 microseconds. With 12 servers and 720 long-lived connections, it achieves about twice the baseline throughput and approaches uniform-load performance. The reactive and proactive policies also keep p99 latency below 1 ms during a sudden overload.
The system supports 200,000 concurrent connections, scales throughput with server count, and keeps total migration latency below 60 microseconds with 128 KB of additional TLS state. It also handles open-loop L7 traffic without dropping in-flight requests.
Q&A
Q1: That was a very interesting talk. I was wondering how the system responds to short-lived events, such as sudden changes in traffic. How reactive is it to those events? I mean short microbursts, where the traffic suddenly spikes.
A1: I see. A microburst can overload a server for a very short time. If every microburst triggered a migration, the migration itself could introduce unnecessary overhead. That is why Capybara provides multiple migration policies to avoid these cases. The system monitors the workload and triggers migrations only when it detects a meaningful imbalance between servers.
Q2: Would this also handle pulsing attacks, where the traffic repeatedly spikes and falls?
A2: Capybara monitors the load distribution across servers from the switch. It triggers migration only when there is a real load imbalance between servers. A temporary spike that does not create a meaningful imbalance does not automatically cause a migration.
Personal thoughts:
My main takeaway is that Capybara occupies a useful middle ground between rigid L4 balancing and application-heavy L7 proxies. The switch stays application-agnostic, while the host stack handles state transfer. The two-phase buffer is a convincing detail because it protects packets arriving while neither server owns the complete TCP state. The large gains under skewed workloads also closely match the paper’s motivation.
The main limitation is that applications with connection-local state must adopt the migration interface, so compatibility is not completely automatic. The design also assumes interchangeable servers and a capable programmable switching path. Future work should examine more varied service times, multi-threaded application state, repeated migration failures, and the operational cost of deploying Capybara at cloud scale.