Title: Connecting 100K+ GPUs: Building the Communication Stack for Large-Scale LLM Training
Authors: Hongyi Zeng, Min Si, Pavan Balaji, Yongzhou Chen, Ching-Hsiang Chu, Adithya Gangidi, Prashanth Kannan, Bingzhe Liu, Saif Hasan, Dong He, Deep Shah, Ashmitha Jeevaraj Shetty, Gregory R Steinbrecher, Srikanth Sundaresan, Yulun Wang, Yexin Wu, Mingran Yang, Kenny Yu, Minlan Yu, Cen Zhao, Shengbao Zheng, Wesley Bland, Denis Boyda, Suman Gumudavelli, Subodh Iyengar, Daniel Johnson, Cristian Lumezanu, Kai Luo, Rui Miao, Zhe Qu, Venkatraghavan Ramesh, Jingliang Ren, Maxim Samoylov, Jan Seidel, Qiye Tan, Feng Tian, Xinfeng Xie, Jingyi Yang, Yimeng Zhao, Shuqiang Zhang, Tiane Art Zhu (Meta)
Scribe: Yuntao Zhao (Xiamen University)
Introduction
As LLM training continues to scale, a single training job can involve more than 100,000 GPUs, pushing conventional GPU communication stacks to new scalability limits. Meta’s cluster spans multiple datacenter buildings, where GPU-to-GPU latency increases significantly with network distance. Communication across datacenter buildings can experience up to 30× higher latency than communication within a rack. Meanwhile, dynamic token routing in Mixture-of-Experts (MoE) models creates bursty and irregular All-to-All traffic, resulting in transient congestion hotspots.
At this scale, operations that were previously considered lightweight, such as communication initialization, resource allocation, and fault handling, also become significant. Initialization can take minutes at large scale, while communication libraries consume valuable GPU high-bandwidth memory. To address these challenges, the paper presents Meta’s communication stack for 100K+ GPU clusters, jointly optimizing the communication library, transport layer, and operational tooling for large-scale LLM training.
Key Idea and Contribution
The main idea of the paper is that communication at 100K+ GPU scale cannot be addressed by optimizing individual collective algorithms alone. Scalability of the communication library, network congestion, and production reliability need to be considered together.
(1) CCLX for large-scale training
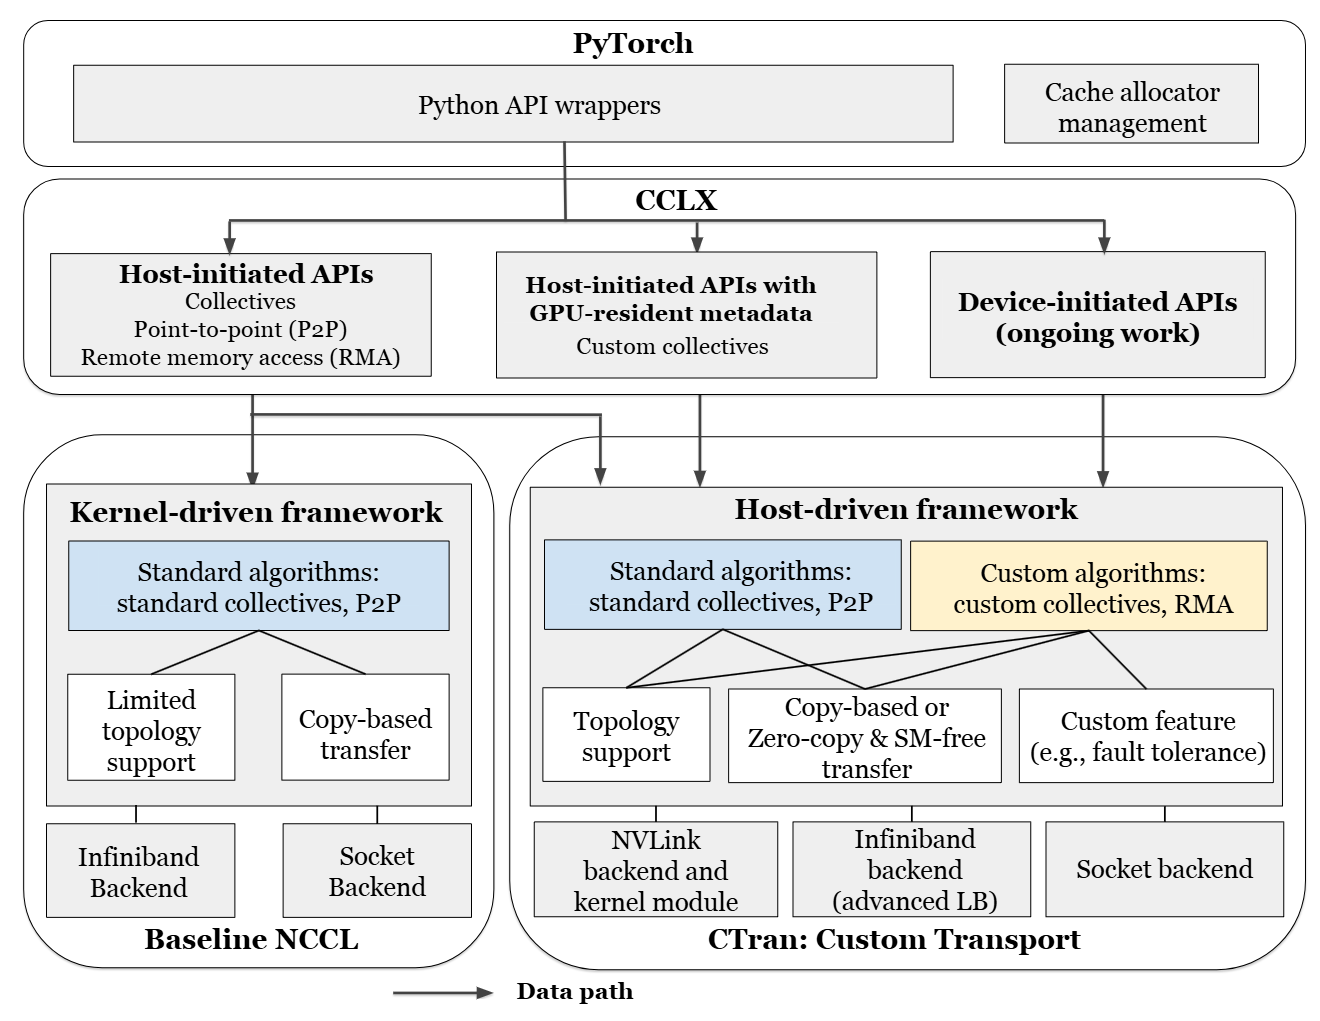
The authors develop CCLX, a GPU communication library designed to reduce initialization and resource overhead at large scale. For scalable initialization, CCLX combines eager initialization, asynchronous I/O bootstrapping, and lazy initialization resource allocation. It also reduces topology computation complexity from (O(N^2)) to (O(N)), decreasing the initialization cost of job startup and recovery.
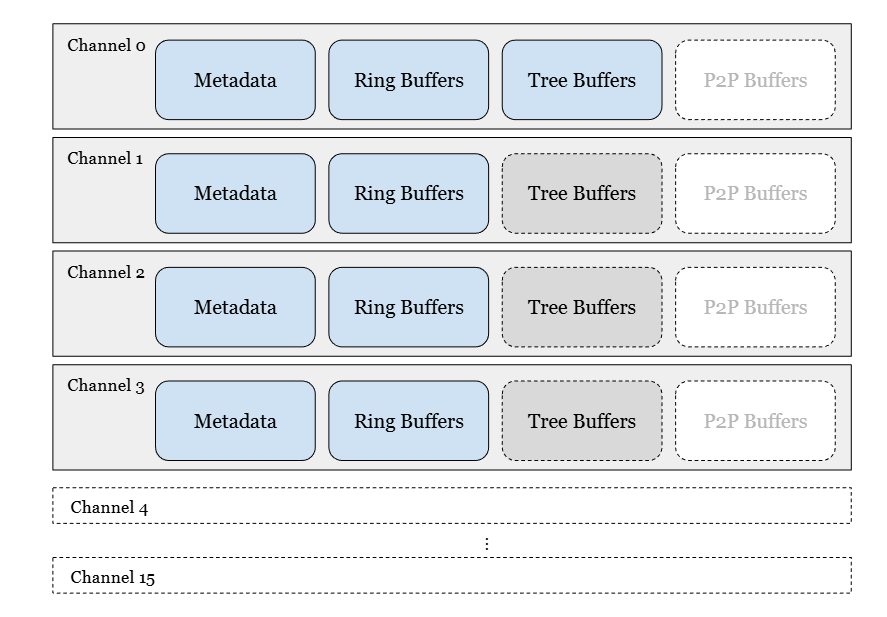
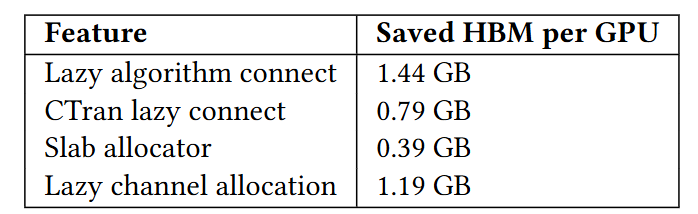
For HBM management, CCLX avoids eagerly provisioning complete resources for every communicator, algorithm, and channel. Instead, algorithm buffers, QPs, and channels are allocated on demand, while a slab allocator reduces metadata fragmentation. These mechanisms reduce the GPU memory consumed by the communication stack.
(2) DQPLB for high-BDP networks
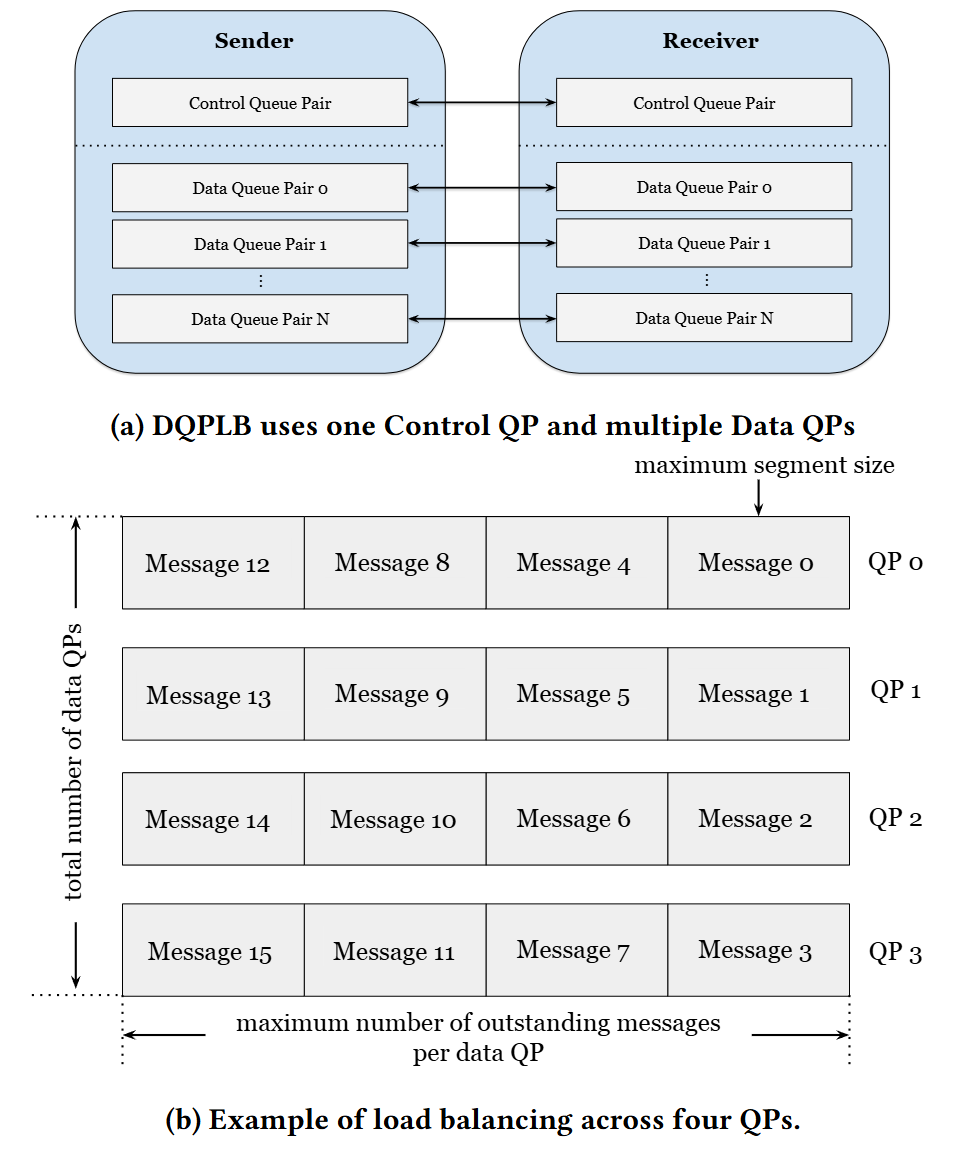
TLinks across racks, AI zones, and datacenter buildings have different RTTs and bandwidth-delay products. Although zero-copy communication reduces control-plane latency, large unsegmented transfers can create excessive switch buffer buildup. The paper therefore proposes Dynamic Queue Pair Load Balancing (DQPLB), which segments data and dynamically configures the number of data QPs, segment size, and maximum outstanding messages according to the BDP of each path.
Connections with lower BDP use more conservative settings, while distant high-BDP connections use more QPs and a larger amount of outstanding data. This allows DQPLB to maintain high link utilization while controlling transient bursts and switch buffering.
(3) Operational tooling for production-scale training
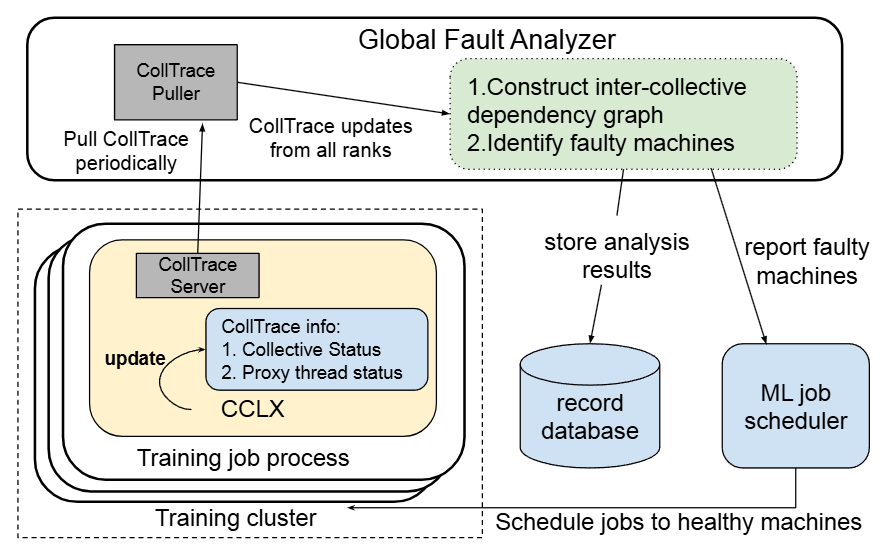
At 100K+ GPU scale, hardware failures become a regular operational concern. The paper develops a set of tools including Fault Analyzer, PerfProfiler, and a distributed CPU emulation framework. Fault Analyzer uses inter-collective dependency graphs to identify root-cause failures; PerfProfiler combines algorithm-level and transport-level measurements to locate performance bottlenecks; and distributed CPU emulation validates control-plane scalability without requiring a full GPU deployment.
Evaluation
The communication stack has been deployed in Meta’s production training cluster. The cluster spans five datacenter buildings in one datacenter region and contains approximately 129,000 H100 GPUs at completion. CCLX and its associated tooling have supported state-of-the-art LLM training in the cluster since late 2024.
(1) Initialization and Memory Overhead
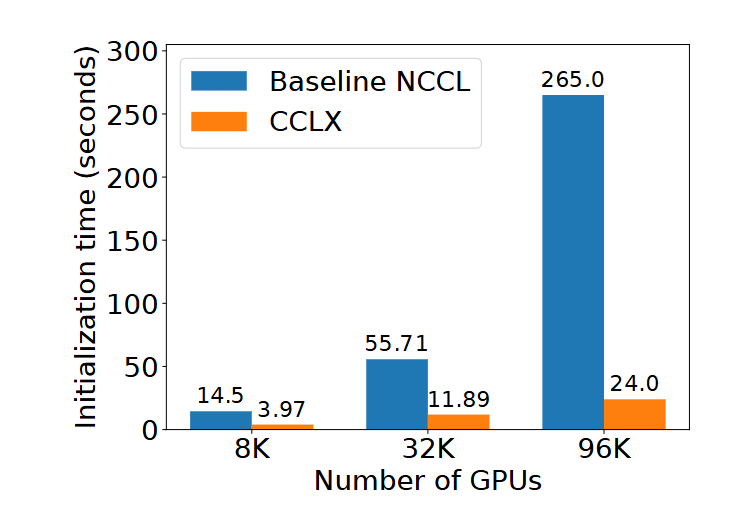
Communication initialization becomes increasingly expensive as the system scales. At 96K GPUs, baseline NCCL requires 265 seconds for default process-group initialization, while CCLX reduces the time to 24 seconds, providing up to an 11× improvement.
For memory usage, the paper observes that NCCL can consume roughly 10 GB of HBM when more than ten communicators are used in multidimensional LLM training. With lazy resource allocation, lazy channel provisioning, and slab allocation, CCLX reduces communication-related GPU memory usage by nearly 2× at large scale.
(2) DQPLB Network Performance
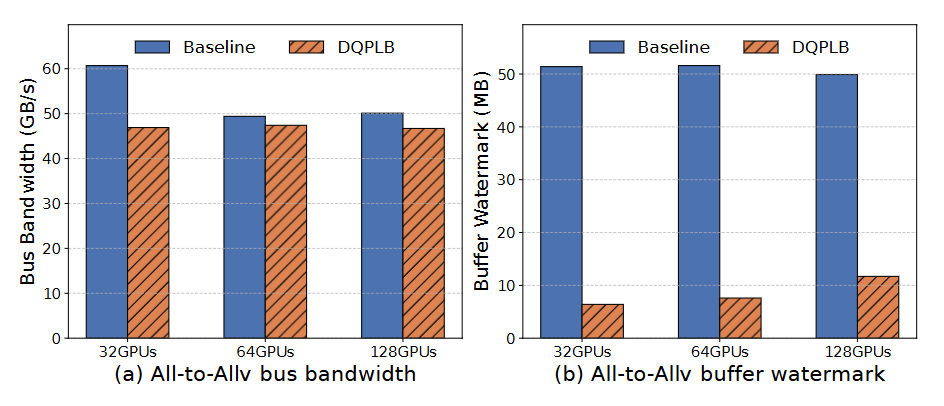
In All-to-Allv experiments with 32, 64, and 128 GPUs, DQPLB maintains throughput close to the maximum network capacity while substantially reducing switch buffer usage. Peak buffer utilization is reduced by almost 90% at 32 GPUs and by approximately 75% at 128 GPUs.
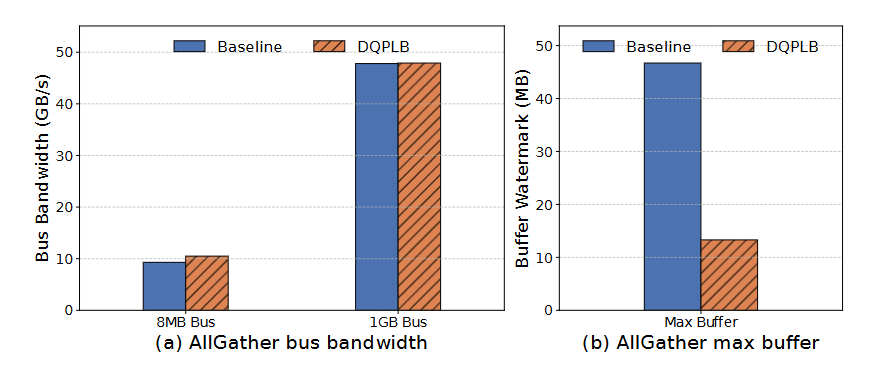
In a 256-GPU AllGather experiment, tuning segment sizes and QP counts according to path BDP reduces peak buffering by 72%, with no performance penalty for 1 GB messages and a 13% improvement in bus bandwidth for 8 MB messages.
(3) Large-Scale Operational Validation
The operational tools are also evaluated on real training failures. In a 4K-GPU job where approximately 500 collectives timed out, Fault Analyzer identified a rank that failed to launch the corresponding collective and helped trace the problem to a model software bug. In another 8K-GPU training job, dependency and communication-state analysis eventually identified a malfunctioning NIC as the root cause.
The distributed CPU emulation framework can emulate 96K ranks on 12K CPU servers. It exposed several scale-triggered control-plane problems, including OS-level bootstrap limits beyond 64K ranks, resource state that unexpectedly grew with the number of peers, and (O(N^2)) initialization telemetry amplification.
Q&A
Q1: When scaling to around 100K GPUs, are there issues that are not very important at small scale but become major bottlenecks at this scale? And if you scale further to 200K or 300K GPUs, what may need to change fundamentally?
A1: I mentioned a couple of things, such as initialization delays and memory usage. Taking memory usage as an example, NCCL uses many memory buffers to achieve high performance, such as copy buffers and staging buffers. Many people may not realize that the amount of buffer usage can grow as the cluster scales. If the cluster becomes even larger, the memory consumption on a single GPU may continue to increase, which is not sustainable. I think this is something the community should look into, especially how to control this kind of resource utilization at larger scale. Another critical resource is the SMs. Using more SMs can usually achieve higher communication bandwidth, but we cannot use all of them for communication. Otherwise, there would not be enough GPU compute resources left for the model.
Q2: What is the runtime overhead of lazy memory allocation, and how do you ensure that the system does not run out of memory at runtime?
A2: I do not think lazy memory allocation introduces significant overhead. It simply delays the allocation. Memory allocation itself does take some time, but that overhead is usually hidden because the GPU is already busy doing other work when the allocation happens. As long as the GPU is busy, the latency overhead does not really matter. When the algorithm is selected, the corresponding memory allocation starts. But by that time, the system has usually already passed the very initial stage, and the GPU is typically doing something else, so it is generally fine.
Q3: After all the optimizations you have done so far, what is the main remaining bottleneck? In other words, what is the next major challenge you are trying to address?
A3: I think we are trying to overcome some physical limits, and that is very difficult. One typical physical limit is latency. We need to connect datacenters over longer distances, and the resulting few milliseconds of latency cannot be easily eliminated just by optimizing the communication mechanisms. So we need to co-design these systems together with our partners on the model team. I think this is an important remaining bottleneck, and it requires cross-layer co-design.
Personal thoughts
The most interesting aspect of this work is that it does not focus on optimizing a single communication algorithm. Instead, it considers the communication problem from the perspective of a real 100K+ GPU training system and jointly addresses the communication library, transport mechanisms, and production operations. The paper shows that, at this scale, initialization overhead, memory usage, latency differences across the network, and fault diagnosis can all have a direct impact on training efficiency. Therefore, communication-stack design needs to consider overall training goodput rather than only raw data-transfer performance. However, the current global state-exchange mechanism in CCLX still faces scalability challenges as cluster size continues to grow. The paper also notes that future systems may need hierarchical initialization or decentralized peer-discovery mechanisms to support larger deployments.