Title: Detection and Localization of End-to-end Bitflip Errors in Data Centers
Authors: Abhigyan Sharma, Neil Spring, Srikanth Sundaresan, Francesco Caggioni, Laurent Virot, Arber Mancaj (Meta)
Scribe: Mengrui Zhang (Xiamen University)
Introduction
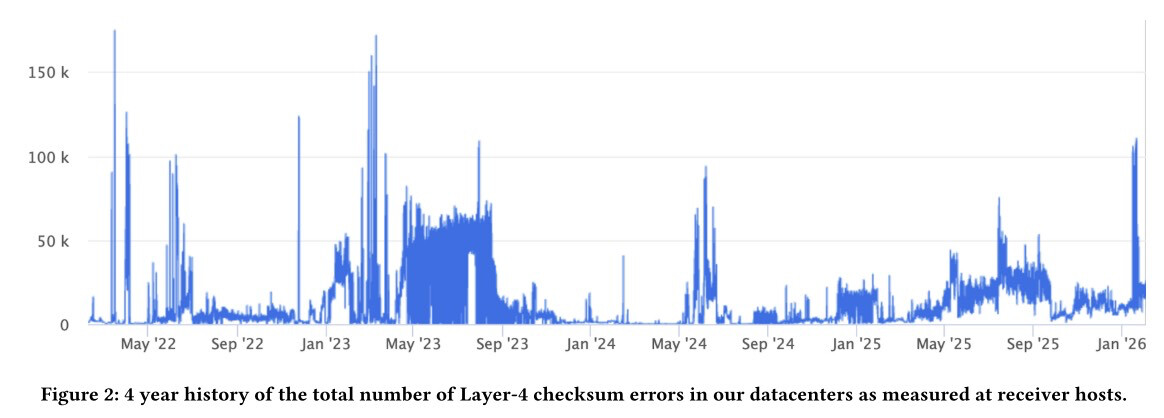
A packet can be corrupted while a switch is forwarding it even though every hop-level Layer-2 CRC and Layer-3 checksum has passed. The outgoing port computes a fresh CRC over the already corrupted packet, so the corruption can reach the destination and only be detected by the end-to-end Layer-4 TCP checksum. TCP’s 16-bit checksum is weaker than the 32-bit link CRC, and a still rarer silent error can pass it and reach the application. At hyperscale, even low-probability bitflips lead to packet drops, retransmissions, service impact, and occasional data corruption.
Localizing the responsible host, link, switch, or port is difficult. The host checksum counter does not identify where along a multipath path the corruption occurred; the search can span hundreds of thousands of switches; and a bad device may corrupt only a small fraction of flows or payloads, so an ordinary iperf test may fail to reproduce it. The paper presents Flipperino, a production system combining passive detection, active path probing, and port-level reproduction.
Key idea and contribution
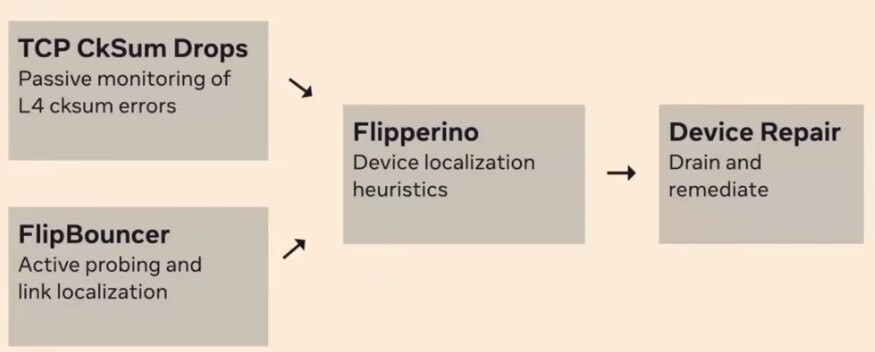
TCPCkSumDrops for fleet-wide passive detection. TCPCkSumDrops is an eBPF program running on receiving hosts. It records every TCP checksum error dropped by the kernel and attaches source and destination context, including host, NIC, rack, datacenter, region, and service metadata. Because the program runs only when a checksum error occurs, its overhead is low. The resulting data identifies heavy-hitter source hosts, destination hosts, and rack links, but it cannot see intermediate fabric or spine switches.
FlipBouncer for active link localization. FlipBouncer extends path-monitoring ideas from NetBouncer. It pins probe packets to selected paths with IP-in-IP, checks whether returned payloads match what was sent, and aggregates path observations to infer faulty links. Randomized source IPs increase entropy in switch-ASIC memory accesses, while randomized payloads expose more corruption patterns. Because bitflips are sparse, the system also adapts the fault-inference procedure to avoid incorrect localization from only a few detected packets.
Flipperino for device-level attribution. Passive and active signals identify bad links or candidate endpoints, while operators ultimately need a device that can be drained and remediated. Flipperino applies two heuristics. The dominant-rack heuristic filters intra-datacenter checksum drops and selects a rack explaining more than half of the drops; a single explanatory host is blamed directly, otherwise the rack switch is selected. The voting heuristic assigns votes to both endpoints of links reported by FlipBouncer and selects the highest-voted device, again refining to a host when one host explains the observations.
Flippy for port-level reproduction. After a switch or link is localized, Flippy runs a loopback test on an isolated switch port to reproduce packet corruption and confirm the specific port. The three components are complementary: passive monitoring covers production traffic and host/rack outliers, active probing reaches fabric and spine paths, and loopback reproduction provides final device evidence.
A staged production workflow. The workflow is detection, candidate localization, active probing, device attribution, and reproduction. Once a device is confirmed, operators can drain it from production. The system is designed for in-datacenter operation and does not require recabling or special tester hardware; tests are scoped to selected hosts and links to limit interference with normal traffic.
Evaluation
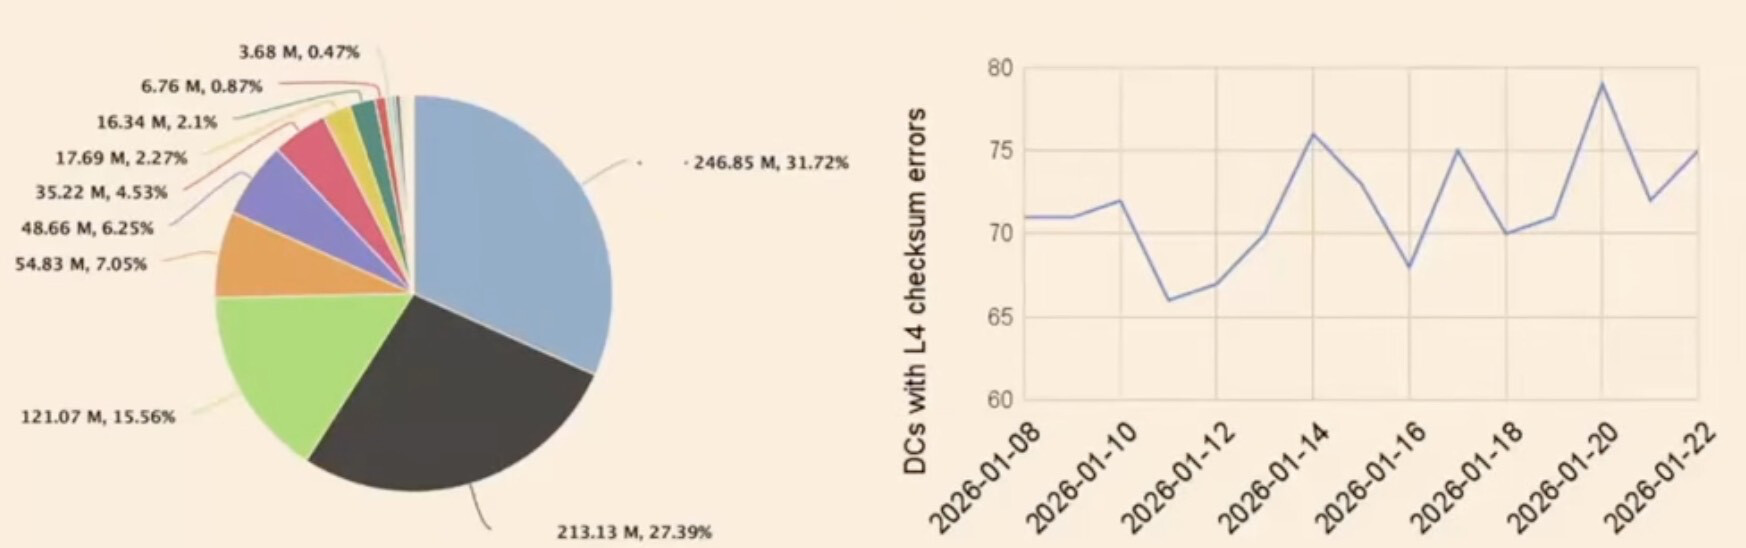
Fleet-scale error distribution. The presentation reports that a small number of datacenters account for most checksum errors, while a long tail of more than 70 datacenters still contains errors. This motivates a continuously running fleet-wide system that can find both heavy hitters and sparse tail devices. The paper reports up to four years of operation for Flipperino’s components.
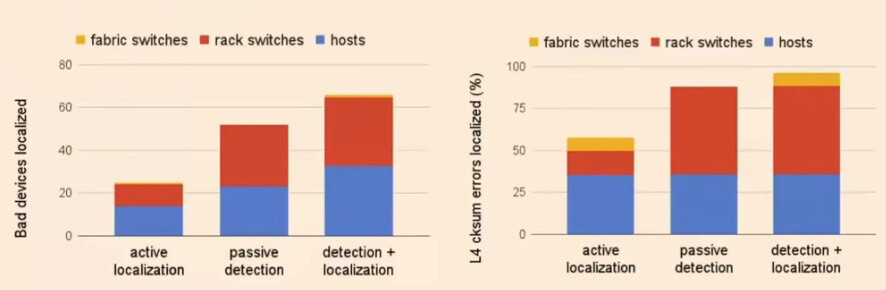
Complementary localization signals. TCPCkSumDrops alone identifies devices responsible for 87% of Layer-4 checksum errors. FlipBouncer finds almost 30% more bad devices that passive source and destination context cannot localize, and the combined system attributes about 97% of errors to localized devices. The result demonstrates why neither passive nor active monitoring alone covers all topology layers.
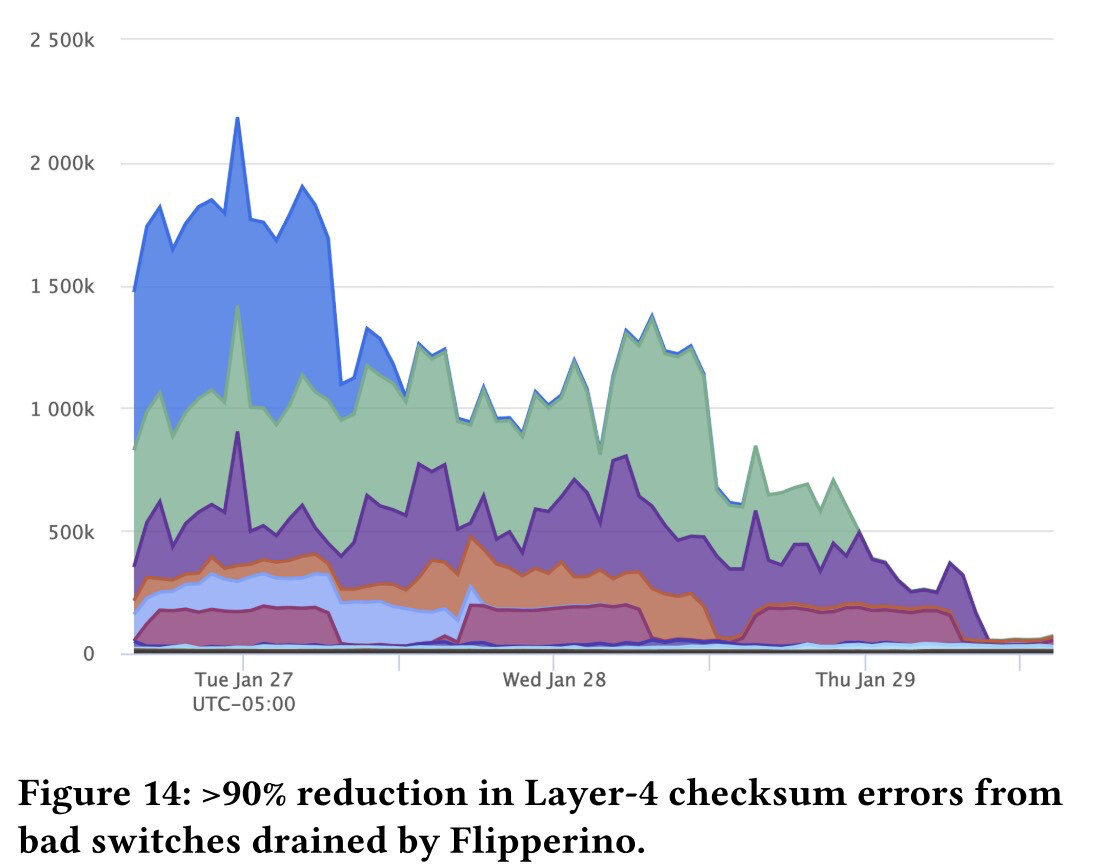
Remediation and reproduction. Enabling Flipperino in seven datacenters reduced Layer-4 checksum errors by 90% within three days. Some devices had been corrupting packets for weeks before identification. Flippy reproduced and localized corruption on eight switches in the last three months, including seven rack switches and one fabric switch. These measurements provide evidence that the localized devices were genuine operational faults rather than statistical outliers.
Q&A
Q1: How can Flipperino localize bitflips in a backend network that uses packet spraying, and can the same approach support RDMA traffic?
A1: So far, we have deployed this system on the frontend TCP network. We could potentially deploy FlipBouncer in a packet-sprayed backend because IP-in-IP path pinning would make path localization possible. However, TCPCkSumDrops depends on kernel TCP checksum-drop events, and building an equivalent passive signal for RDMA is much harder, so backend coverage remains an open challenge.
Q2: Can a bitflip silently reach the application when traffic is protected by end-to-end encryption?
A2: Our reported incidents concern non-encrypted traffic inside the fleet. We have not claimed that an undetected bitflip can bypass the integrity protection of an end-to-end encrypted protocol; decryption and authentication would normally detect a modified ciphertext. The Flipperino measurements therefore apply to the unencrypted traffic covered by our deployment.
Q3: How do you balance the probe budget with the probability of reproducing a sparse corruption, and how do you choose probe payloads?
A3: We keep the probe budget very small: roughly a few hundred to about one thousand packets on a link that may carry around 100 million packets. The probes should be nearly invisible to fleet monitoring. Within that budget, we maximize detection probability by randomizing source entropy and payload contents. The presentation described a rough budget of about 1,000 probes per second per link, with the exact tradeoff depending on the path and fault pattern.
Personal thoughts
Flipperino’s strongest contribution is the combination of signals with different blind spots. Passive monitoring is cheap and sees real production traffic, active probing reaches fabric layers that host counters cannot observe, and port-level reproduction turns a statistical suspicion into evidence suitable for draining a device. The long deployment history and the 90% reduction after draining seven devices make the engineering value especially clear.