Title: EPIC: Abstraction and Polymorphism of In-Network Collectives on Ethernet
Authors: Yitao Yuan, Jianglong Nie, Tianyu Bai, Ruizhe Zhou, Siyuan Cao, Xujie Fan, Yuchen Xu, Junkai Chen, Chenqi Zhao, Nengyuan Zhang, Shaoke Fang, Jiaqi Sun, Wenfei Wu (Peking University), and other members of the ETH+ Consortium; collaborating institutions also include the University of Science and Technology of China, National University of Defense Technology, Institute of Computing Technology at the Chinese Academy of Sciences, Beijing University of Posts and Telecommunications, Infrawaves, Lenovo Research, Centec Networks, and Alibaba Cloud.
Scribe : Mengqi Fu (Xiamen University)
Introduction
In-Network Collective (INC) offloads part of the computation in collective operations such as AllReduce to switches, reducing traffic volume and end-host overhead. Yet INC has been difficult to deploy in the open Ethernet ecosystem. The challenge lies not only in the different capabilities of switch ASICs, but also in the fact that communication libraries, RoCE NICs, switches, and controllers are usually supplied by different participants. Investment by any one party cannot guarantee end-to-end interoperability, easily resulting in high-cost, low-return islands of functionality. EPIC reframes the problem from requiring all hardware to implement the same INC design to defining a unified functional abstraction and interfaces first, while allowing implementations of different complexity levels to coexist.
Key Idea and Contributions
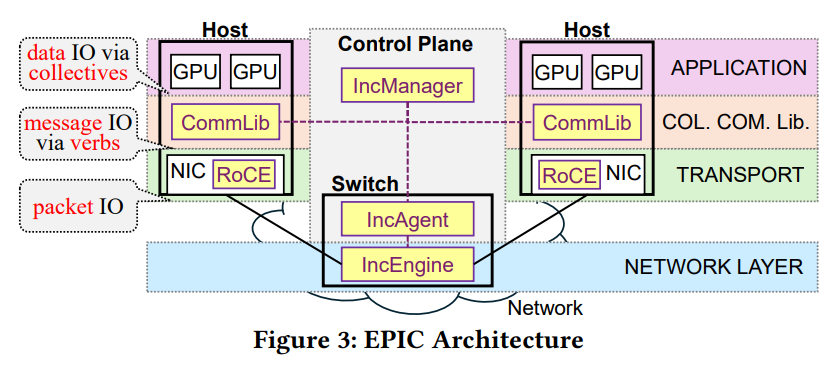
EPIC builds an open INC architecture across three layers—the abstraction, data plane, and control plane—and makes five main design contributions:
-
An IncTree abstraction that uniformly represents six collective primitives. A communication group is represented as an IncTree whose leaves are ranks and whose intermediate nodes are INC switches. Each tree edge maps to an Ethernet/RoCE path between two endpoints identified by
<IP, QP>. AllReduce, Reduce, and Broadcast are basic operations, while Barrier, ReduceScatter, and AllGather are composed from them. The abstraction specifies how data is aggregated, converges toward the root, and is replicated toward the leaves without binding these semantics to a particular switch ASIC. -
Interoperability with standard RoCE. The host-side CommLib continues to invoke standard RDMA Verbs, while the switch-side IncEngine processes standard RoCE packets. Before data transmission, CommLib uses a Send with Immediate control message to announce the collective type, root, and data size, avoiding a dedicated INC packet header. INC therefore extends the existing Ethernet/RoCE stack rather than requiring NICs and switches to adopt a proprietary transport protocol.
-
Three polymorphic data planes assembled from reusable modules. EPIC decomposes the data plane into modules for state lookup, routing, duplicate detection, aggregation, replication, ACK processing, and retransmission, then composes them into three modes. Mode-I fully terminates RoCE connections at the switch, providing the strongest functionality at the highest logic and state cost. Mode-II avoids a full transport stack through header translation, duplicate detection, and end-host retransmission, giving it the lowest implementation barrier. Mode-III introduces a pipe abstraction and hop-by-hop retransmission, improving loss tolerance without implementing a complete RoCE endpoint.
-
A systematic analysis and validation of the capability–cost trade-off. Modes II and III use packet-level pipelining and avoid Mode-I’s message-level store-and-forward behavior. Modes III and I require less space than Mode-II, while Modes I and III provide better loss tolerance than Mode-II.
-
A unified resource model derived from the abstraction. IncManager uses pointer indirection to separate long-lived group context from large, transient SRAM regions. This allows the controller to support edge-disjoint trees (EDT), Spatial Mux, and Temporal Mux: EDT assigns INC using edge-disjoint paths, while the latter two allocate switch memory for either an entire job lifetime or an individual communication operation. EPIC thus specifies not only how packets are processed but also a common interface for multi-tenant resource arbitration.
Evaluation
EPIC is evaluated through TLA+ model checking, OVS/SoftRoCE emulation, Tofino- and NP-switch testbeds, NS3/OMNeT++ simulation, FPGA prototypes, and chip-level RTL.
-
Correctness and interoperability across implementations. On a Tree-3-2 topology, all three modes satisfy two properties under reliable, lossy, and out-of-order network conditions: their results are equivalent to single-server execution, and the protocols eventually terminate. In the OVS/SoftRoCE environment, EPIC-I, EPIC-II, and EPIC-III all interoperate correctly with standard RoCE hosts.
-
AllReduce and basic collective performance. On a Tree-2-8 testbed with eight GPUs and one switch, EPIC accelerates AllReduce by 1.59× over NCCL when both use 256-byte payloads. One Barrier operation takes approximately 5 μs with EPIC, compared with about 2 ms for NCCL, yielding a roughly 400× improvement.
-
Training and inference applications. For Llama-3.2-1B with TP=8, EPIC reduces iteration time from 46.1 s with NCCL to 35.1 s, a 31.3% improvement. With DP=8, where communication accounts for a smaller fraction of execution, the gain is about 1.2%. For GPT-2 Large inference, TTFT and TPOT fall from 37.9/36.3 ms to 26.8/25.1 ms, reductions of 29.3% and 30.9%, respectively. In SimAI/NS3 large-model simulations, EPIC-II improves iteration time for GPT-3-175B, GPT-3-13B, Llama-65B, and Llama-7B by 22%, 22%, 14%, and 12%, respectively.
-
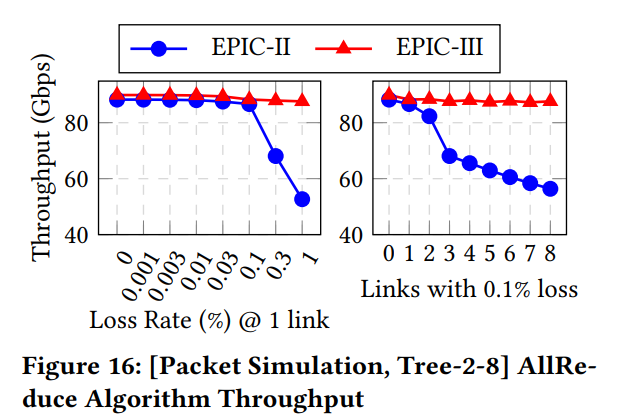
Differences among the three modes under packet loss (Figure 16). When the loss rate on one link exceeds 0.1%, Mode-II throughput drops sharply because a single lost packet triggers redundant retransmissions from every rank for the same sequence number. Mode-III’s hop-by-hop ACK and retransmission mechanism allows loss-free branches to continue, resulting in a more gradual degradation. When the loss rate is fixed at 0.1% and the number of lossy links increases, losses accumulate across links in Mode-II, whereas Mode-III is governed mainly by the worst link. With a 100 Gbps background flow on a 200 Gbps link, rate synchronization further increases 16 MB AllReduce throughput from 43.3 Gbps to 95.9 Gbps.
-
Multi-tenant resource management. Across three workload traces on a 2048-GPU fat-tree, Ring has average JCTs of 6190, 6245, and 6267 s, while Temporal Mux reduces them to 3750, 4621, and 4618 s—the lowest among the four evaluated policies. By releasing SRAM after each communication group completes, Temporal Mux serves tail jobs more effectively than Spatial Mux, which reserves resources for an entire job lifetime. However, Temporal Mux may also temporarily reserve resources needed by other jobs, so it does not necessarily accelerate every individual job.
EPIC demonstrates that protocol abstraction, hardware polymorphism, and resource management need not be isolated concerns: an interoperability-oriented specification can still deliver substantial communication- and job-level gains on real devices and in multi-tenant settings.
Personal Thoughts
EPIC’s most important contribution is closer to a cross-vendor engineering protocol blueprint than merely a new AllReduce algorithm. IncTree, endpoints, and contexts establish the cross-layer semantics; the modular IncEngine confines hardware differences to individual implementations; and IncManager extends the protocol semantics into resource allocation. This layering is well suited to the coordination problem in an open ecosystem where all participants need the functionality but no single party can implement the complete stack alone.
I particularly appreciate the paper’s use of model checking as part of protocol design. The transition from Mode-II to Mode-III may appear to replace only end-to-end retransmission with hop-by-hop retransmission, but it also changes buffer lifetimes and root behavior; naively reusing the original logic can corrupt data. Exposing these errors at the specification stage is more valuable than validating a prototype through performance tests alone.