Title: InfiniFlow: Decoupling Virtual Channel Scalability from Buffer Requirements in Lossless Datacenter Networks
Authors: Zerui Tian, Sen Liu, Minkun Xue, Hao Shangguan, Ruyi Yao, Hao Mei, Deli Huang, Songchen Xue, Yang Xu (Fudan University)
Scribe: Yuntao Zhao (Xiamen University)
Introduction
Modern datacenter networks increasingly rely on Remote Direct Memory Access (RDMA) for high throughput and low latency, while hop-by-hop flow control is used to provide lossless transmission. Existing PFC and CBFC mechanisms isolate traffic at the granularity of Virtual Channels (VCs), but commodity devices support only a limited number of VCs. When multiple flows share the same VC, backpressure caused by a congested flow can also throttle other flows in that VC, resulting in Head-of-Line Blocking (HoLB) and congestion spreading.
Increasing the number of VCs can improve traffic isolation, but conventional mechanisms reserve buffer space for every VC. PFC and CBFC require at least 2× and 1× per-hop Bandwidth-Delay Product (BDP) per VC, respectively, causing the total buffer requirement to grow linearly with the number of VCs. The paper observes that all VCs on a port ultimately share a physical link with bounded aggregate transmission rate. Therefore, the packet buffer required for lossless line-rate transmission is fundamentally determined by the per-hop BDP of the port rather than the number of VCs. Based on this observation, the authors propose InfiniFlow, a credit-based hop-by-hop flow control mechanism.
Key Idea and Contribution
The main idea of InfiniFlow is to allow a large number of VCs on the same port to share packet-buffer resources, while letting the upstream node dynamically control how much of the shared buffer each VC can consume.
(1) Per-port buffer sharing
Instead of reserving an independent packet buffer for every VC, InfiniFlow shares packet-buffer space at the port level. Since the aggregate rate of all VCs is bounded by the physical link capacity, the packet-buffer requirement mainly depends on the per-hop BDP rather than the VC count. Per-VC metadata still grows with the number of VCs, but its memory footprint is much smaller than conventional per-VC packet-buffer reservation.
(2) Upstream-driven buffer allocation with UABD
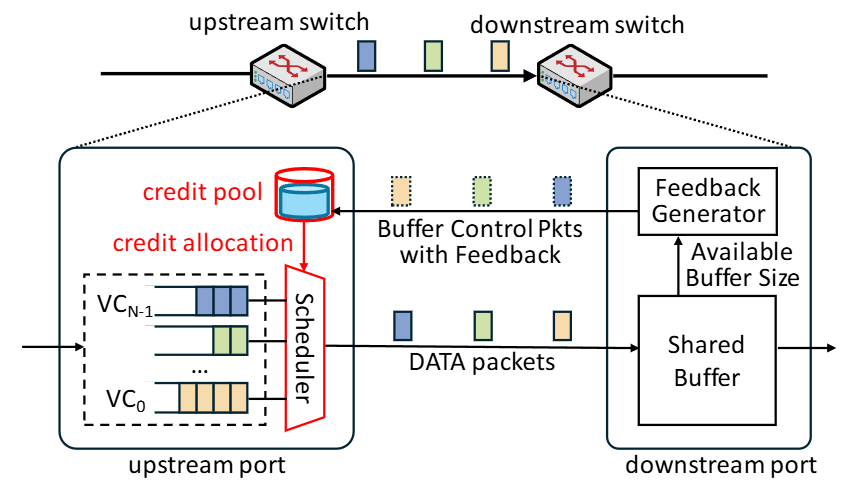
InfiniFlow introduces Upstream Allocates Buffer for Downstream (UABD). For each link, the upstream port maintains a shared credit pool representing the available buffer space at the downstream port. The upstream scheduler allocates credits to VCs when packets are transmitted, enabling immediate buffer allocation without waiting for a separate downstream allocation procedure.
(3) Demand-aware per-VC buffer usage control
Buffer sharing alone can allow congested VCs to consume excessive credits. InfiniFlow therefore introduces the Buffer Usage Control Protocol (BUCP), which dynamically adjusts a per-VC credit threshold according to real-time downstream backlog. This allows each VC to receive enough credits for its actual transmission demand while preventing throttled VCs from monopolizing the shared buffer. A locking mechanism further ensures that the effect of one threshold adjustment takes place before another adjustment begins, reducing rate oscillations.
Evaluation
The authors implement InfiniFlow on a Xilinx Alveo U280 FPGA and use NS-3 simulations for larger-scale evaluation.
(1) VC Scalability
For a 64-port switch with 100 Gbps links and 40 MB of on-chip memory, InfiniFlow supports 16,384 VCs using 401 KB of on-chip memory per port. Under the same setting, CBFC and PFC support only 32 and 16 VCs, respectively, giving InfiniFlow 512× and 1024× higher VC scalability. The FPGA prototype also sustains throughput close to the 100 Gbps line rate.
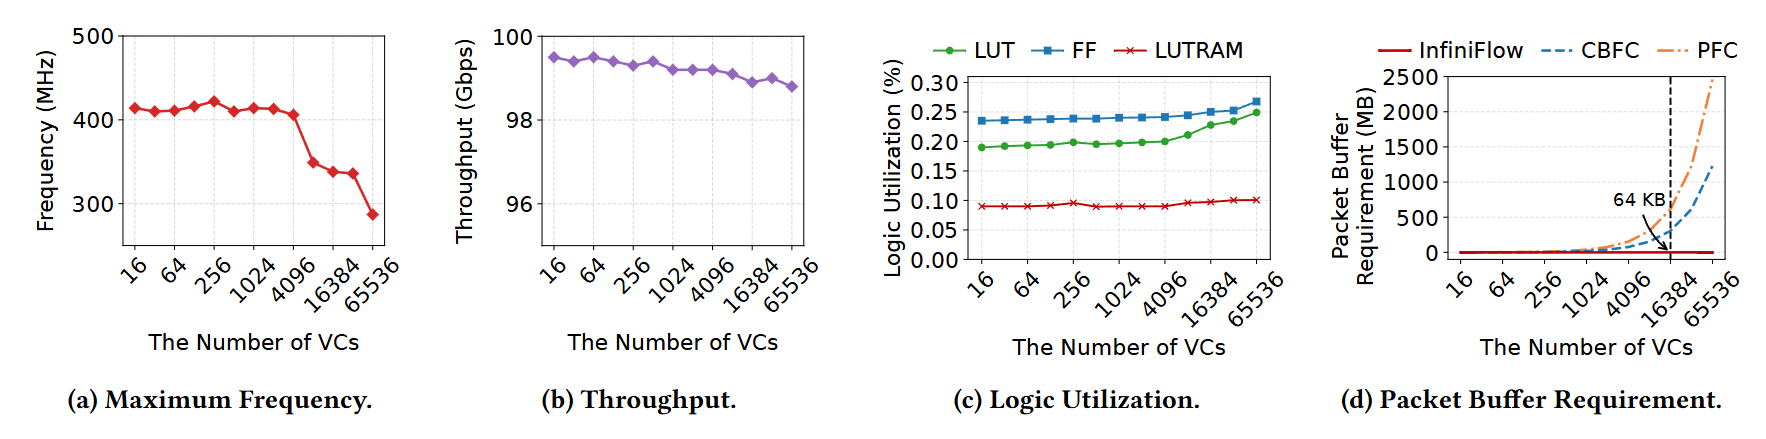
In a 1024-host simulation, approximately 3× per-hop BDP of buffering per port is sufficient for InfiniFlow to approach ideal performance even at 80% load intensity.
(2) Large-Scale Network Performance
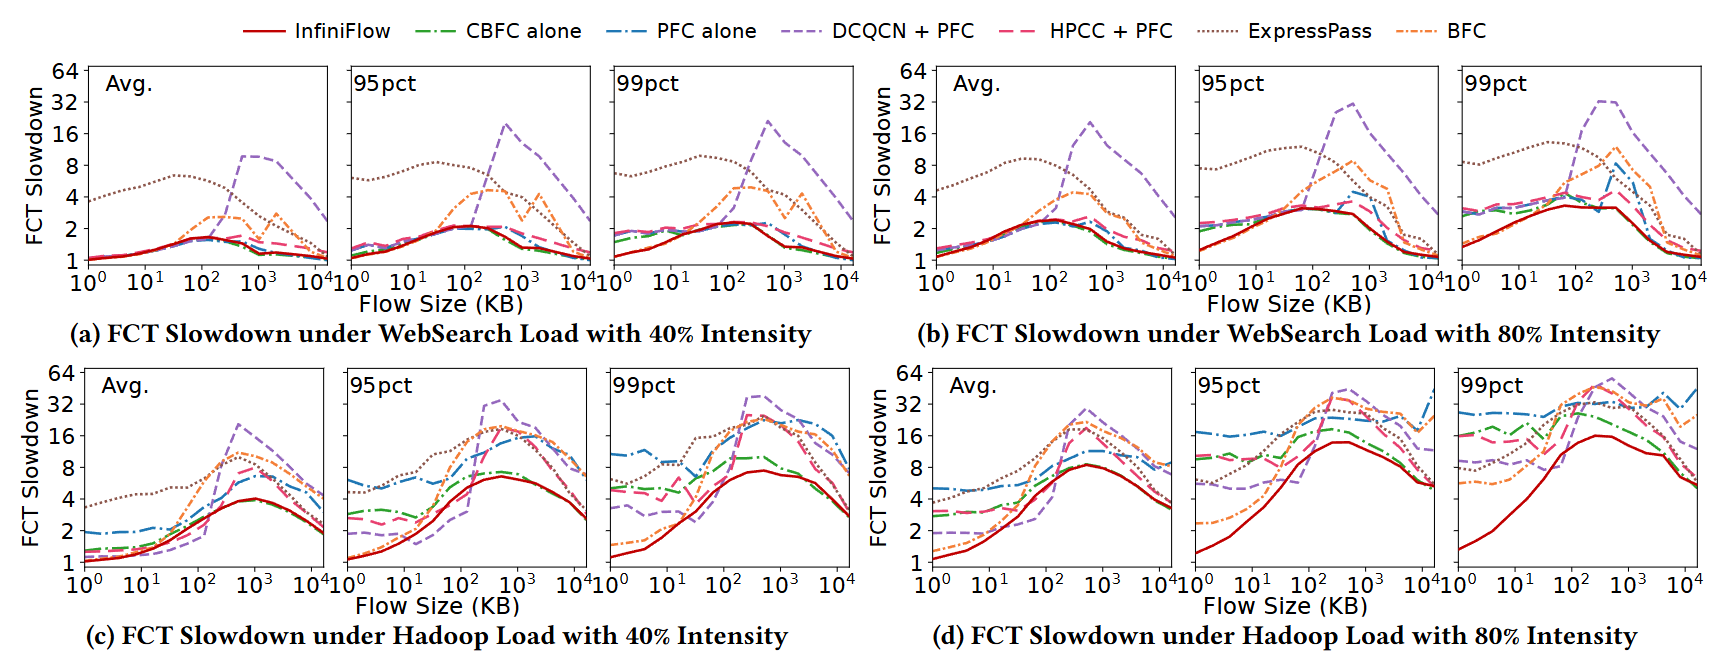
The paper evaluates InfiniFlow on a 1024-host leaf-spine topology using realistic WebSearch and Hadoop workloads and compares it with PFC, CBFC, BFC, DCQCN, HPCC, and ExpressPass. Across most scenarios, InfiniFlow achieves low tail FCT for short flows, with its advantage becoming more pronounced under heavy load and the Hadoop workload. It also maintains low average FCT for long flows across most settings.
Q&A
Q1: Does your scheduler assume a fixed packet size, or can it handle variable packet sizes?
A1: It does not require a fixed packet size. Before sending a packet, the scheduler deducts credits from the credit pool according to the actual packet length, so packets of different sizes can be handled. The credit pool is maintained in bytes rather than packets. The presentation used packets only for clarity. The scheduling condition in the paper also checks whether the available credit pool can cover the actual size of the head packet.
Q2: If there are multiple upstream ports, do they have separate schedulers, and how do they share the buffer?
A2: In the current design, different ports of the same switch do not share the buffer. Buffer sharing in InfiniFlow is limited to each individual port, so buffer usage is separated across ports. Sharing buffers across multiple ports is considered future work.
Personal thoughts
The most interesting aspect of InfiniFlow is that it does not simply provision more independent buffers to support more VCs. Instead, it revisits the fundamental buffer requirement of lossless flow control. By recognizing that all VCs on a port share a physical link with bounded aggregate capacity, InfiniFlow replaces per-VC packet-buffer reservation with per-port sharing and uses UABD and BUCP to control how individual VCs consume the shared resource. This breaks the traditional linear relationship between packet-buffer requirements and VC scalability and makes fine-grained traffic isolation much more practical.
However, InfiniFlow does not make the entire on-chip memory footprint independent of the VC count. Although packet-buffer requirements are largely decoupled from the number of VCs, per-VC metadata still grows linearly. In addition, InfiniFlow still requires buffering proportional to the per-hop BDP. The paper notes that future datacenter networks with higher link rates or longer links may eventually push the per-hop BDP beyond practical buffer budgets, motivating BDP-independent lossless flow control as a future direction.