Keynote: All Models Are Wrong — Some Are Useful, Some Are Harmful
Title : All Models Are Wrong — Some Are Useful, Some Are Harmful
Speaker : Walter Willinger (Northwestern University / University of Oregon)
Scribe : Xing Fang (Xiamen University)
Introduction
At SIGCOMM 2026, Walter Willinger received the ACM SIGCOMM Award for lifetime contributions and delivered a keynote titled “All Models Are Wrong — Some Are Useful, Some Are Harmful: Perspectives from a 30 Year-Long Journey in Measuring and Modeling the Internet.” The talk was organized around George E. P. Box’s classic aphorism: models need not be perfect, but they must be useful.
Willinger emphasized that the question worth answering is not whether a model is wrong—every model is an approximation of reality. What matters is whether it is a reasonable approximation of the real system. If it is, what new insights does it reveal? If it is not, can we recognize its “false look of truth” and identify where it has become too wrong to be of value?
Through four exhibits, he discussed self-similar traffic, multifractal address structure, scale-free router topology, and AI models for networking problems. The first two examples show that imperfect models can still help us understand the stable mechanisms behind real systems; the latter two show how models can become useless or even harmful because of flawed data, flawed abstractions, or shortcut learning.
From Probability Theory to Networking Research
Willinger’s background is not in traditional computer networking. His doctoral work was on stochastic processes and probability theory, and he never received systematic training in computer science or networking. Only after joining Bellcore in 1986 did he gradually move into network measurement and Internet modeling.
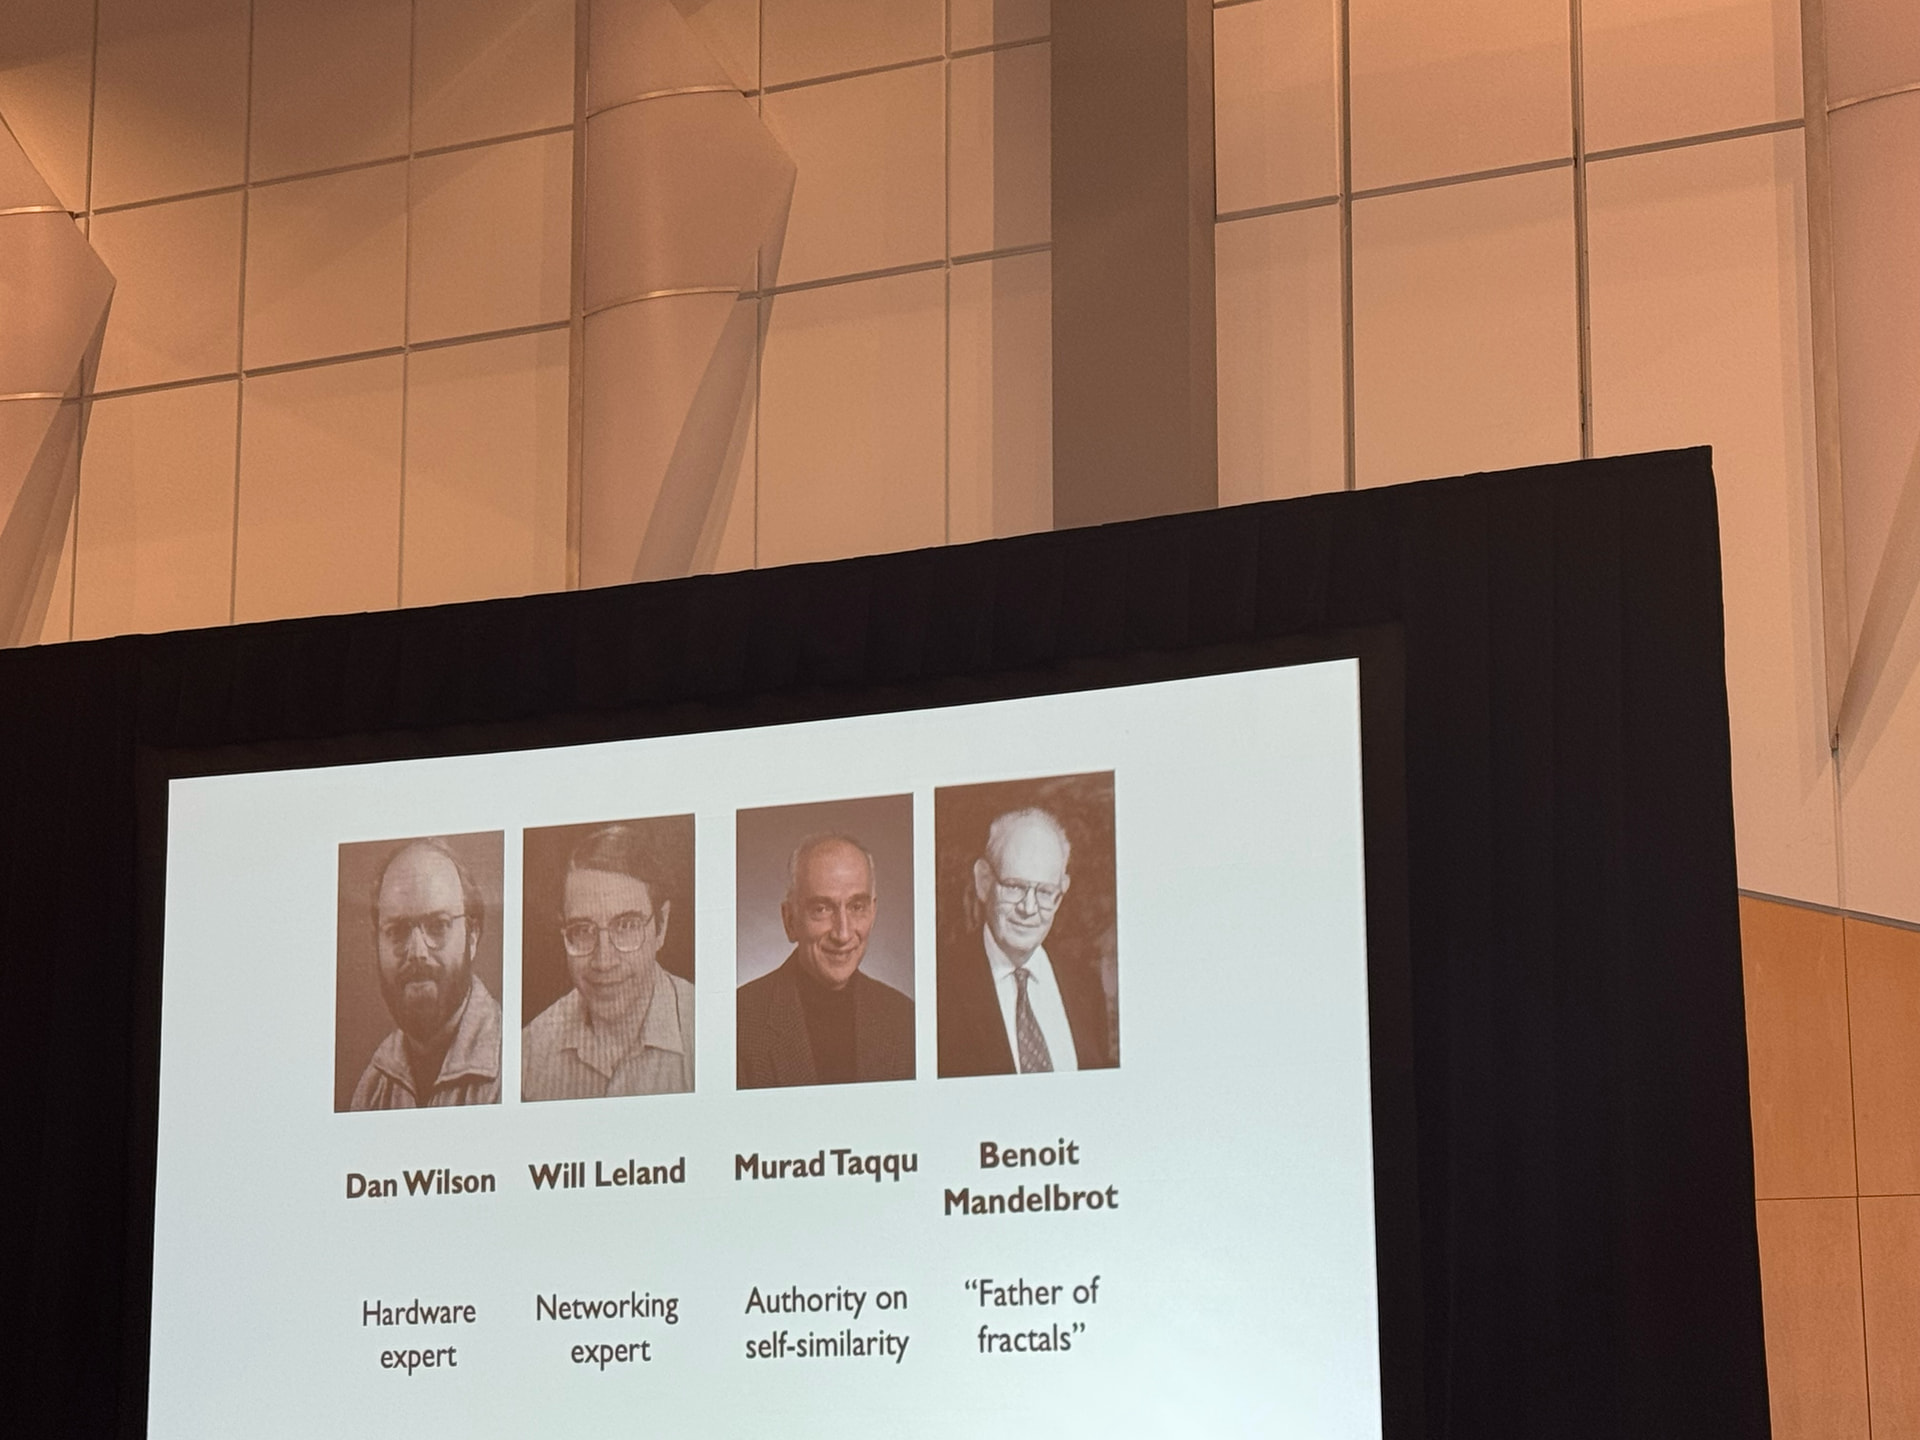
There, he began collaborating with Dan Wilson, Will Leland, and Murad Taqqu. Dan Wilson provided high-quality measurement data, Will Leland brought networking expertise, and Murad Taqqu was a leading authority on self-similarity. Later, Benoit Mandelbrot’s work helped them understand these scaling phenomena more deeply.
This experience also carries an implicit theme of the whole talk: there is no single path into networking research; what matters is whether one can connect knowledge from different fields to real networking problems.
George Box: The Goal of a Model Is Utility, Not Perfection
Willinger stressed that Box’s original intent is stricter than the commonly quoted “all models are wrong, but some are useful”: the goal of a model is not to be perfect, but to provide utility.
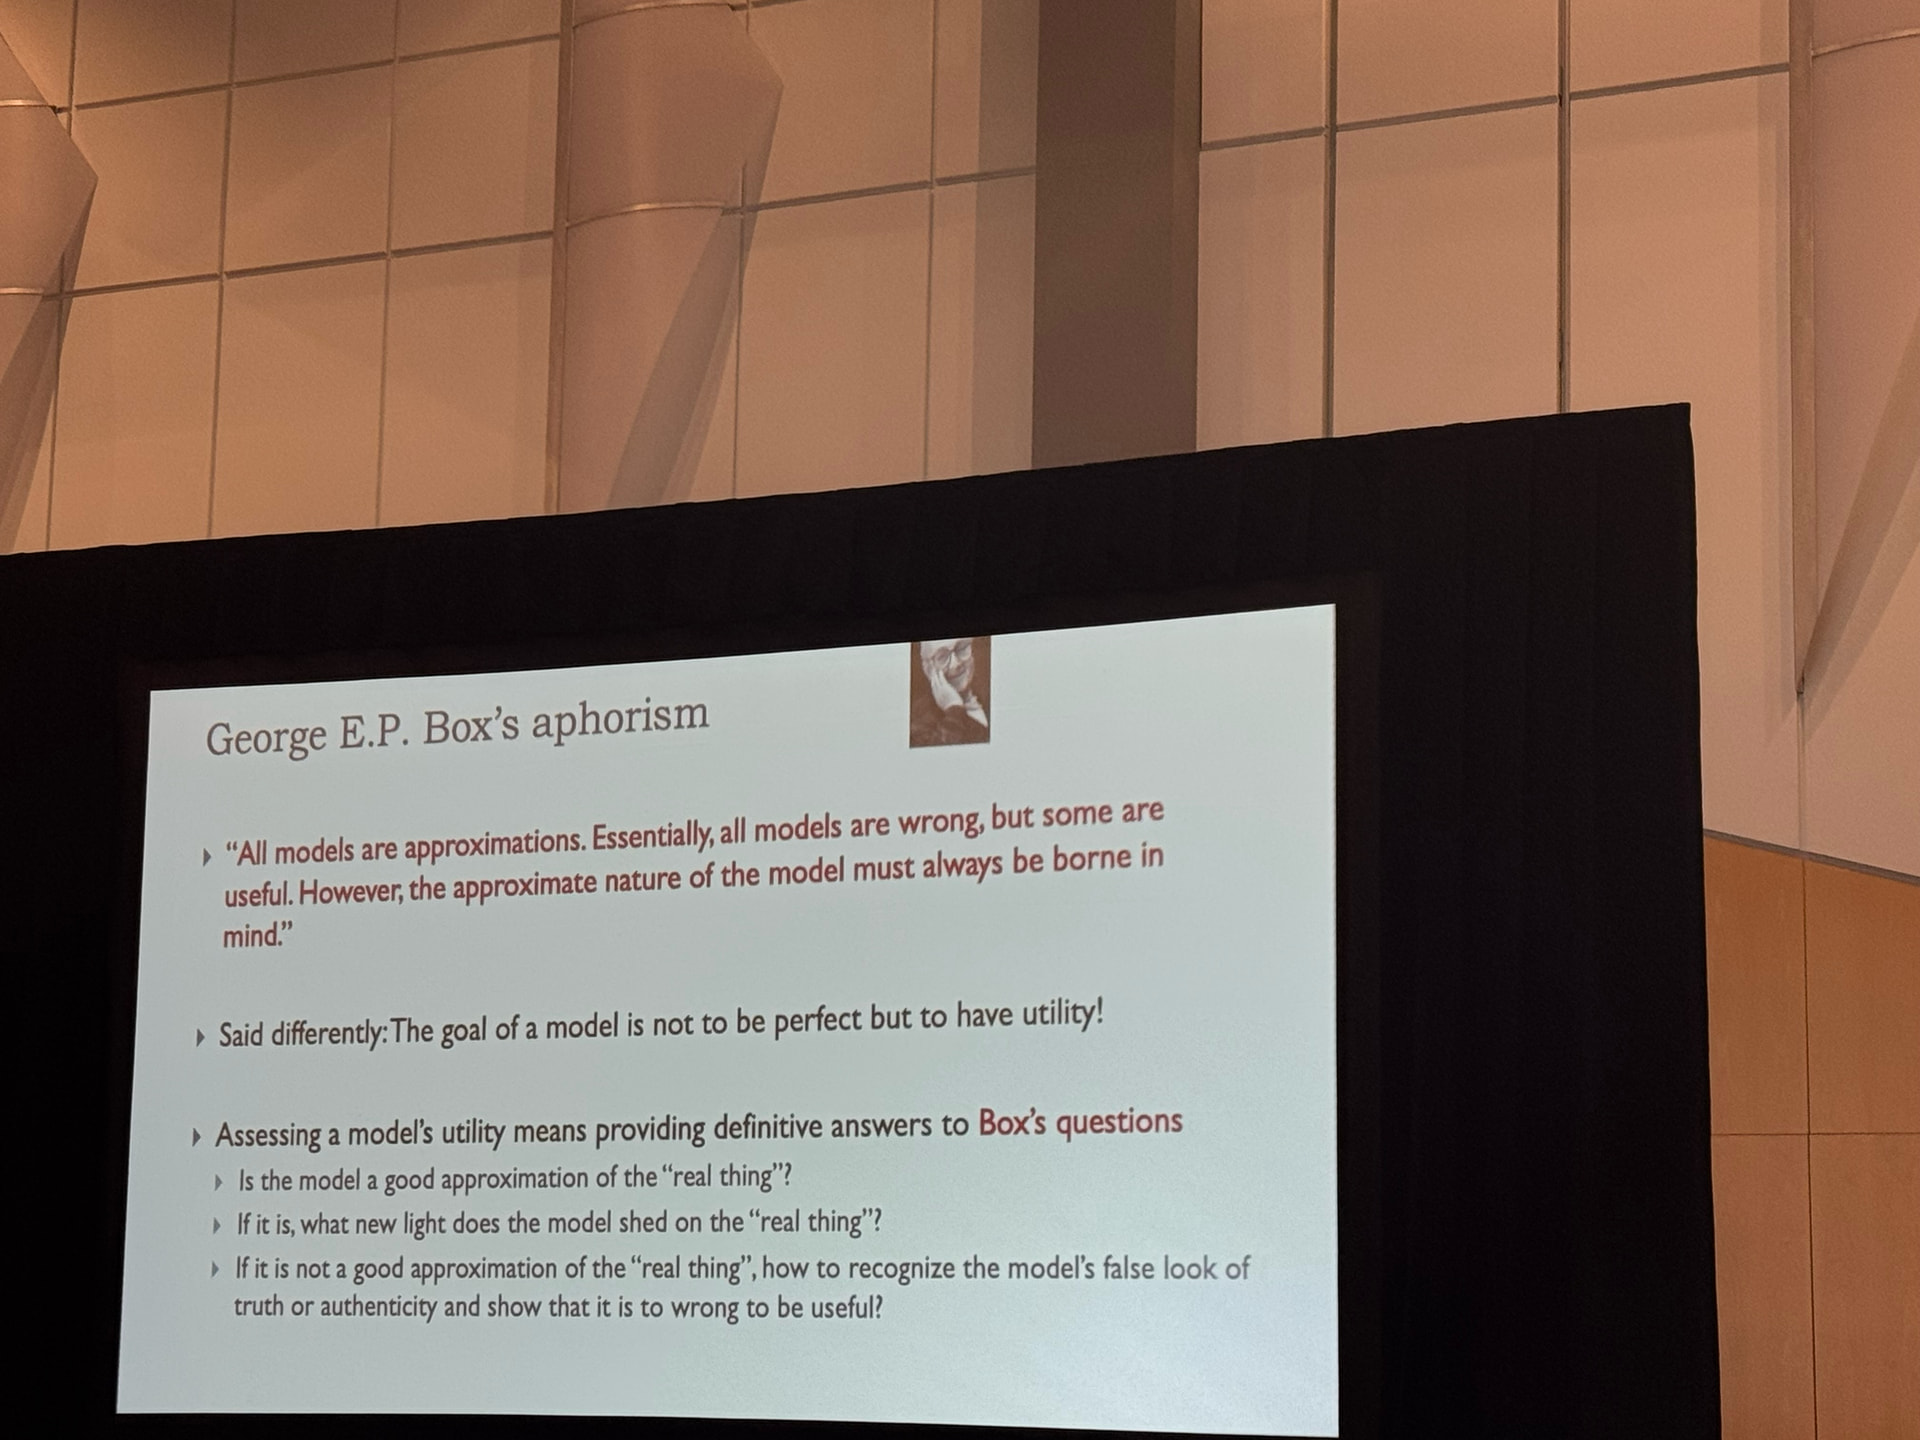
Assessing a model’s utility requires definitive answers to at least three questions:
-
Is the model a reasonable approximation of the “real thing”?
-
If it is, what new light does it shed on the real thing?
-
If it is not, can we recognize its “false look of truth” and show that it is too wrong to be useful?
The four exhibits that follow are, in essence, repeated attempts to answer these questions.
Exhibit I: Self-Similar Traffic — Wrong but Useful
Early communication network research followed the intuition of Poisson or Markovian traffic models: when many independent traffic sources are aggregated, random fluctuations should average out, and traffic should look smoother at longer time scales.
Long-term measurements of real Ethernet traffic by Willinger and his collaborators told a different story: from milliseconds and seconds to minutes and beyond, traffic retained pronounced burstiness and exhibited self-similarity and long-range dependence. In 1993, they published the classic paper “On the Self-Similar Nature of Ethernet Traffic,” which later received the SIGCOMM Test-of-Time Award.
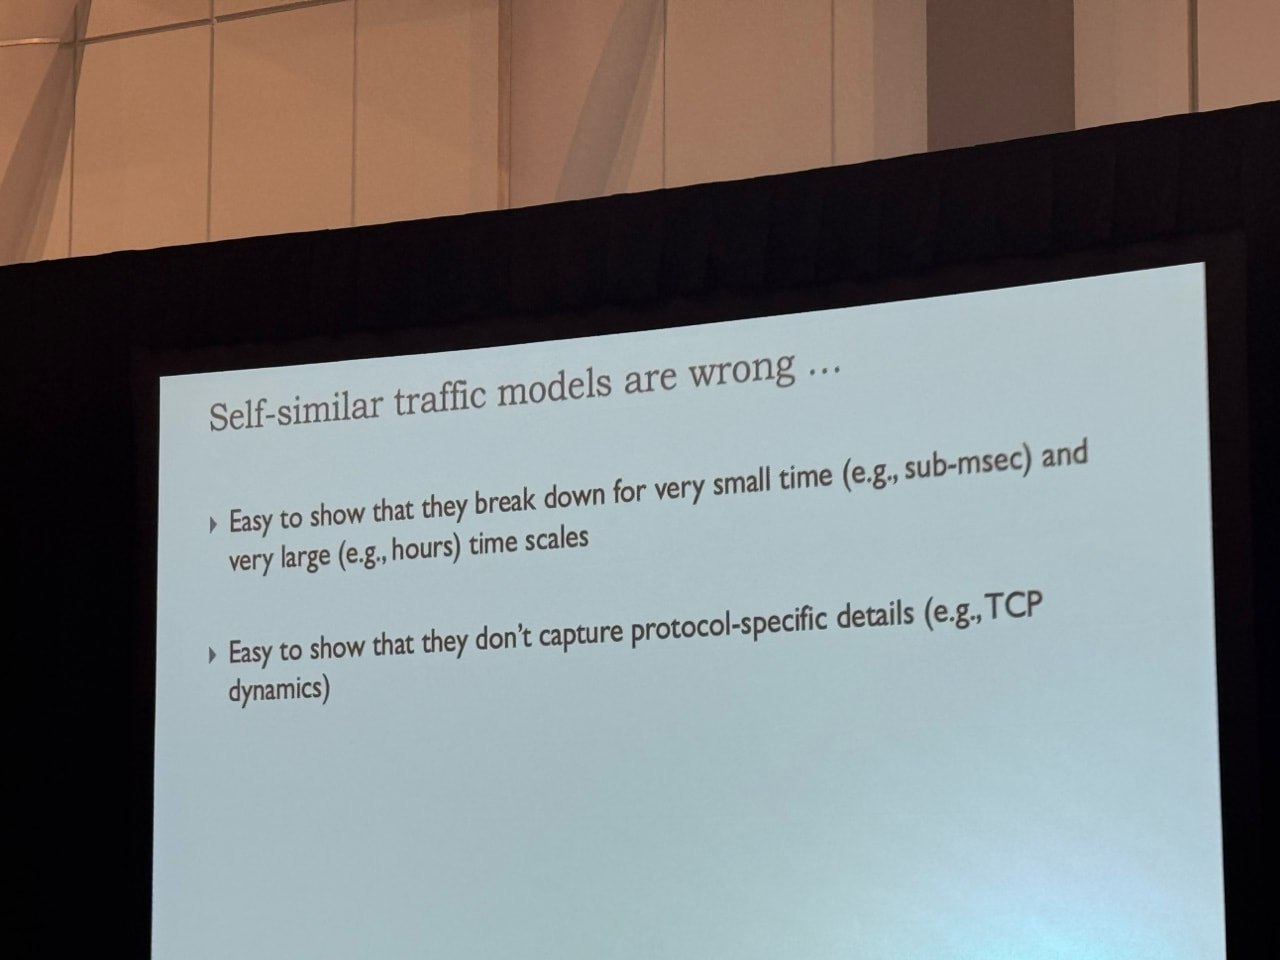
Willinger never treated the self-similar model as the “correct” model, though. It breaks down at very small and very large time scales and does not capture protocol-specific details such as TCP dynamics. It remains wrong. The real question is: why is it useful?
From Descriptive Models to Engineering Explanations
Willinger summarized the research process as a three-stage data-to-model-to-utility workflow:
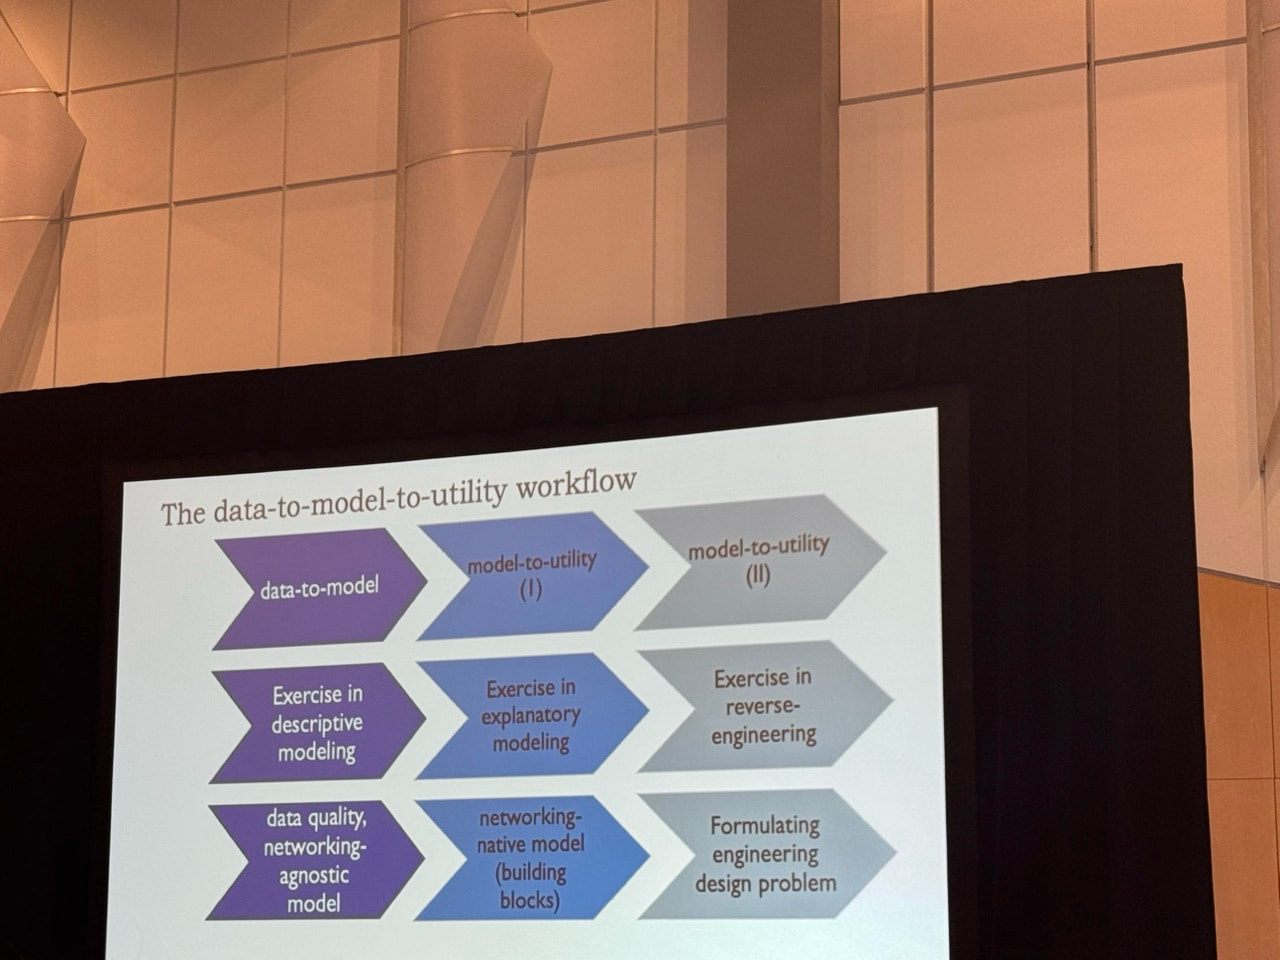
data-to-model → model-to-utility (I) → model-to-utility (II)
The first stage identifies stable statistical structure in high-quality data; the second builds networking-native explanations; and the third reverse-engineers the underlying engineering design.
For self-similar traffic, the key building blocks are flows and the persistent mice-elephant property of Internet traffic. This raised the next question: why does Internet traffic have mice and elephants?
The answer ultimately traces back to human consumption. Humans process information at a very limited rate and are sensitive to latency, so Internet applications naturally generate a large number of quickly consumable “mice”—titles, abstracts, thumbnails—and a small number of bulky “elephants,” such as long-form content and videos. Application developers never deliberately engineer self-similarity, but by adapting to how humans consume information, their design choices end up producing self-similar structure in aggregate traffic.
The value of the model, therefore, lies not in perfectly reproducing packet-level behavior, but in revealing a stable mechanism that emerges from real engineering design.
Willinger also connected this insight to the present: as AI-generated or bot traffic grows, the key question is whether this information still serves human consumption or is shifting toward agent-to-agent consumption. If the latter becomes dominant, traditional traffic invariants may change as well.
Exhibit II: Multifractal Address Structure — From Phenomenon to Design
The second exhibit moved from the time domain to spatial structure. One can take the IPv4 source addresses observed in a packet trace and analyze their distribution at different prefix scales (/8, /12, /16, /20, /24). Related work found that the observed address structure exhibits pronounced multifractal behavior.
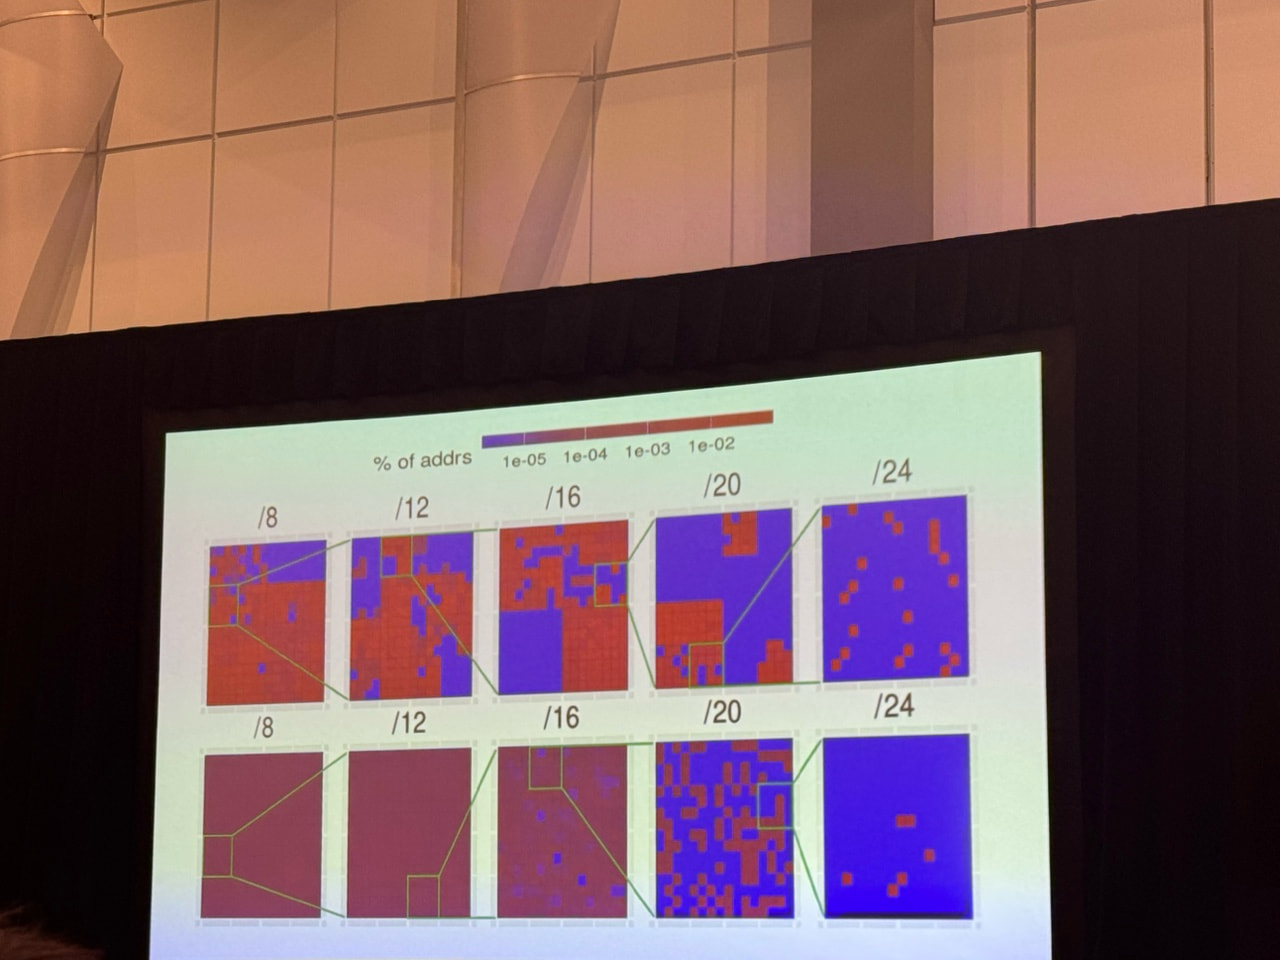
Like the self-similar model, the multifractal model is clearly imperfect: it breaks down at very short and very long prefix scales, and it does not directly capture real-world details such as reserved address space, renumbering, or dynamic assignment.
It is still useful, however, because the multifractal structure is not an accidental artifact of the Internet but the outward manifestation of address-allocation engineering design. Allocation policies have to balance two goals:
-
improving address-space utilization;
-
reducing address fragmentation.
The early Internet pioneers did not have multifractal scaling in mind when they shaped allocation policies, but the policies they created to support the scalability and stability of the Internet produced highly variable address block sizes, and this structure ultimately shows up as multifractal scaling.
This case validated the same path once again:
measurement → descriptive structure → networking-native explanation → engineering design
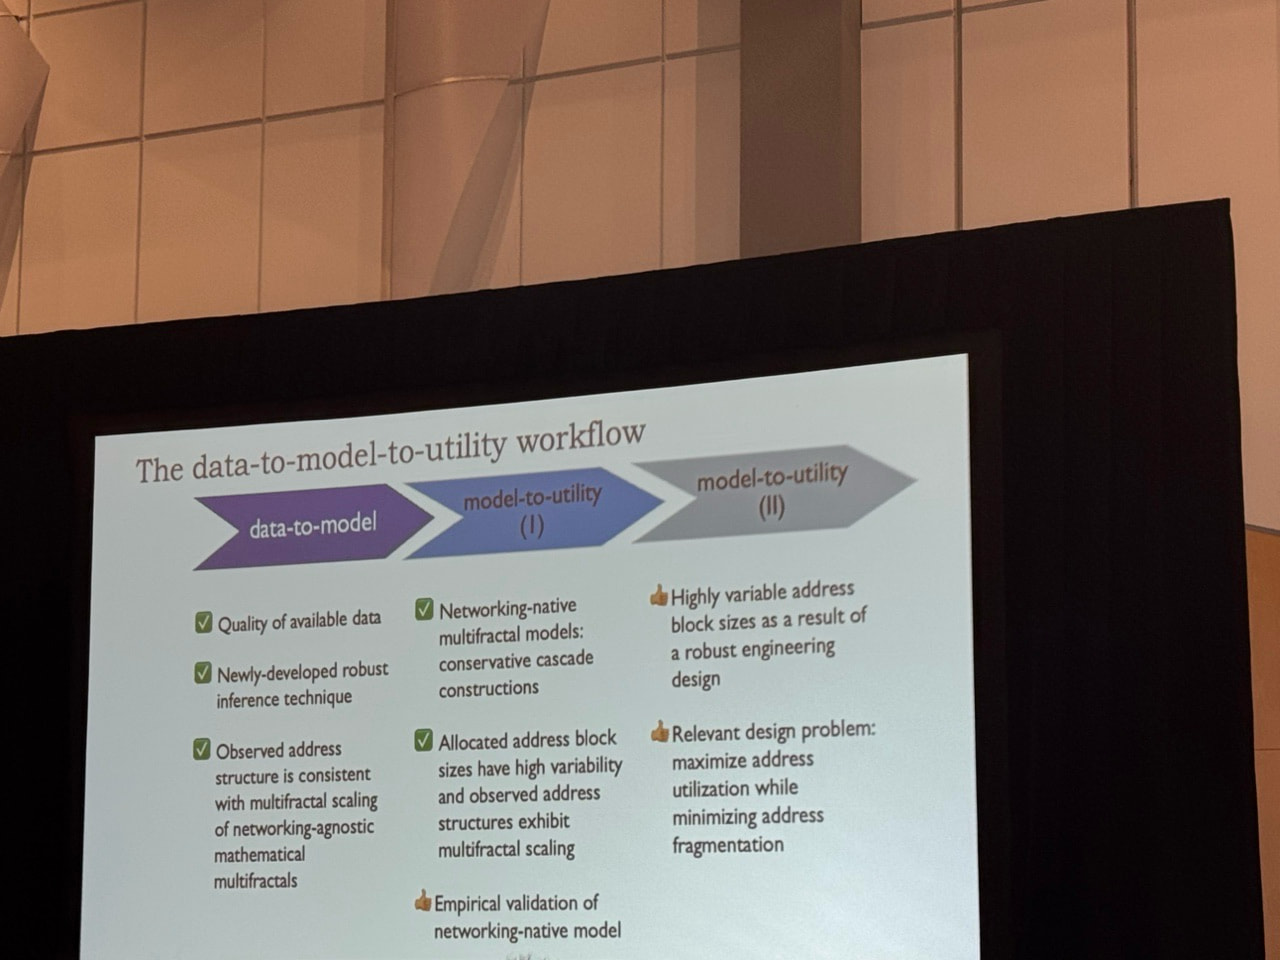
Once the underlying design is understood, one can also reason forward—for example, asking whether IPv6 would exhibit a similar structure under comparable allocation policies, and what would change if IPv6 allocation/assignment policies were modified.
Exhibit III: The Scale-Free Internet — Wrong and Harmful
The third exhibit turned to the well-known controversy over scale-free modeling of the Internet router topology. Willinger characterized these models as “wrong but deceitful.”
In the late 1990s, several topology studies observed power-law-like node-degree distributions from traceroute measurements and concluded that the Internet is scale-free. Under this interpretation, the network forms hubs through preferential attachment, making it robust to random failures yet fragile to attacks on high-degree hubs—the Internet’s “Achilles’ heel.”
Willinger raised two fundamental objections.
First, traceroute measurements alone cannot reliably infer the true node-degree distribution. If the input data are already biased, then however elegant the downstream analysis, it is simply “garbage in, garbage out.”
Second, and more importantly:
Willinger pointed out that ISPs do not design their networks by randomly connecting routers.
A real router topology is the product of serious engineering, shaped by router and link costs, customer demand, router capacity, link speed, traffic demand, and robustness constraints. Even if a random graph matches the Internet on some degree statistics, that does not mean it explains why the Internet looks the way it does.
The danger of the scale-free model, therefore, is not merely that it is imprecise, but that it has a false look of truth: it compresses a complex engineered system into a graph topology and creates the illusion that “details don’t matter.”
Borrowing T. H. Huxley’s words, Willinger described the fate of such models as “the slaying of a beautiful hypothesis by ugly facts.”
HOT: Understanding Topology from First Principles
As an alternative, Willinger recalled his work with John Doyle, Lun Li, David Alderson, and others, and introduced Heuristically Optimal Topology (HOT) models.
Rather than starting from random growth, HOT treats the router topology as the outcome of constrained optimization: the network must efficiently carry expected traffic demand while satisfying economic, technological, and robustness constraints.
Such models remain simplifications and are still “wrong”; but they are networking-native models, because they preserve the real engineering logic that determines the router topology.
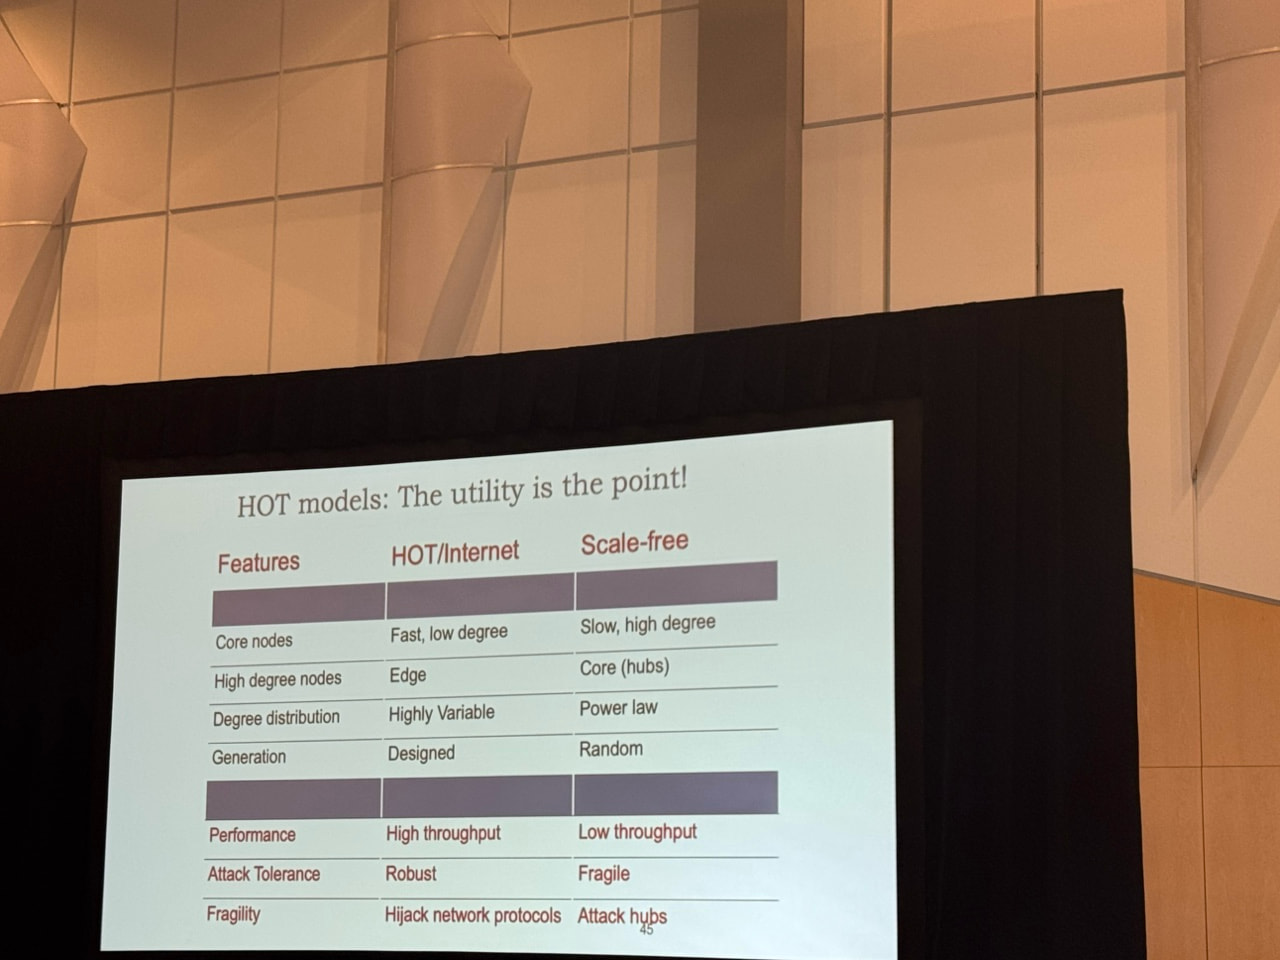
The talk then contrasted HOT/Internet with the scale-free model: in HOT/Internet, core nodes are typically fast and low-degree, while high-degree nodes sit mostly at the edge; the scale-free model puts high-degree hubs in the core. Even though both exhibit highly variable degree distributions, their performance, robustness, and fragility differ completely.
Lessons from the First Three Exhibits
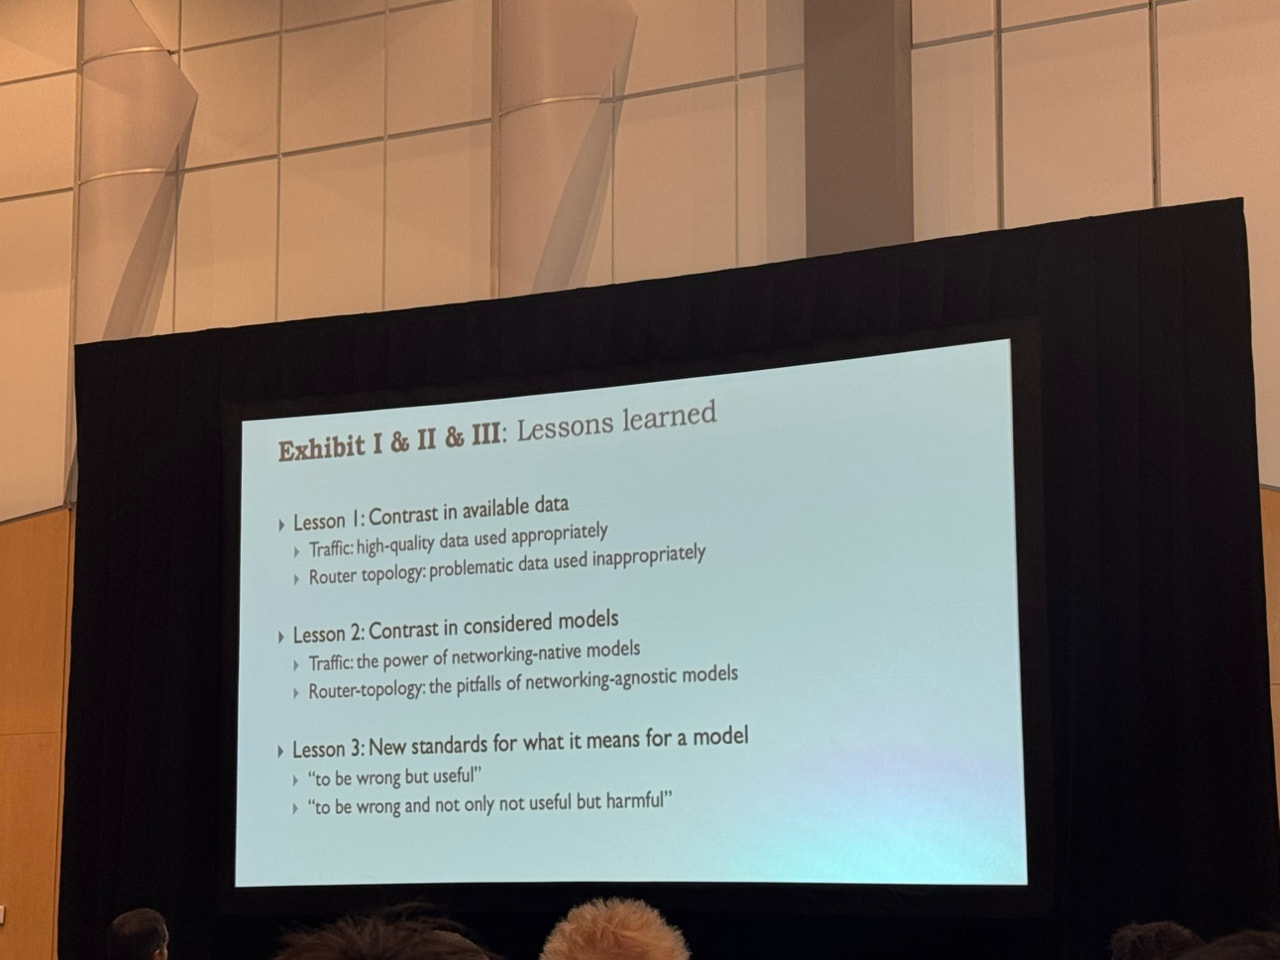
Willinger distilled three lessons from the first three exhibits.
First, data matters: traffic modeling was built on high-quality data, whereas the trouble with scale-free topology began with the measurements themselves.
Second, networking-native models matter: the successes of traffic modeling and HOT came from modeling network mechanisms, while networking-agnostic abstractions can be statistically elegant yet lose their explanatory power.
Third, “wrong but useful” needs to be understood more rigorously. Models can be imperfect, but researchers must know what their models ignore; when flawed data and flawed abstractions further produce misleading conclusions, a model turns from “wrong” into something harmful.
Networking Research in Industry
Willinger also spoke about the realities of doing research in industry. Industry has the most realistic data and operational experience, yet researchers there are often told:
“Sorry, but you can’t publish this work!”
The reasons may be proprietary data, sensitive topics, or simply the organization’s unwillingness to disclose.
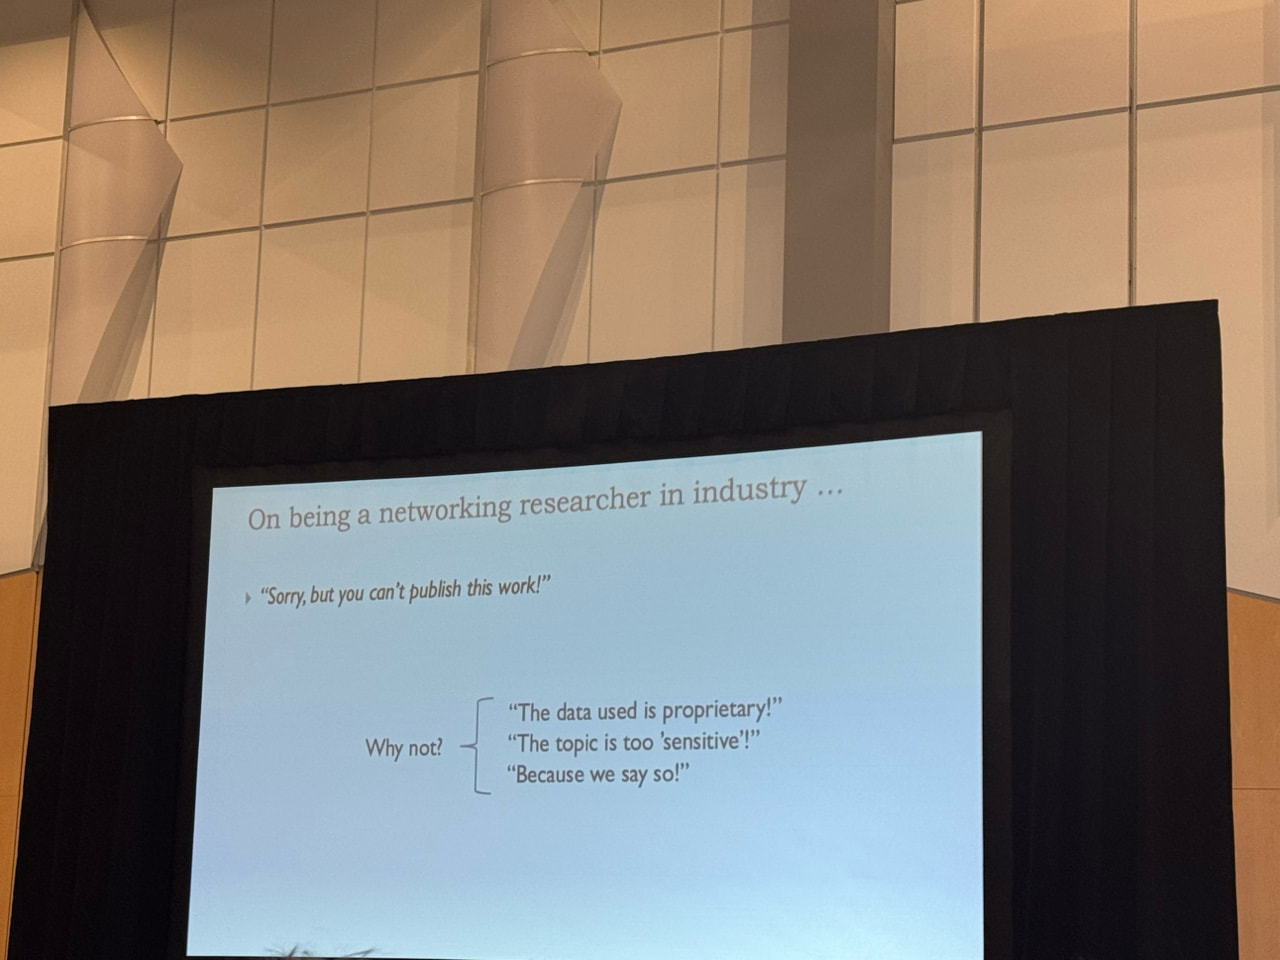
This taught him that the most valuable data in networking research is often hard to obtain or not public, while easily available data may not be enough to answer the questions that really matter.
Exhibit IV: AI for Networking — When High Accuracy Is Meaningless
The final exhibit applied the same criteria to AI/ML. Willinger observed that since around 2020, AI-for-networking papers have proliferated, many following a similar pipeline: recast the networking problem as generic ML input, train a black-box model, and demonstrate effectiveness with accuracy, F1, and similar metrics.
The question is: what have these models actually learned?
A Near-Perfect VPN Classifier
Willinger used encrypted traffic classification as an example. The task is to distinguish VPN from non-VPN traffic using the public ISCXVPN2016 dataset. Prior work trained a 1D CNN with about 6M parameters, achieving an F1-score close to 1.0.
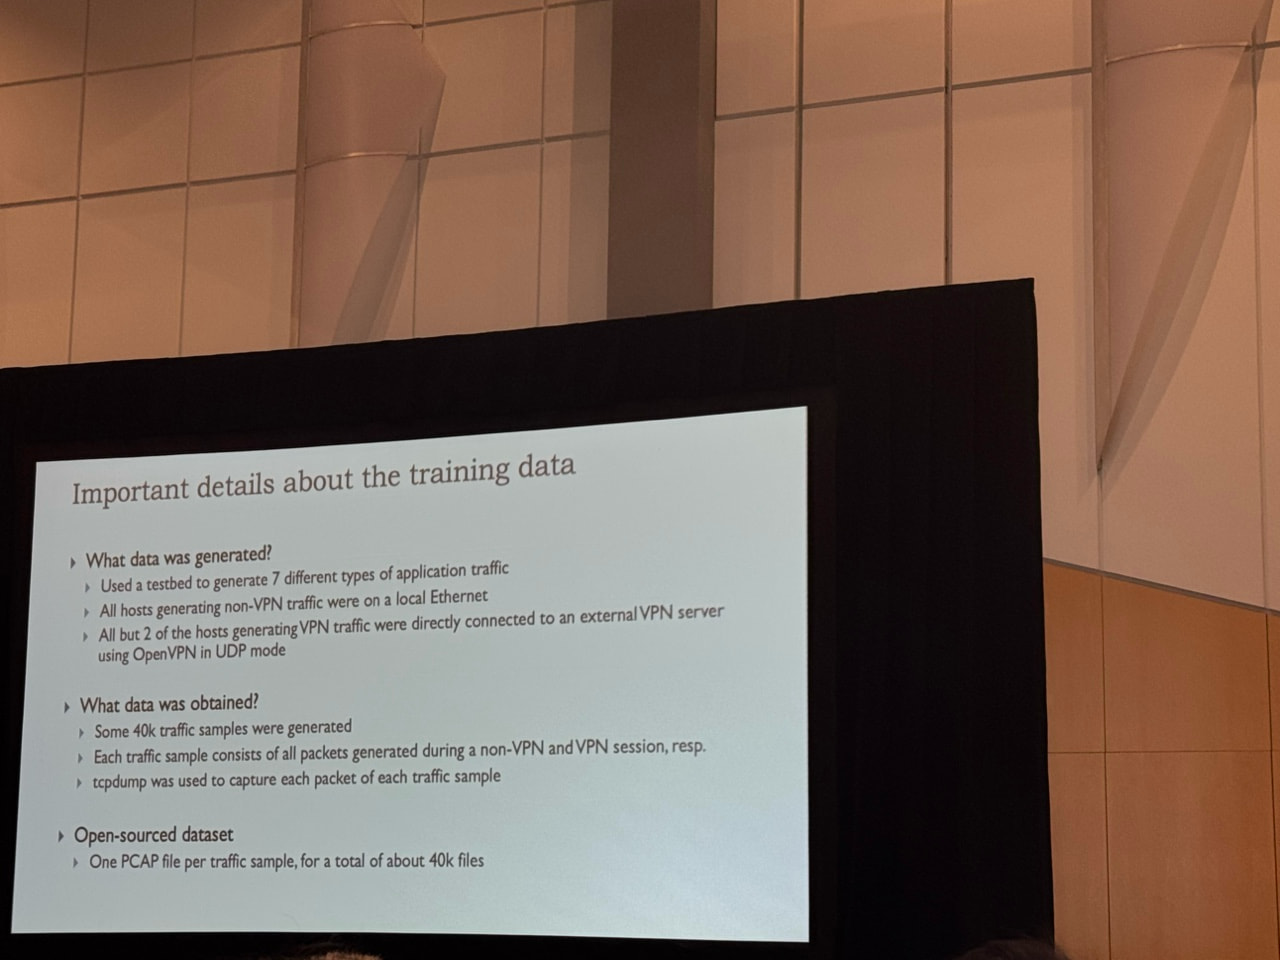
A closer look at the data-generation process, however, reveals that the non-VPN traffic was captured on a local Ethernet, while most of the VPN traffic passed through an external VPN server, leaving a clear artifact in packet encapsulation between the two classes.
Using packet format alone, a networking expert can reach 100% accuracy with a tiny decision tree.
Further analysis of the black-box CNN showed that it never learned the semantic difference between VPN and non-VPN traffic; it was exploiting the dataset artifact—shortcut learning. Once real-world traffic no longer satisfies the same data-generation conditions, the model collapses.
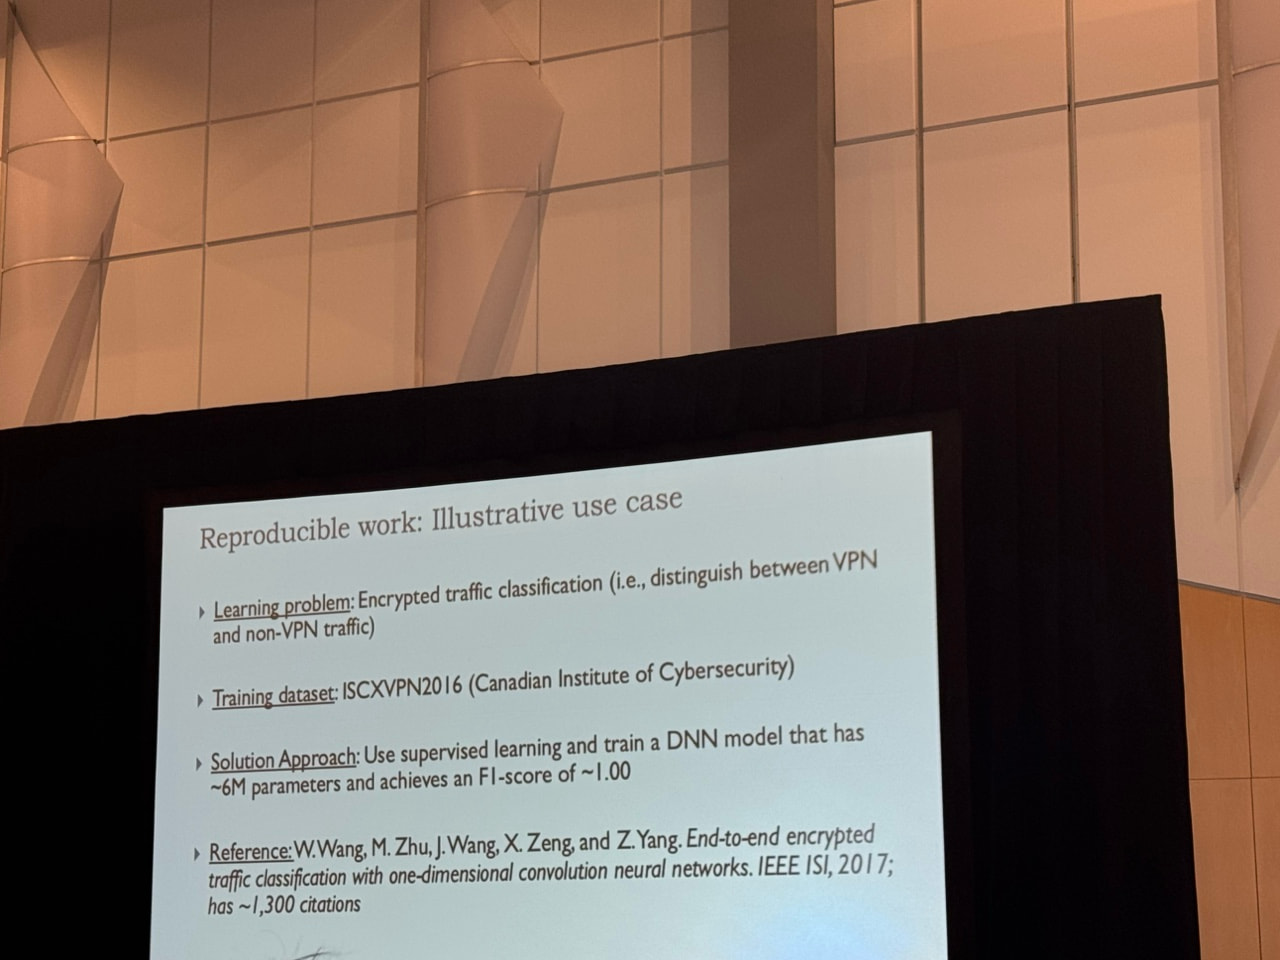
This case shows that high benchmark performance does not equal real utility.
Willinger stressed again that understanding training data means knowing not just how many samples it has, but how the data was generated, captured, collected, and used. No matter how complex the model, if the input is garbage, it is still “garbage in, garbage out.”
Network Foundation Models: A Bigger Black Box
Willinger then pushed the question to Network Foundation Models (NFMs).
Foundation models learn embeddings and latent representations through lossy compression, so the latent space itself becomes a new “big black box.” Evaluating an NFM cannot stop at downstream task performance; one must also ask:
-
What networking structure is preserved in the latent space?
-
What does self-similar traffic look like in the latent space?
-
Is it just a scaling property, or is flow-level context retained?
-
Is the latent space truly a good approximation of the underlying network?
Willinger framed these questions as a new kind of challenge: “G. E. P. Box meets NFM.”
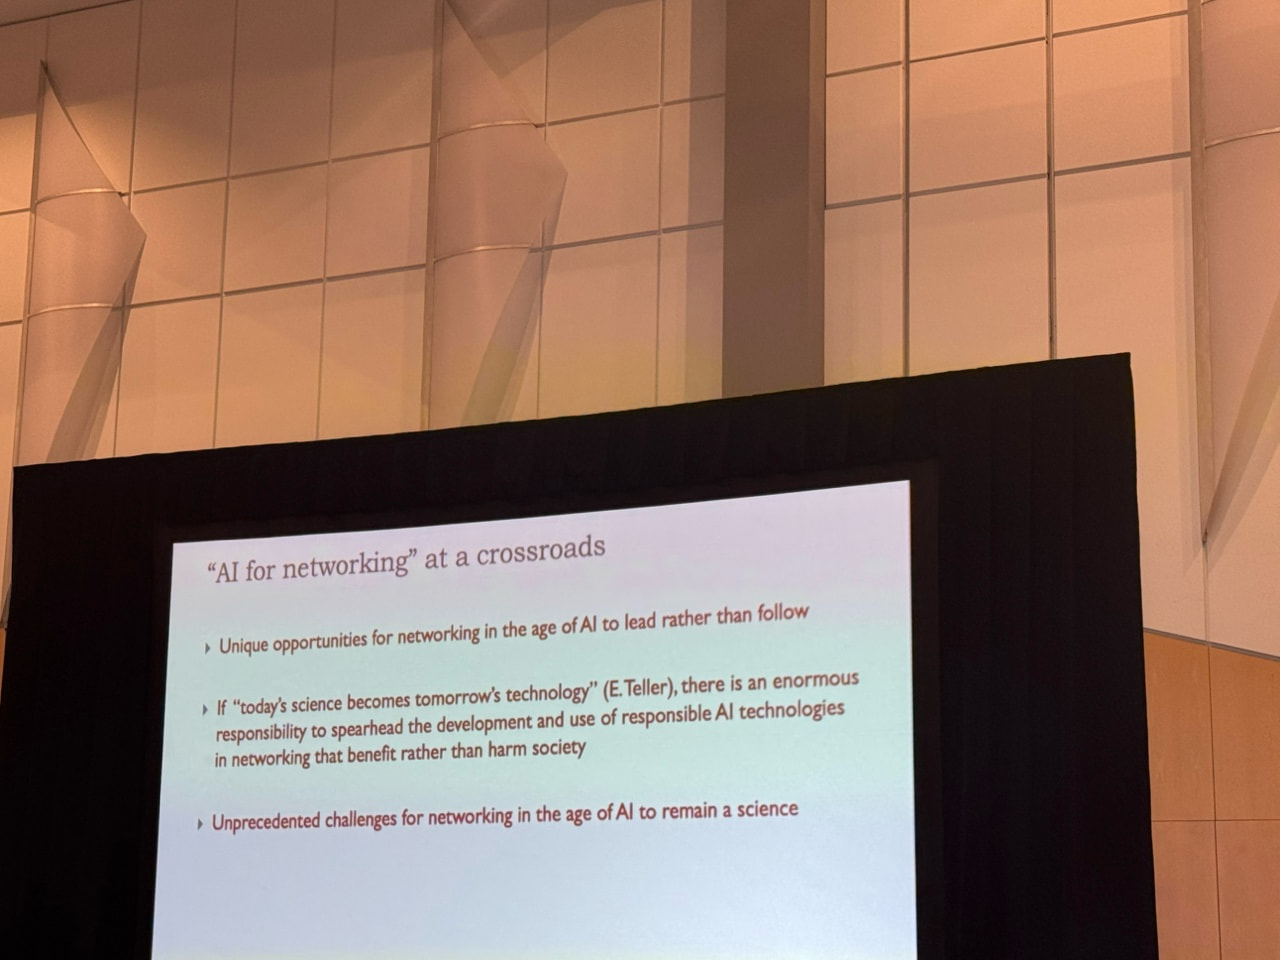
“AI for Networking” at a Crossroads
Toward the end, Willinger described AI for networking as standing at a crossroads.
His message was not “avoid AI,” but that the networking community should not merely follow—it should actively leverage its own domain knowledge:
-
Do not wait for AI to tell us which learned representations deserve trust;
-
Be explicit about how networking differs from other domains;
-
Do not shy away from networking-specific domain knowledge;
-
Push for genuinely networking-native AI models.
On LLMs, Willinger noted that they can be used for mundane, low-risk, or low-stakes tasks, but using them for high-risk, high-stakes decision-making without sufficient understanding is irresponsible. What is needed is not only stronger models, but a genuine science of LLMs that explains why models work, when they fail, and which settings deserve trust.
The Best Thing About Being a Networking Researcher
The final slide returned to collaboration and people.
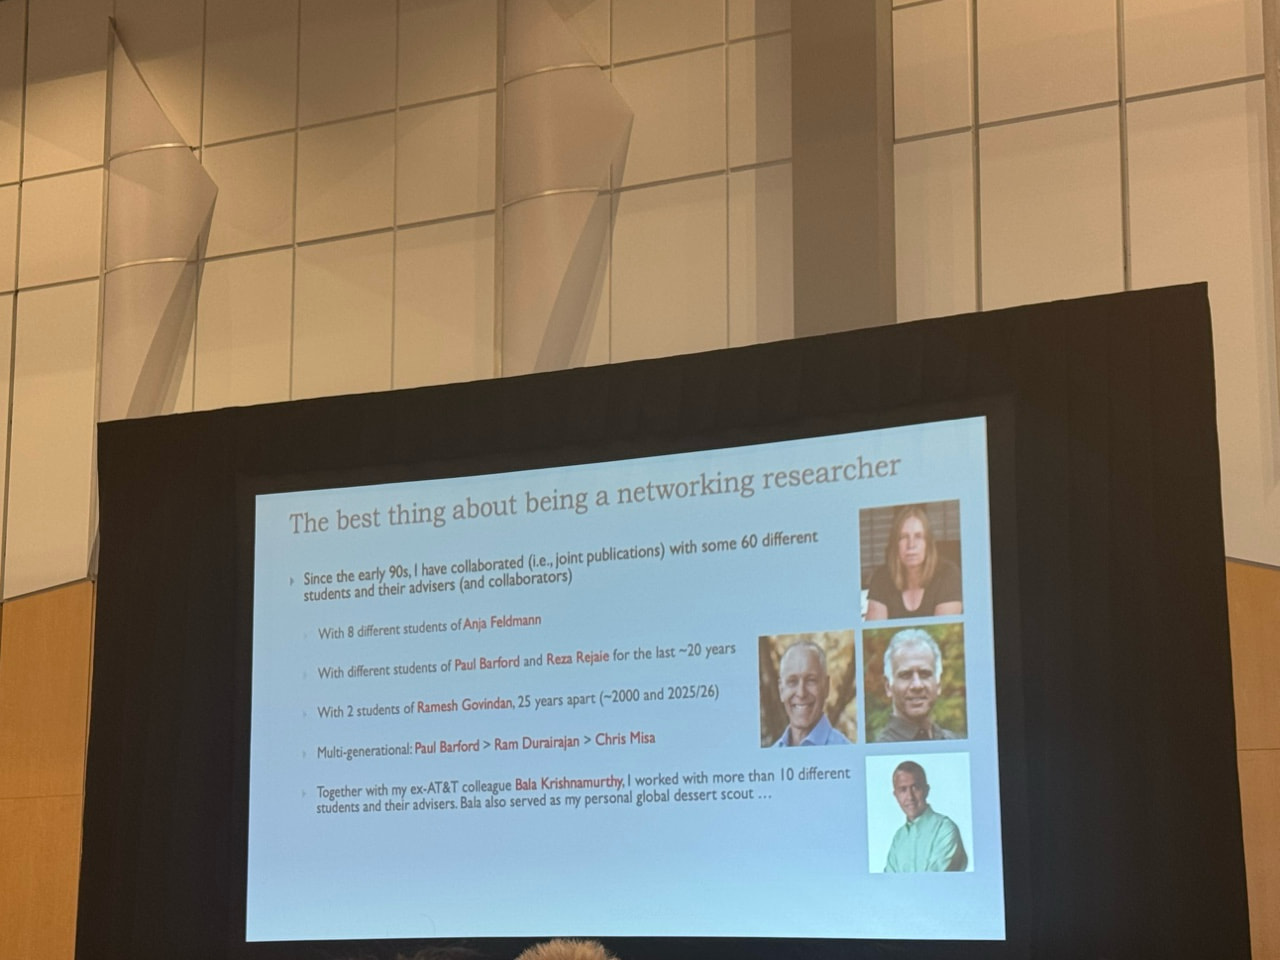
Willinger noted that since the early 1990s, he has co-authored papers with some 60 different students and their advisors and collaborators. Many of these collaborations have lasted a decade or two, forming multi-generational academic lineages such as Paul Barford → Ram Durairajan → Chris Misa.
For someone who started without a traditional networking background, these students, advisors, and collaborators not only did the research together with him, but also helped him fill in his own understanding of the field. He called this long-term collaboration the best part of being a networking researcher.
Questions and Answers
Q1: When deploying AI models in production, how should one balance performance, interpretability, and operability?
A1: Willinger’s position was unambiguous: for low-risk, low-stakes tasks, a certain degree of black box is acceptable; but for high-risk or high-stakes decision-making, if we do not understand how a model works, we should not use it. With foundation models and latent spaces, the truly hard problem is understanding these learned representations, which calls for a more systematic “science of AI/LLMs” so that using models in high-stakes settings rests on scientific ground.
Q2: Will AI agents change the self-similar nature of traffic?
A2: Willinger reduced the question to whether AI agents ultimately organize information for human consumption or for agent consumption. If humans remain the end consumers, the limits of human cognition and information processing still hold, and traffic structure may not change fundamentally; but if agent-to-agent traffic becomes dominant, new patterns may emerge.
Q3: Can new technologies bypass the upper limit of human information processing?
A3: Willinger argued that the upper bound on the human information processing rate is a strong constraint that application design cannot simply remove. A more interesting question for the future is how this hard limit will continue to shape new applications and traffic patterns.
Q4: What practical value do these models actually offer to operators?
A4: Real practical value, he answered, comes from reasoning backward from an empirical phenomenon to the underlying engineering design problem. Once we understand which design produces a given scaling property, we can further ask whether that design matters to operators, applications, or the optimization of future systems.
Q5: Both of your Test-of-Time papers were initially rejected—how should young researchers view rejection?
A5: Willinger noted that both of his representative works that later won SIGCOMM Test-of-Time Awards—self-similar traffic and router topology—were rejected when first submitted. His advice: one rejection does not mean the research is poor. It often reflects factors beyond the researcher’s control, such as community taste and review context. What matters more is judging whether your problem and your evidence still stand—and persisting.
Personal Thoughts
I strongly agree with the keynote’s emphasis on model utility. No model can fully reproduce a real system, so being “wrong” is not itself the problem; the key is whether the approximation serves practical goals. Many networking tools inherently trade off scalability, accuracy, and runtime overhead. As long as the error and the scope of applicability remain under control, sacrificing some accuracy for scalability is generally acceptable in practice.
I also agree with the call for a “science of LLMs.” If LLMs already outperform existing methods on some tasks, the point is not to simply exclude them from important scenarios, but to build adequate safeguards—understanding and constraining their failure modes through verification, systematic testing, and runtime checks, and improving robustness—so that these capabilities can be used more reliably in critical networking tasks.