Title: MonkeyTree: Near-Minimal Congestion for Multi-tenant Training via Migration
Authors: Anton A. Zabreyko, Weiyang Wang, Manya Ghobadi (MIT)
Introduction
This talk studies congestion in multi-tenant AI training clusters, where many large jobs share the same datacenter network. As training workloads scale to tens of thousands or even hundreds of thousands of GPUs, network congestion becomes expensive very quickly: if the fabric cannot keep up, GPU cycles are wasted and training throughput drops. The speaker emphasized that this is not a minor scheduling nuisance, but a central bottleneck for modern training infrastructure.
The main congestion point is the ToR-to-Spine path. When multiple jobs are placed on the same rack, their data-parallel traffic competes for the same uplinks, and the resulting contention can significantly slow down training. Because data-parallel communication dominates the traffic that actually enters the network, the degree of fragmentation in placement directly determines how many flows a rack needs to carry. In other words, fragmentation is not just a placement artifact; it is the root cause of network congestion.
Key idea and contribution
MonkeyTree reframes the problem from routing and scheduling to fragmentation management. Traditional spatial scheduling tries to spread flows across links, while temporal scheduling tries to separate traffic over time. Both can help, but neither removes the root cause: once a rack hosts too many fragmented jobs, contention is still unavoidable. MonkeyTree instead uses migration as a first-class primitive to reduce fragmentation itself.
The system works in three steps. First, it decides whether migration is needed by monitoring the current fragmentation level. Second, it selects which workers to move by solving a sparsity-constrained transportation problem with ILP, aiming to minimize the number of migrations. Third, it chooses how to route the remaining traffic by using bipartite edge coloring, which guarantees path isolation as long as the fragmentation level stays within the uplink capacity of each rack.
The paper’s main ideas can be summarized in four points:
- It identifies fragmentation as the real source of congestion in shared training clusters.
- It introduces migration as a low-cost mechanism to repair fragmented placements.
- It provides a theoretical target, called FIFO placement, that bounds fragmentation to at most 2 per rack.
- It shows that the resulting system can be integrated into existing schedulers such as Slurm or Kubernetes without changing the training framework itself.
MonkeyTree also provides an important system-level guarantee: if each ToR has at least two uplinks, congestion-free states remain reachable regardless of GPU scale. That makes the approach attractive for highly oversubscribed clusters, where full bisection bandwidth would be too expensive. In practice, the controller operates on top of existing orchestration software, uses checkpoint-and-restore to migrate workers, and relies on CPU DRAM plus RDMA rather than disk-based checkpointing.
Evaluation
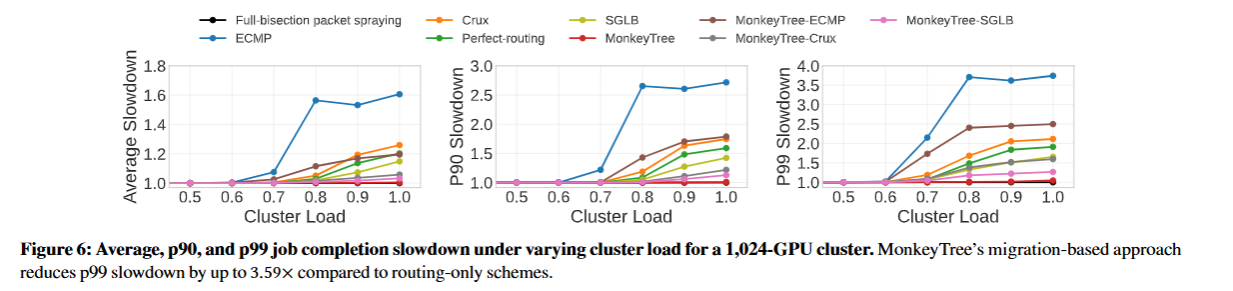
The evaluation is conducted on a simulated 1,024-H200-GPU cluster using realistic workloads drawn from LLaMA and GPT-style training distributions. The authors compare MonkeyTree against several baselines, including ECMP, Crux, Perfect routing, SGLB, and a full-bisection packet-spraying upper bound.
The key result is that MonkeyTree substantially reduces slowdown under load. Figure 6 shows average, 90th-percentile, and 99th-percentile job completion slowdown across different cluster loads. MonkeyTree’s migration-based de-fragmentation improves the tail behavior most strongly: p99 slowdown is up to 3.59x better than routing-only schemes, and even at high load the slowdown stays close to the ideal upper bound.
The overhead is also practical. Most migrations are small, with 85% of them moving only two workers. The ILP controller remains fast enough for the intended scale, with P90 solve time around 4 seconds on a 2k-GPU cluster. That makes the approach look like a real control-plane mechanism rather than a purely theoretical optimization.
Personal thoughts
My main takeaway is that MonkeyTree changes the way congestion should be understood in multi-tenant training. The paper does not treat congestion as a pure routing problem, and it does not assume that simply adding more bandwidth is the only way forward. Instead, it shows that the placement structure of jobs, especially fragmentation, is a key hidden variable behind poor training performance.
I also think the paper is strong because it connects theory, control logic, and evaluation very cleanly. FIFO placement, the two-uplink guarantee, the ILP-based migration controller, and the checkpoint-based implementation all point in the same direction: the system is designed to be both analyzable and deployable. That makes the argument more convincing than a paper that only reports routing gains.
More broadly, MonkeyTree suggests that future AI cluster networking will need to consider placement, migration, routing, and training behavior together. For large oversubscribed clusters, this kind of cross-layer design seems much more realistic than relying on fabric overprovisioning alone.