Title: Open the Floodgates in a Digital Twin: Experiences of Building Spillway for 100M±User Signaling Storms in Cellular Core Networks
Authors: Hongtao Xie, Jianmin Liu, Ce Yang, Yu He, Li Chen, Dan Li, Mineng Fu, Xi Chen, Siyu Chen (Tsinghua University; Department of Networks, China Mobile; Zhongguancun Laboratory)
Review:Ying Yao(SNG first-year PhD student )
Introductio n
China Mobile operates one of the world’s largest 5G Standalone (SA) networks, serving approximately 622 million subscribers via 2.6 million base stations across 31 provinces. Its core network employs a Service-Based Architecture (SBA), where the AMF handles access and mobility management, the SMF manages sessions, the UDM stores subscriber profiles, and the PCF enforces policies. A seemingly simple user registration or service request requires sequential processing across multiple network functions; a single UE request typically amplifies into roughly 15 internal SBA transactions. Consequently, the core network’s effective throughput is constrained by the slowest node in the chain rather than being determined solely by the ingress no de.

Localized fiber cuts, data center failures, or application anomalies can cause millions of devices to go offline simultaneously. Upon link recovery, these devices attempt to re-register almost concurrently, generating a signaling surge that far exceeds normal load levels. When queuing delays exceed the hard-coded 10–15 second timeout thresholds on the UEs, the devices retry, while the core network may still be processing stale requests that users have already abandoned. The accumulation of stale requests and new retries drives effective goodput toward zero. Even more critical is the risk that the system remains trapped in an overload state due to unproductive work—even after external traffic subsides—a phenomenon the paper terms “metastable colla pse.”
Existing overload control mechanisms—based on CPU load, subscriber capacity, or neighbor node success rates—suffer from a localized perspective. For instance, an AMF might perceive itself as capable of accepting requests because its CPU load is only 40%, while the downstream UDM has already reached 100% utilization. Requests admitted by the AMF ultimately fail; instead of successfully restoring service to users, they further deplete resources across the entire chain. The fundamental issue is that user recovery is an end-to-end process, whereas individual network functions make decisions based solely on their own operational viab ility.
The paper introduces Spillway, a digital twin system designed to address signaling storms in cellular core networks. Instead of modifying existing firmware or introducing new real-time global backpressure protocols, it treats standard 3GPP static parameters as a programmable control plane: it simulates failures in an offline digital twin and then jointly optimizes local rate-limiting parameters across multi-vendor equipment, enabling upstream nodes to proactively sacrifice local throughput to protect the entire downstream link. The system has been operating on China Mobile’s production network for five years .
Key idea and contrib ut ion
Spillway accepts network topology, service snapshots, and fault scenarios as inputs, outputting a set of globally optimized configurations. Its closed-loop mechanism consists of two parts: the CN-DES simulator evaluates signaling storms under candidate parameters to generate metrics such as the number of user fallbacks and recovery times; the HEBO search engine updates its model based on these metrics and proposes the next set of candidate configurations, continuing the process until a safe solution balancing service continuity and recovery speed is found.
(1) Achieving implicit global coordination through “altruistic rate limiting”
Spillway categorizes the resource consumption process of signaling transactions into four layers. The first layer is AMF access control, which limits traffic as soon as registration or Service Request messages enter the network; this serves as the most critical traffic gate, as rejection at this stage incurs the lowest cost. The second layer resides at the SMF, limiting PDU Session establishment and modification to prevent a single external request from triggering a cascade of internal state operations. The third layer is located at the IMS/SBC, prioritizing voice services—such as VoNR/VoLTE and emergency calls—during periods of congestion. The fourth layer is at the UDM/UDR, protecting user database data integrity through strict backpressure; if the preceding two layers function correctly, this final line of defense should rarely be trigg ered.
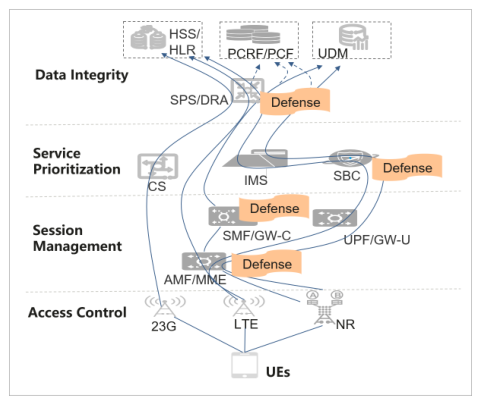
The key here is not for each node to maximize its own throughput, but rather to align the ingress rate with the capacity of the weakest downstream node. Even if the AMF has spare capacity, it will proactively drop requests based on the safe handling limits of the SMF or UDM, thereby avoiding failures that would otherwise occur after requests have already entered the system. The paper terms this behavior “altruistic shedding”: local nodes “altruistically” lower their access rates to secure better global goodput and recove ry stability.
This coordination is achieved entirely through parameters already supported by network equipment—such as token buckets, queue depths, query rates, connection pools, and backoff timers—making it applicable to equipment from vendors including Huawei, Ericsson, Nokia, and ZTE. Parameters are deployed via standard O&M interfaces like Netconf/YANG, requiring no firmware modifications. Spillway operates outside the active service path; even if the management system fails, the network retains the last known safe configuration, ensuring no new single point of failure is introduced. (2) Constructing Digital Twins for Tens of Millions of Use rs with CN-DES
Traditional discrete-event simulation (DES) creates independent objects for each User Equipment (UE)—maintaining state machines, timers, and event queues—resulting in memory usage that grows linearly with the number of users. The paper’s fine-grained baseline crashed after exceeding 128 GB of memory when simulating 17.3 million users, making it incapable of supporting parameter searches that require running a full simulation for e very iteration.
The core abstraction of CN-DES is the Aggregated UE Vector (AUV). Instead of tracking individual users, it aggregates users who share the same protocol state, retry phase, serving AMF, and next-timer bucket into a triplet: protocol state, user count, and next trigger time. Consequently, a single event in the event queue can represent the simultaneous state transition of tens of tho usands of users.

When a user group passes through an AMF token bucket, CN-DES deterministically splits the AUV into “accepted” and “rejected” sub-vectors based on the acceptance probability; before entering the queue, the newly generated vectors are merged with existing ones based on state and time buckets. With populations in the millions, the Law of Large Numbers ensures the stability of this aggregation approximation, while the split-merge mechanism shifts complexity from the number of users to the finite number of protocol states. The system preserves retry and backoff behaviors at a 1-second granularity, aiming to accurately reproduce macroscopic storm dynamics—such as queue backlogs, retry amplification, and user fallback—rather than reconstructing the complete trajectory of ever y indi vidual user.
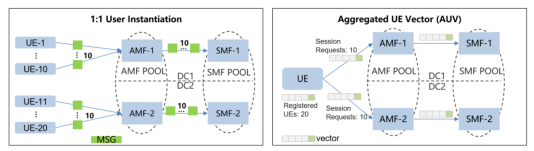
CN-DES employs a three-stage pipeline: initialization, a vectorized event loop, and telemetry export. It reads topology and traffic snapshots from production logs to generate initial AUVs; the core loop advances state transitions for the entire user population; finally, it outputs CPU usage, queue depth, and rejection counts in the same format as production Prometheus exporters, allowing existing monitoring systems to directly consume the simulation results. Since provincial core networks in China Mobile typically serve between 8 million and 42 million users, and the impact of signaling storms is generally confined to provincial partitions, there is no need to simulate the entire national base of 622 million users in a single run. (3) Using HEBO to Search for Safe Parameters Near t he “Stability Cliff”
A regional topology comprising approximately 200 network units involves thousands of tunable parameters. The authors focused their search on 42 groups of critical flow-control parameters—identified through global sensitivity analysis and functional equivalence grouping—yet the number of valid combinations remained around $10^{63}$. A further challenge lies in the non-smooth mapping from parameters to system outcomes: relaxing an AMF threshold by just 1% can shift the bottleneck to a UDM several hops away, causing the system to plummet abruptly from a state of re covery into collapse.
The paper defines the objective as a weighted sum of the user fallback ratio and the recovery duration. Near the capacity critical point, the same set of parameters might lead to either recovery or collapse depending on stochastic traffic patterns, resulting in a sudden spike in variance. Standard Bayesian optimization typically assumes constant noise variance; consequently, it tends to either chase short-term high throughput at the critical edge or retreat to overly conservative solutions. HEBO, by contrast, learns input-dependent noise variance and employs input transformations to handle non-convex geometry. This allows it to steer clear of the high-variance “cliff edge” and instead select a “robust plateau” characterized by both lower mean costs and lower volatility.
(4) Offline Computation, Static Pre-deploy ment, and Safe Rollback
Spillway does not take over real-time signaling during an incident. Offline optimization is triggered by capacity changes or disaster recovery planning; after operators review the results, the parameters are pre-deployed during routine maintenance. The rate limiters remain inactive when normal traffic peaks stay below these thresholds; during signaling storms, the devices’ native 3GPP mechanisms automatically enforce rate limiting. Should anomalies arise post-deployment, the management plane can roll back to the previous configuration; if the management plane loses connectivity, the system retains the last k nown safe parameter set.
The system initially operated passively in “shadow mode” for 12 months, collecting telemetry and generating configurations for audit purposes. Subsequently, access-layer defenses were activated in two provinces, with the system gradually expanding nationwide and across additional defense layers over a three-year period. This deployment strategy avoids risky live A/B testing on critical infras tructure.
Evaluat ion
The authors evaluated the system on a server equipped with an Intel Xeon Gold 6240 processor and 128 GB of RAM, constructing a topology of 200 network units that mirrors a production core network. The experiments assessed simulation speed and accuracy, optimization efficiency, end-to-end resilience, and real-wo rld production performance.
(1) Scalab ility and Accuracy of CN-DES
At a scale of 1.16 million users—where the fine-grained discrete-event baseline remained operational—a single simulation run took over 6,000 seconds for the baseline, compared to approximately 100 seconds for the AUV model, representing a 60-fold speedup. At a scale of 17.3 million users, CN-DES completed the simulation in 800 seconds, whereas the fine-grained baseline exceeded the 128 GB memory limit. A synthetic stress test with 100 million users took 761 seconds and consumed approximately 1,002 MB of memory—figures comparable to the 723 seconds and 994 MB recorded at 17.3 million users—demonstrating that resource overhead remains largely indepe ndent of the number of users.

Across 50 random scenarios simulated by both models, the AUV model achieved an average accuracy of 96.2% relative to the fine-grained baseline, with P50, P90, and P99 prediction errors of 0.5%, 1.8%, and 2.5%, respectively. Replaying 14 actual regional storm events that occurred prior to the deployment of “Spillway” yielded Mean Absolute Percentage Errors (MAPEs) of 8.3% for the number of users falling back and 11.2% for recovery time. These results indicate that, despite discarding individual trajectories, the AUV model preserves the macroscopic behaviors that determine overload thresholds.
(2) Optimization Speedand Solution Quality
Across network scales ranging from 200 to 320 units, HEBO identified a robust configuration in approximately 100 iterations, whereas TuRBO required about 140 iterations—a 28% reduction in the number of samples. Compared to TuRBO, the parameters identified by HEBO resulted in a more than fourfold reduction in user fallbacks and a 10%–15% decrease in recovery time. Ablation studies further demonstrated that removing safety constraints increased the number of convergence rounds from 103 to 147, while failing to model heteroscedasticity led the optimizer to select unstable configurations, causing us er fal lbacks to surge to 319,160.

(3) End-to-en d resilience against traffic surges
In a scenario where 17.3 million users attempted simultaneous re-registration, Spillway was compared against three industry-standard mechanisms: CPU Load-based, User Capacity-based, and Lookahead Success Rate-based approaches. As the user count increased, Spillway reduced user fallbacks by 80% compared to the best baseline; even as the scale of network units grew, it maintained a reduction of approximately 60%. It capped signaling peaks at around 35,000 requests per second, whereas the CPU load-based mechanism allowed peaks to escalate beyond 120,000 requests per second. While the latter only triggers after the node is already overloaded, Spillway proactively shapes traffi c befo re des tructive peaks can form.
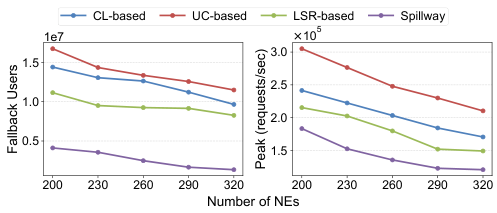
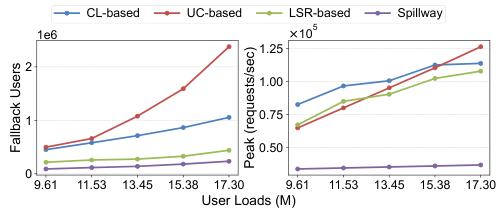
Parameter sensitivity analysis further illustrates the risks associated with critical thresholds: the optimal AMF registration threshold was identified as 12,400 requests per second. Tightening this limit by 9% increased recovery time only marginally—from 314 to 318 seconds—whereas relaxing it by 9% triggered a metastable collapse, pushing recovery time to 340 seconds and resulting in 194,000 user fallbacks. The value of the offline digital twin lies precisely in identifying a stable operating region that is slightly conservative yet safely distanced f rom the “cliff edge” of system failure .
(4) Five-year production deployment
In July 2024, an anomaly in a popular application caused 17.81 million devices in a specific province to initiate simultaneous retry attempts. Although the AMF had a local capacity of 18,000 requests per second, Spillway had pre-configured the ingress limit to 12,400 requests per second to align with the processing capacity of the downstream SMF. The actual peak SMF CPU usage was 73%—below the 85% performance degradation threshold—resulting in no network element overload or user fallback. In contrast, replaying the same traffic trace with the old configuration caused the SMF to saturate within 45 seconds, leading to a worst-case scenario of 2.02 million user fallbacks.
In July 2025, following the recovery from a transmission failure in a specific province, 3.36 million users required simultaneous reconnection. Each registration request triggers approximately 15 UDM queries; replay simulations using the old configuration indicated that this surge could cause database deadlocks lasting 932 seconds and result in 324,021 user fallbacks. Spillway throttled incoming traffic based on the UDM’s precise write capacity, ensuring 93.6% of users remained completely unaffected, while the remaining 6.4% experienc ed only brief slowdowns or fallback to 4G.
In October 2024, a disaster recovery switchover in a provincial data center affected 20.3 million users. As the cold-standby database’s cache was not yet warmed up, linear capacity estimates predicted a 44-second deadlock during migration. Spillway calculated an input rate trajectory that dynamically adjusted with the warm-up process, reducing the number of affected users by 87.2% and limiting active flow control to just 29 seconds. To date, Spillway has been deployed across 31 provinces, covering approximately 622 mi llion u sers and 2.6 million base stations .
QA
Q1: Since the first layer of AMF access control incurs the lowest cost for rejecting requests, could we simply rely on this single global admission control point at the ingress? Is adjusting just this one “knob”—after observing o r predicting downstream failures—suff icient?
A1: The first layer is indeed the most critical line of defense, as rejecting requests earlier minimizes the waste of processing resources; however, relying solely on this layer may be insufficient. Ingress decisions require predicting the state of downstream nodes like the SMF and UDM, and any model carries the risk of overestimation or underestimation. Overestimating downstream load could suppress ingress traffic too aggressively, wasting usable network capacity, while underestimating it could allow excessive requests into the system, potentially overwhelming the backend. Subsequent layers act as additional shields, continuing to limit session complexity, safeguard critical services, and protect databases in cases where ingress predictions are off-target or bottlenecks shift elsewhere.
Q2: If we use digital twins and machine learning to simulate various anomalous traffic patterns—such as synchronized retries or disaster recovery failovers—in advance, could we learn all “bad scenarios” and enable the first l ayer to make sufficiently accurate predictions?
A2: The response given on-site noted that exhaustive prediction is not feasible in a production environment. First, operators cannot foresee exactly which failures will occur or the specific time-series patterns of incoming traffic; if all anomalies could be accurately predicted, there would be no such thing as an “unknown failure.” Second, given the scale of hundreds of millions of users and numerous network elements, the computational cost of enumerating every combination of failures, request sequences, and defense strategies would be prohibitive; certain highly unique user request patterns might even challenge the performance of an accelerated CN-DES. Consequently, Spillway employs offline simulation to identify robust parameters for representative scenarios rather than claiming to precisely cover every future possibility; the multi-layer defense strategy provides a safety margi n for unmodeled scenari os and prediction errors.
Personal th oughts
The most valuable insight from this paper is that it does not equate the “absence of a global backpressure protocol” with the “necessity of redesigning the protocol.” Given a user base of 622 million, multi-vendor equipment, and rigorous change management processes, waiting for standardization, firmware upgrades, and network-wide replacements is simply unrealistic. Instead, Spillway taps into the latent control capabilities of existing static parameters, using offline computation to orchestrate a set of independent local controls into a mechanism that approximates global backpressure. This represents a classic—a nd highly practical—trade-off in systems research.
AUV also illustrates a key principle of digital twins: being “sufficiently accurate and timely” is more important than achieving a “perfect, object-by-object replica.” The paper openly acknowledges that using one-second time buckets and aggregate metrics results in a loss of individual-level detail; however, through triple validation—involving fine-grained models, historical incident data, and small-scale online testing—it demonstrates that these errors do not significantly shift the boundaries of macroscopic phase transitions. In the context of signaling storms, obtaining deployable, safe parameters within minutes is often far more valuable than receivi ng a more precise post-mortem analysis hours later.
The limitations of the approach are equally clear. Spillway relies on the assumptions that fault impacts remain largely confined to provincial core networks, user behaviors within the same AUV are approximately independent, and historical data covers the logic of major protocols and vendors. In scenarios involving cascading failures across provinces, highly correlated terminal behaviors, or novel 6G control workflows, both the aggregation assumptions and the existing parameter space would require re-validation. More importantly, because altruistic rate limiting requires access teams to voluntarily sacrifice local throughput, organizational goals must shift from “maximizing utilization at every node” to “maximizing the number of successful end-to-end user sessions.” The paper’s five-year deployment history demonstrates that such organizational coordination is just as critical as the algorithm design itself.