Title: PReCCL: Performant and Resilient Collective Communication via Integrated Inband Telemetry and Workload Reallocation
Authors: Zhiyong Chen, Rui Yan, Zihan Yan, Dan Li (Tsinghua University); Kaihui Gao, Li Chen, Fei Gui (Zhongguancun Laboratory); Jiamin Cao, Jiaqi Gao (Alibaba Cloud)
Scribe : Mengqi Fu (Xiamen University)
Introduction
Collective communication operations such as AllReduce and AlltoAll in large-model training are typically decomposed into multiple sub-tasks and mapped onto different Virtual Topologies (VTs). NCCL assigns an equal amount of data to each VT, which works well when their bandwidths are similar. Under multi-tenant contention, link imbalance, or partial failures, however, the slowest VT determines the completion time of the entire CCT while the other VTs become idle early. Transport-layer congestion control observes only individual flows, whereas static CCL scheduling assumes relatively stable network conditions. Neither can readily identify and eliminate imbalance among VTs within an executing collective.
Key Idea and Contributions
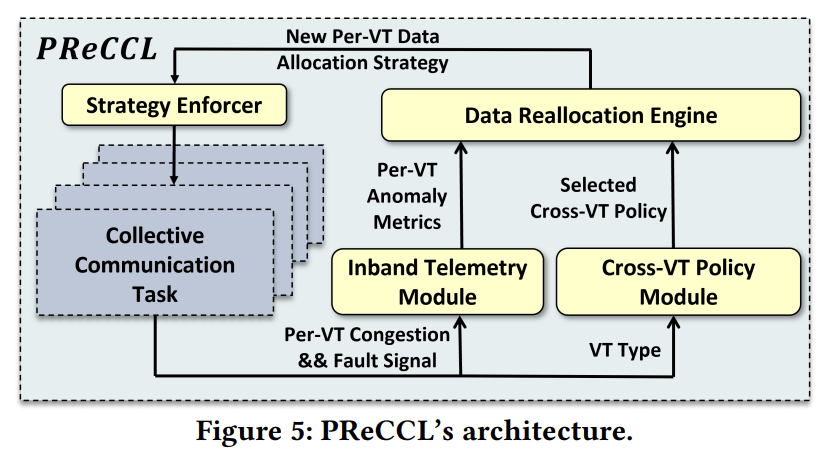
PReCCL’s central idea is to convert network anomalies into observable VT-stall signals and dynamically reallocate work at CCT boundaries so that all VTs finish as close together as possible. The system contains four key designs:
-
FIFO stall counts for cross-VT inband telemetry. When the sender-side FIFO tail pointer cannot advance because downstream processing has not completed, GPU threads accumulate a stall count in the wait loop. This signal captures blocking across NVLink, PCIe, and inter-host network paths without relying on clocks that are not globally synchronized across CUDA SMs. An online-calibrated alpha-beta model combines the stall count with the data volume to estimate each VT’s completion time, while compact metadata is piggybacked on existing synchronization traffic without requiring a separate control connection.
-
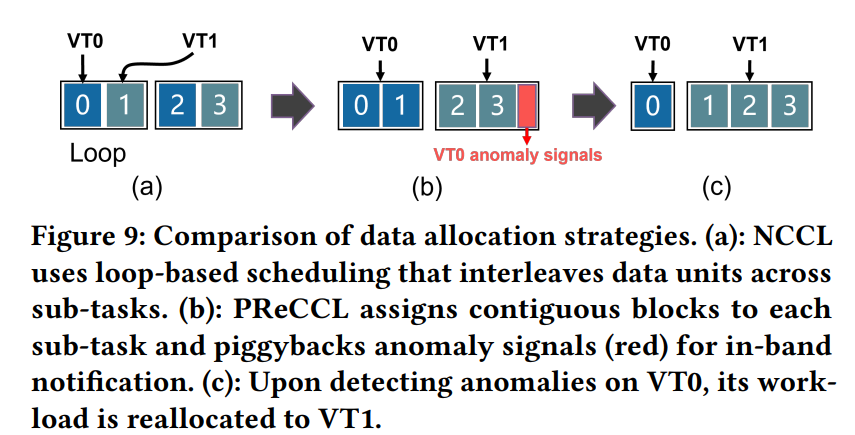
Updates only at CCT boundaries to maintain consistency across ranks. Each CCT carries an epoch tag. All ranks finish the current epoch, exchange telemetry for the same epoch, and deterministically compute the next allocation. PReCCL changes only the byte ranges carried by existing channels, preventing races in which different ranks use old and new allocations.
-
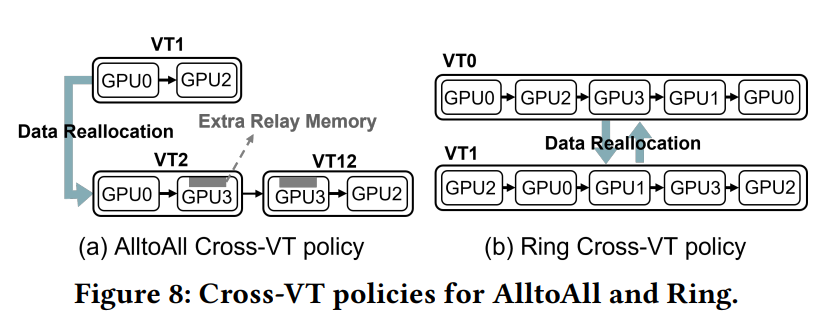
Cross-VT policies tailored to different collectives. For Ring, Tree, ReduceScatter, and AllGather, the system assigns contiguous data blocks to independent VTs and shifts bytes from VTs with longer estimated completion times to faster VTs. For AlltoAll, it also enumerates single-hop relay paths over intra-node NVLink and enables a relay only when the benefit of bypassing congestion exceeds the relay overhead. Inspired by TeXCP, the allocator coordinates adjustments using completion-time information from all VTs while preserving the total data volume, avoiding the persistent oscillation caused by independent per-VT AIMD (Figures 8 and 9).
-
A unified treatment of partial failures as extreme congestion. When a VT exhibits an anomalous stall count or a communication failure, all processes mask that VT, retry the failed CCT, and redistribute its work among the remaining healthy VTs. At the beginning of each collective round, a lightweight probe checks whether the path has recovered and reincorporates it once it becomes healthy. This mechanism handles transient partial failures as long as at least one candidate VT remains available; a complete partition or the loss of all VTs still falls back to checkpoint/restart.
Q1: Does PReCCL require prior knowledge of the paths used in the network? If yes, how is path information collected? If not, how does it leverage multiple available network paths?
A1: PReCCL adopts a channel-based mechanism. Channels are pre-prepared during the CCL initialization stage. New paths will not be activated directly at runtime; new channels can only be added for use after probes confirm they are available again.
Q2: How does PReCCL handle dynamic network load? For example, in a data center running both inference and training workloads where inference consumes less network resources.
A2: PReCCL tracks the contention status of each VT and averages the completion time across VTs. When channel states change in a multi-tenant environment, the system dynamically adjusts task placement on each VT to adapt to dynamic network conditions. Relevant tests on this dynamic adaptability have been conducted.
Q3: Does the dynamic placement of channels interact with the transport layer and accept feedback from it? Or does it only observe collective communication metrics every epoch?
A3: A custom equation is used to probe latency for better scheduling decisions. The probing targets the entire collective communication task, instead of sending standalone probe packets.
Evaluation
The authors use three complementary environments: a 32-GPU physical testbed, Multiverse packet-level simulations at 512/1024-GPU scale, and a two-week production trial on a 1024-GPU H200 cluster. The baselines include NCCL, SyCCL, MCCS, Crux, and FuseLink.
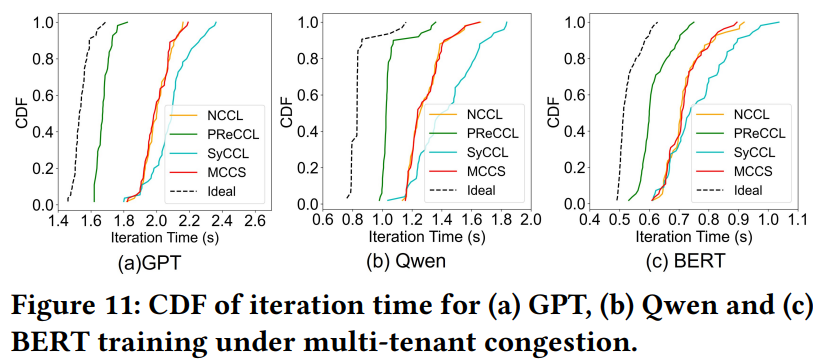
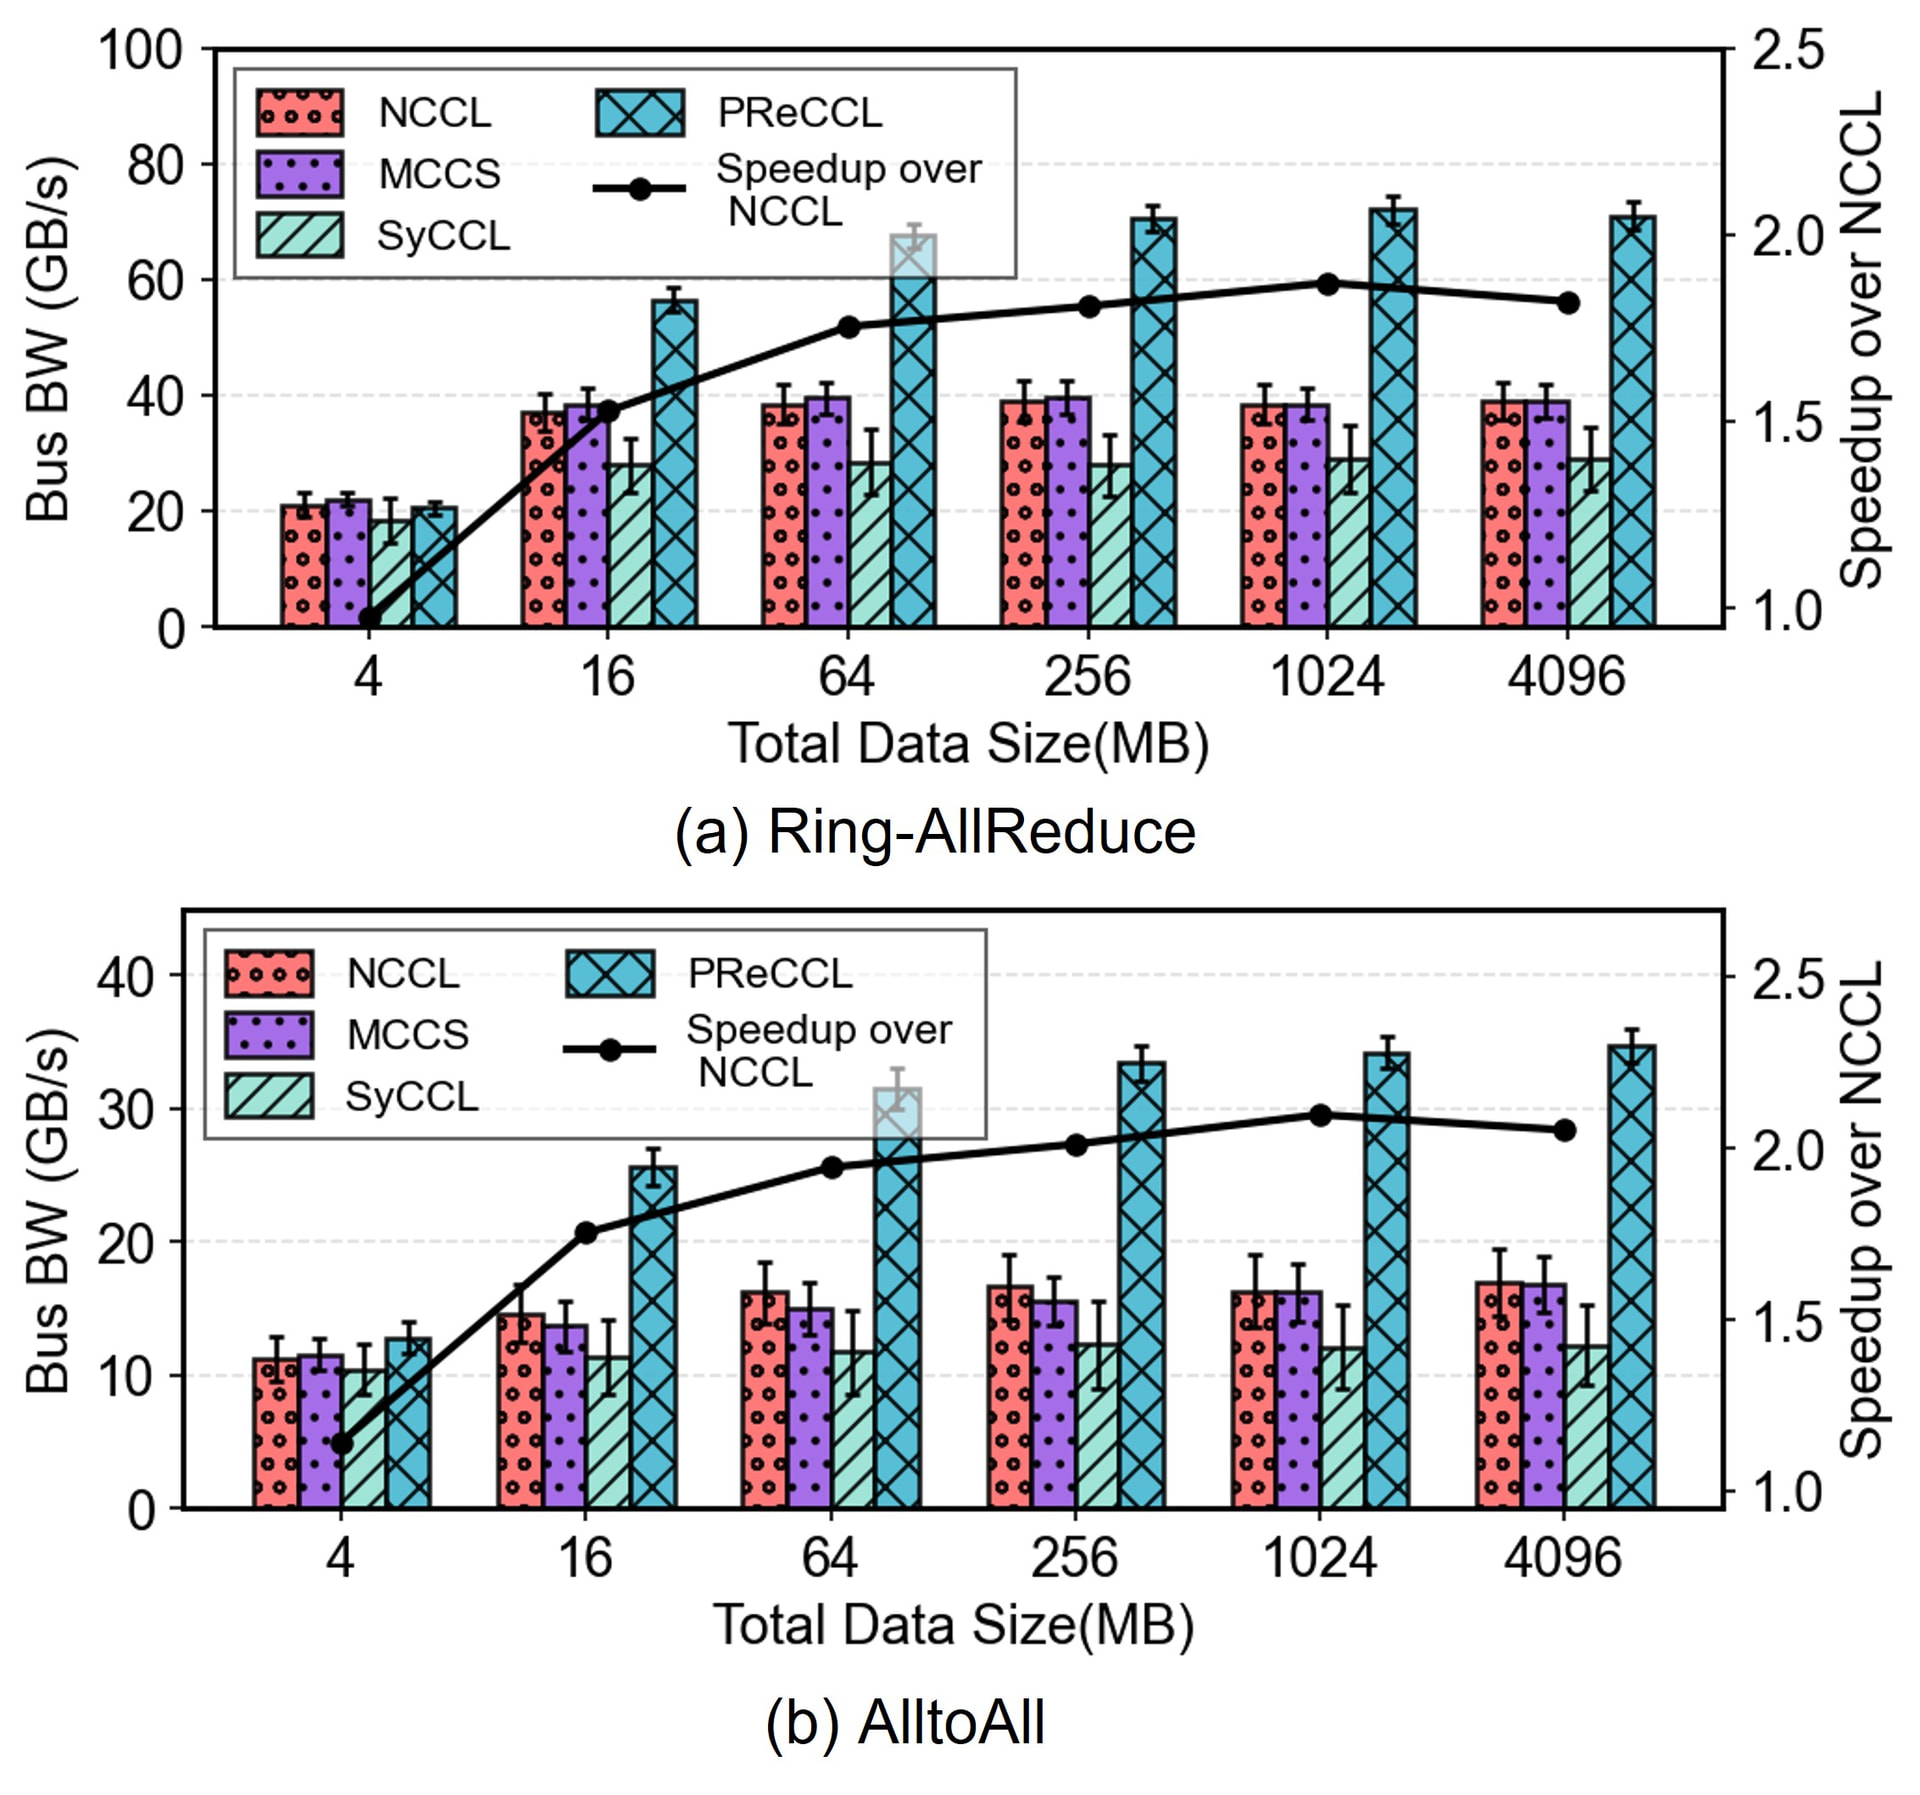
Under multi-tenant load, PReCCL accelerates the iteration time of GPT, Qwen, and BERT by 1.19×, 1.21×, and 1.18× over NCCL, respectively (Figure 11). For data sizes above 64 MB, it improves average bus bandwidth by 1.8× for Ring-AllReduce and 2.1× for AlltoAll (Figure 12). In the 1024-GPU simulation, AlltoAll with 16 concurrent jobs achieves a 2.3× speedup over NCCL. The production trial completes 146 jobs and reduces median/P95 JCT by 5.7%/51.2%, while increasing median/P95 per-job NIC utilization by 21.4%/12.5%. In terms of control overhead, the additional latency for 64 MB messages is 0.97% for Ring/Tree and 0.11% for AlltoAll. After a partial NIC failure, the system reconverges within five round trips and retains 78.0% of its pre-failure bus bandwidth.
Together, these experiments show that a CCL can convert dynamic network problems into cross-VT workload adjustments, improving both performance and availability without changing the training framework or transport connections.
Personal Thoughts
In my view, PReCCL’s key strength is that it intervenes at the right control layer. It does not compete with DCQCN, HPCC, or packet spraying; instead, it operates above them on the co-flow semantics of a collective. A rate or path decision that is sensible for an individual flow does not necessarily shorten a collective whose overall completion time is determined by its slowest VT. Restricting updates to CCT boundaries and changing only the byte ranges on existing channels also makes the design easier to deploy than approaches that rebuild transport connections.