Title: RepLLM: Toward Automatically Reproducing Network Research Results
Authors: Yining Jiang, Yunxin Xu, Wenyun Xu, Yufan Zhu, Rui Liu, Tangtang He, Haiying Huang, Letian Zhu, Qingyu Song, Qiang Su, Lizhao You, Lu Tang, Qiao Xiang (Xiamen University); Wanjian Feng (Yealink); Yuchao Zhang (Beijing University of Posts and Telecommunications); Linghe Kong (Shanghai Jiao Tong University); Jiwu Shu (Xiamen University & Tsinghua University).
Introduction
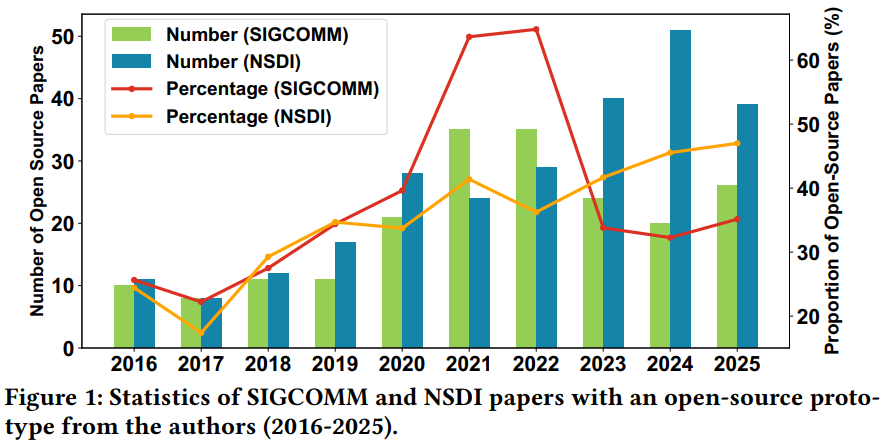
Reproducibility is a fundamental requirement in computer networking research because it allows researchers and engineers to validate results, compare systems fairly, and build upon previous work. However, reproducing networking research results is difficult because many papers do not provide open-source implementations, and rebuilding complex network systems from descriptions requires significant domain knowledge and engineering effort. The authors point out that only about 38% of papers published in major networking conferences such as SIGCOMM and NSDI provide open-source implementations, forcing researchers to manually re-implement systems from papers.
Recently, Large Language Models (LLMs) have shown strong potential in code generation. However, existing LLM-based code generation systems are not sufficient for reproducing networking research. Networking systems involve diverse domains, heterogeneous architectures, long technical papers, multiple dependent modules, and complex implementation details. Current approaches either focus on narrow domains or require excessive human interaction. They also suffer from inefficient context handling, high token consumption, and insufficient verification mechanisms.
Therefore, the paper studies the problem of automatically reproducing network research systems from academic papers and proposes RepLLM, an end-to-end multi-agent framework designed to transform research papers into executable and logically correct implementations.
Key idea and contribution
The key idea of RepLLM is to treat paper reproduction as a complex software engineering process rather than a simple code-generation task. Instead of asking a single LLM to generate an entire system, RepLLM divides the reproduction workflow into several specialized stages and assigns different responsibilities to multiple LLM-based agents.
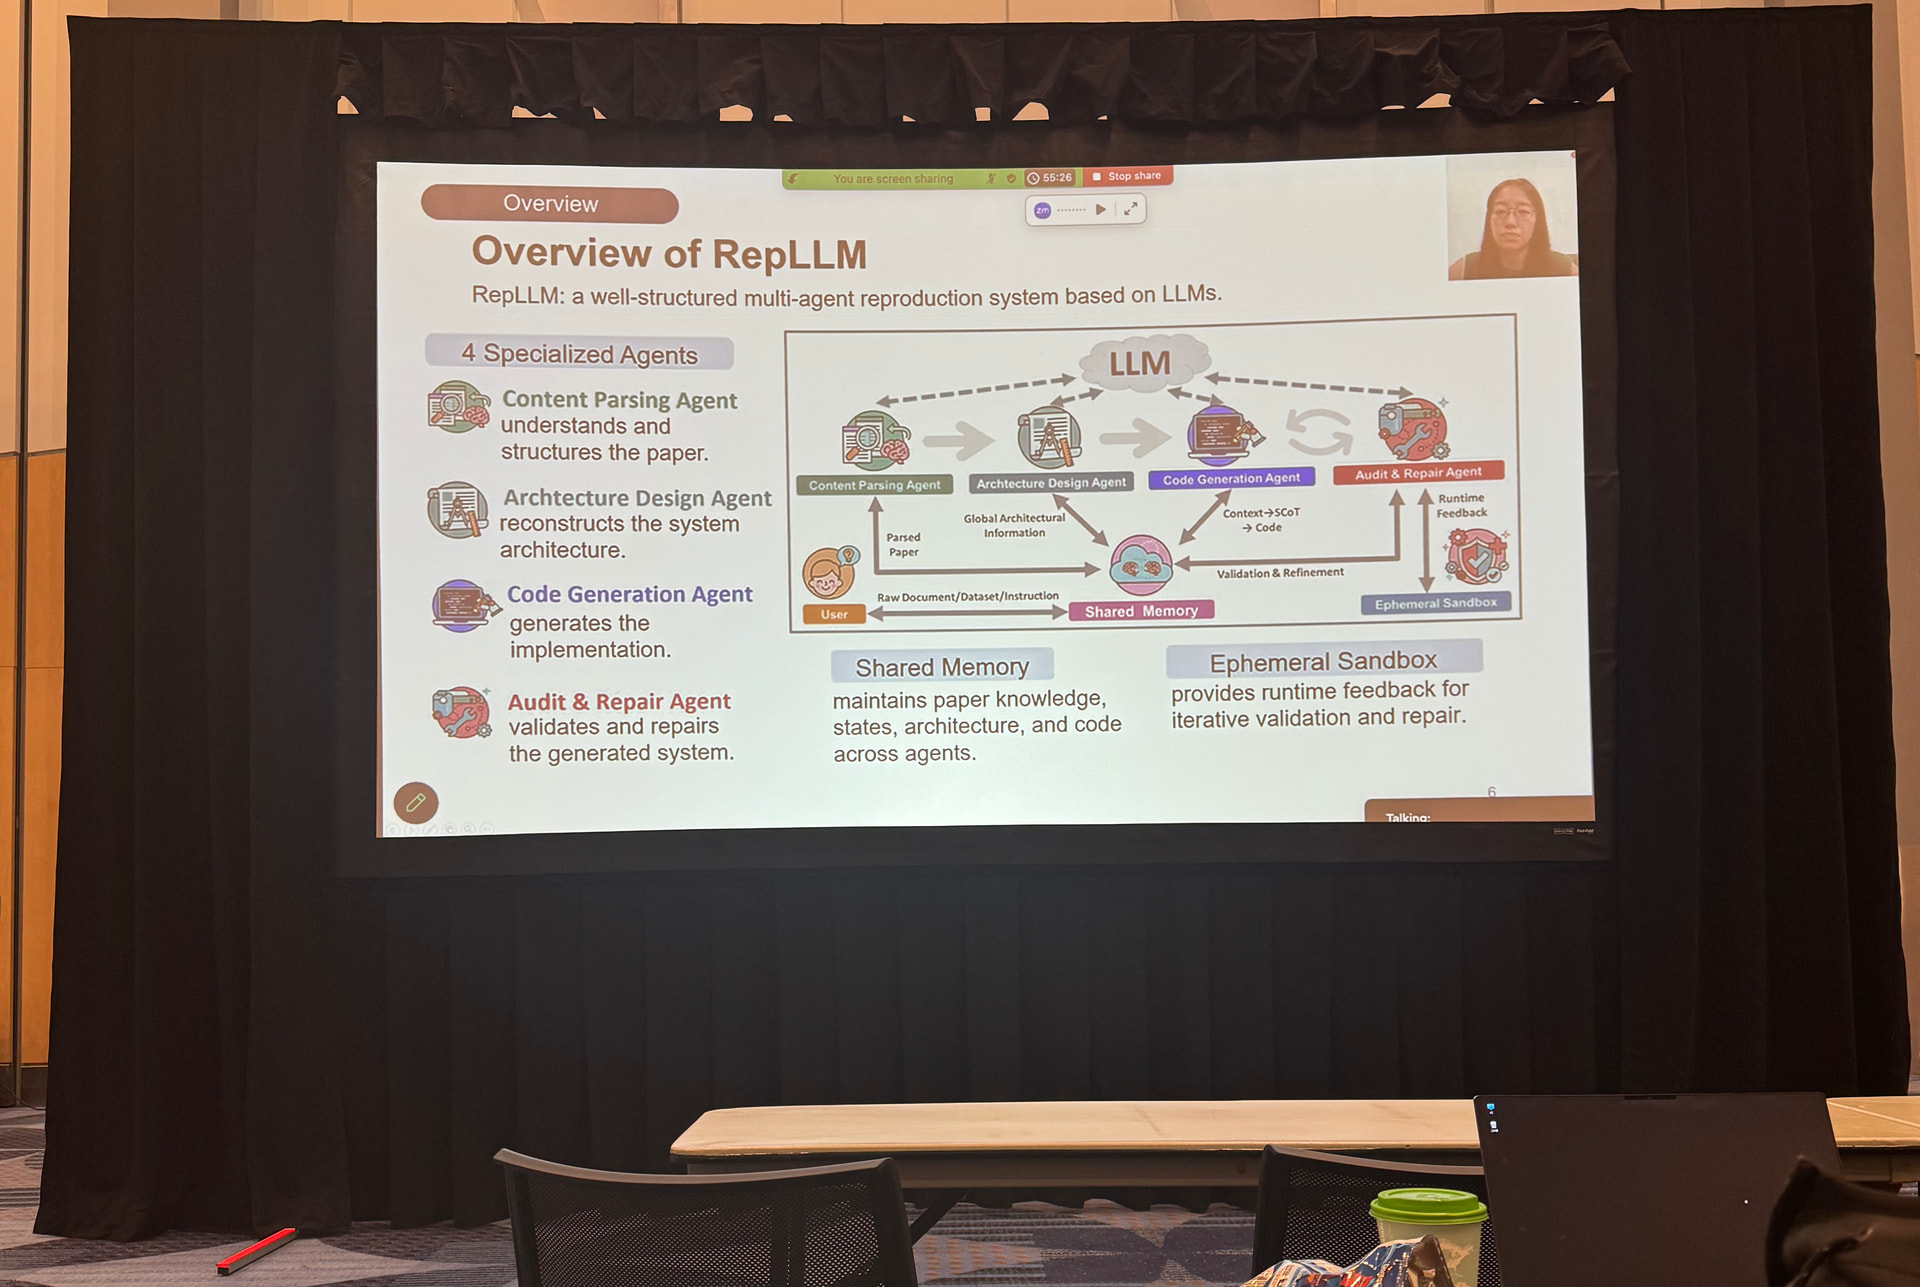
The system contains four major agents:
-
Content Parsing Agent (CPA)
This agent converts raw research papers into structured representations. It extracts text, figures, tables, algorithms, and equations, and stores them in a structured format so that later agents can efficiently retrieve relevant information. -
Architecture Design Agent (ADA)
ADA analyzes the paper and designs the system architecture. It decomposes the target system into smaller implementation steps represented as a Directed Acyclic Graph (DAG), including dependencies and input/output interfaces. -
Code Generation Agent (CGA)
CGA generates executable code based on the architecture description. It introduces a Structured Chain-of-Thought (SCoT) approach, which first converts algorithm descriptions into structured intermediate representations before producing actual code. This reduces the reasoning burden on LLMs and improves consistency between paper descriptions and implementation. -
Audit & Repair Agent (ARA)
ARA verifies and improves generated code through static analysis and runtime testing. It uses sandbox-based execution to detect errors and iteratively repair incorrect implementations.
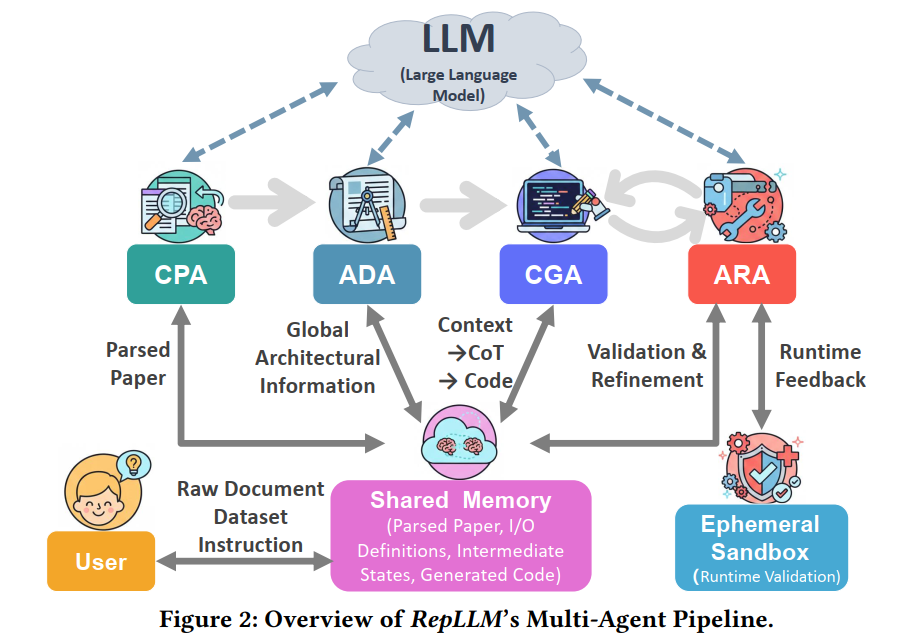
A central component of RepLLM is the Shared Memory mechanism, which stores structured paper information, architecture descriptions, intermediate states, and generated code. Unlike traditional multi-agent systems that repeatedly exchange large amounts of context, Shared Memory allows agents to access only the necessary information, reducing token consumption and maintaining global consistency.
The main contributions of this paper are:
-
A multi-agent framework that automatically converts research papers into executable network system implementations.
-
An efficient Shared Memory architecture for managing long-context information and coordinating agents.
-
A hierarchical verification and repair mechanism combining static analysis and dynamic execution.
-
Extensive evaluation showing that RepLLM can reproduce network research systems with minimal human intervention.
Evaluation
The authors evaluate RepLLM on seven representative networking research papers from top conferences, covering different domains such as traffic engineering, DNS verification, coding theory, probabilistic verification, and in-network systems. The evaluated systems include NCFlow, GRooT, Rateless IBLT, SelfStarter, NetDice, Teal, and NetChain.
RepLLM is compared with two baselines:
-
Standalone LLM: directly provides the whole paper to an LLM and asks it to generate the complete codebase.
-
Claude Code CLI: a tool-based coding agent framework capable of file operations and execution.
The evaluation measures:
-
Code executability and dataset loading success.
-
Paper-code semantic alignment.
-
Token consumption.
-
Reproduction performance compared with original paper results.
-
Human effort required for refinement.
The results show that RepLLM successfully generates executable code and loads required datasets for all evaluated tasks. It achieves better semantic alignment than standalone LLM generation and provides more reliable reproduction results. Across three independent runs, RepLLM obtains an average semantic alignment score of 6.18 ± 0.24, showing stable performance.
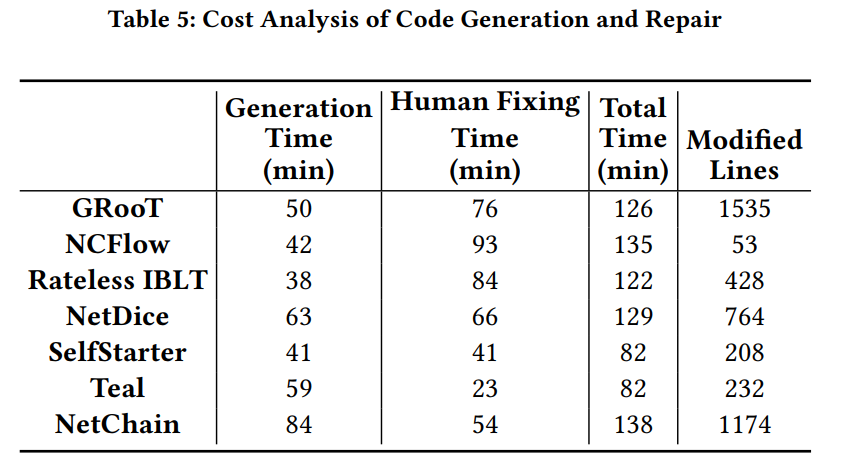
RepLLM finishes generation within about 1.5 hours, and with limited human calibration, performance reproduction can typically be completed in around 2 hours.
Q&A
Q: It was a very interesting presentation. My question is related to the future work you mentioned about AI-generated systems research. How soon do you think we will be able to write a complete systems paper using LLMs or AI agents? Do you think the next generation of systems conference papers could be fully generated by LLMs, or do you think this is still several years away?
A: Actually, since 2023, our team has been exploring how to use AI to generate code for systems research. At that time, this goal might have sounded unrealistic. However, in recent years, with the rapid progress of LLMs and AI agents, we have seen significant improvements in AI coding capabilities and AI-assisted research capabilities. Therefore, we believe this direction is becoming increasingly feasible, and we are continuing to refine our approach toward achieving this goal.
Q: I have one question. Have you evaluated the quality of the reproductions? I imagine that some of the papers you reproduced may already have their own open-source implementations. I’m interested in understanding how your generated implementations compare with the original ones. After reproducing the implementations, did you evaluate whether your reproductions were better or worse compared with the authors’ original implementations?
A: Yes. We provide more detailed analysis and comparisons in the paper.
Personal thoughts
RepLLM is an interesting step toward automated scientific reproducibility. I like that the paper does not treat LLM code generation as a single prompting problem. Instead, it recognizes that reproducing a research system involves many engineering tasks, including understanding papers, designing architectures, maintaining dependencies, debugging, and validating experimental results. The multi-agent design is a reasonable solution because different stages require different types of reasoning.
The Shared Memory idea is particularly valuable. Many existing LLM-based agents lose consistency because they repeatedly pass large amounts of context between agents. By introducing structured intermediate representations, RepLLM improves both efficiency and reliability. The SCoT mechanism is also a strong contribution because it creates a bridge between human-readable algorithms and machine-generated code.
However, some limitations remain. First, the system still depends heavily on the quality and completeness of the original paper. If important implementation details are missing, even a sophisticated agent framework may not reproduce the exact system. Second, evaluation is mainly based on a limited number of networking papers, so it remains unclear how well RepLLM generalizes to other scientific domains.
Future research could explore combining RepLLM with stronger formal verification techniques, larger-scale benchmarks across different scientific fields, and methods that automatically discover missing experimental details from external resources. Overall, this paper represents an important direction toward AI-assisted scientific discovery and reproducible research.