Title: Scale-up PIFO: Interleaving Multiple Priority Queues for High Speed Programmable Scheduling
Authors: Hao Mei, Shili Chen, Xu Chen (Fudan University); Zixuan Chen (China Telecom); Ruyi Yao, Zhiyu Zhang, Hao Wang, Deli Huang, Weiyi Chen, Yibo Fan, Yang Xu (Fudan University)
Introduction
Push-In First-Out (PIFO) is a useful abstraction for programmable packet scheduling. A programmable function assigns each packet a rank, and the queue transmits packets in rank order, allowing many scheduling policies to share the same hardware. The problem is speed. With port rates moving toward 800 Gbps and 1.6 Tbps, the processing budget per packet is now below a nanosecond. Making one PIFO queue faster becomes increasingly difficult, especially when the queue also needs enough high-speed memory to hold many packets.
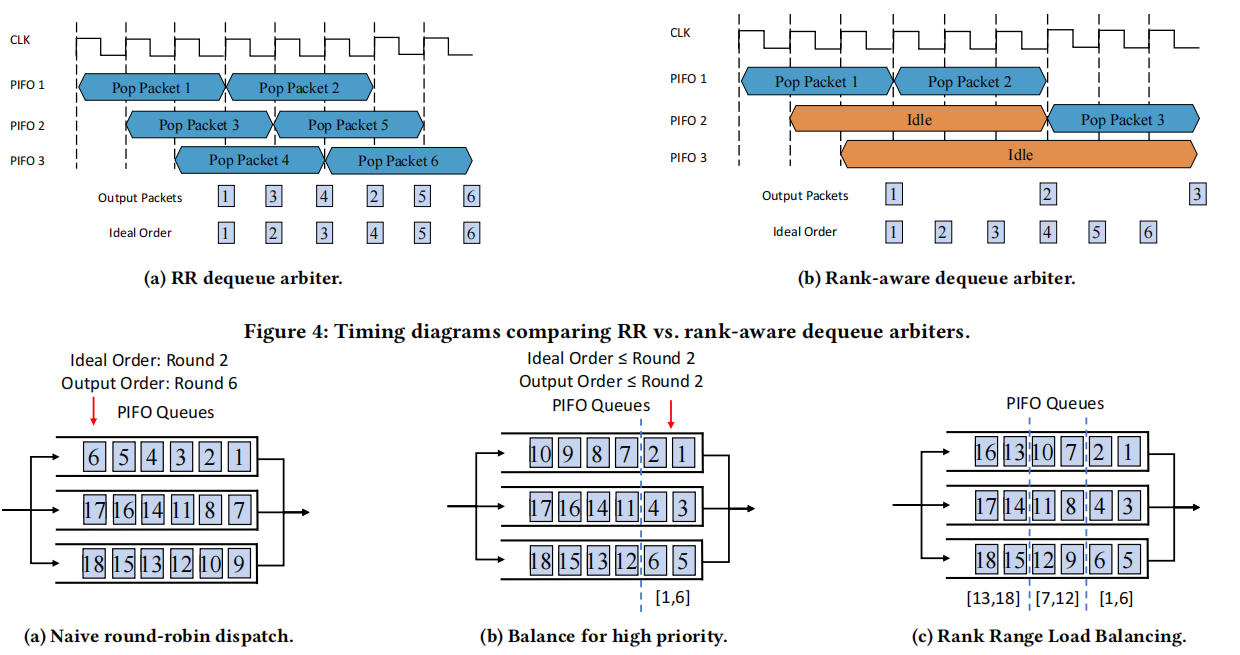
Scale-up PIFO takes the same basic approach that high-speed links use with SerDes lanes: it aggregates several PIFO queues instead of trying to scale one queue indefinitely. Simple round-robin parallelization is not sufficient, because packets with similar ranks can become concentrated in one sub-queue and the global departure order can drift far from an ideal PIFO. The paper therefore treats scheduling error as the central cost of parallelism.
Key idea and contribution:
The main mechanism is Rank Range Load Balancing. Scale-up PIFO divides the rank space into ranges, spreads packets from each range across the parallel PIFOs, and adjusts the range boundaries as the observed rank distribution changes. This keeps most reordering local to one rank range and bounds a packet’s departure-time error by the time needed to drain that range.
The fast path is kept simple. A Load Balancer maps an incoming rank to a range and chooses a PIFO, while a separate pipelined Border Adjuster periodically splits overloaded ranges and merges underloaded ones. The paper analyzes why naive round-robin parallel PIFOs accumulate large error and derives the improvement from range partitioning under an explicit analytical model. The key logic is implemented in SystemVerilog and synthesized in 28 nm, and the authors also provide a P4 version of the load balancer for future switches that expose PIFO primitives.
Evaluation
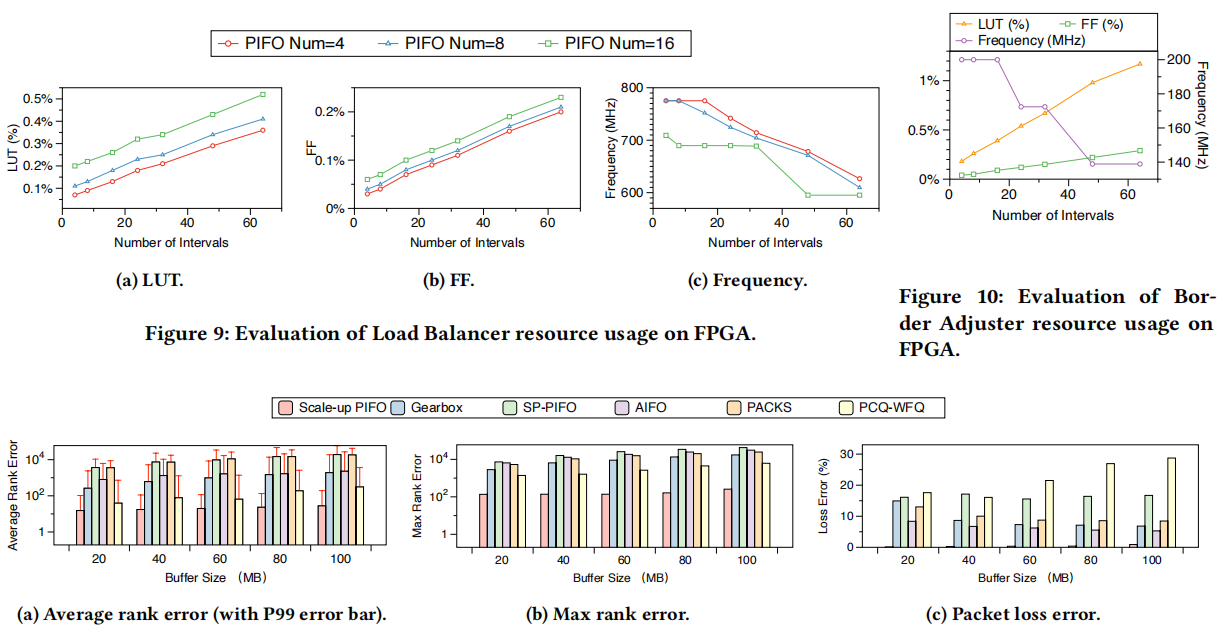
On a Xilinx Alveo U200 FPGA, the Load Balancer uses at most 0.52% of LUTs and 0.23% of flip-flops. Depending on the number of PIFOs and ranges, it runs at about 595-775 MHz. In GlobalFoundries 28 nm synthesis, an 8-PIFO, 16-range Load Balancer reaches about 1.2 GHz in 0.0337 mm2; at a 150-byte average packet size, this per-packet processing rate corresponds to more than 1.6 Tbps. The Border Adjuster is slower because it is off the per-packet critical path; a 16-range configuration runs at 200 MHz and occupies 0.0173 mm2.
NS-3 simulations compare Scale-up PIFO with SP-PIFO, AIFO, PACKS, Gearbox, PCQ, and an ideal PIFO. Under WebSearch traffic on a single switch, Scale-up PIFO reduces average rank error by at least 238, 52, and 233 times relative to SP-PIFO, AIFO, and PACKS, while reducing loss error by at least 19, 6, and 9 times. Relative to Gearbox and PCQ, rank error improves by about 17 and 3 times, and loss error by 8 and 32 times. In a 144-server leaf-spine network running Shortest-Flow-First, high-load short-flow FCT is at least 73%, 97%, and 45% lower than AIFO, SP-PIFO, and PACKS. An ablation shows that Rank Range Load Balancing reduces average and P95 FCT by 28% and 51% compared with simple parallel round-robin PIFOs. The sensitivity study selects 16 ranges and a 1,000-packet update interval as the default trade-off.
Q&A
Q: Is scheduling error unique to programmable schedulers?
The authors explained that scheduling error is not unique to programmable schedulers. High-throughput scheduler implementations have long faced hardware constraints that can force a trade-off between accuracy and practicality. Scale-up PIFO follows the same principle: it sacrifices a small amount of scheduling accuracy to scale throughput, while rank partitioning and partition-based load balancing keep the measured error small.
Personal thoughts
The cleanest part of the design is the decision to scale the scheduler horizontally and then control the ordering error that parallelism introduces. The rank-range mechanism is not complicated, but it gives the system something a plain collection of parallel queues lacks: a way to relate hardware scaling to a quantitative scheduling-error bound. The ablation against simple round-robin parallel PIFOs is especially useful because it isolates the value of the range-based balancing mechanism.
The 1.6 Tbps result should still be read carefully. The FPGA and ASIC work validates the Load Balancer and Border Adjuster, not a complete 1.6 Tbps scheduler containing eight physical PIFO implementations plus the full packet-memory system. The design assumes fast PIFO primitives underneath. The analytical error results also have explicit assumptions: they consider fixed-border epochs, exact sub-PIFOs, and average-case dispatch behavior in which packet ranks are not adversarially correlated with the dispatch phase. The paper therefore does not claim an unconditional low-error guarantee for arbitrary traffic. It further notes that adversarial rank distributions can put most traffic into one range, reducing the benefit of load balancing, and packets from the same flow can be reordered across sub-queues unless an extra per-flow mechanism is added. I would therefore view Scale-up PIFO as a strong scaling architecture for future PIFO-capable hardware, rather than a drop-in replacement for every scheduler today.