Title: STORM: Enabling Traffic Scheduling for RDMA
Authors: Jichun Wu (University of Cambridge); Ran Shu and Yongqiang Xiong (Microsoft Research); Gianni Antichi (Politecnico di Milano and Queen Mary University of London); Jon Crowcroft and Andrew W. Moore (University of Cambridge)
Scribe: Jinghui Jiang (Xiamen University)
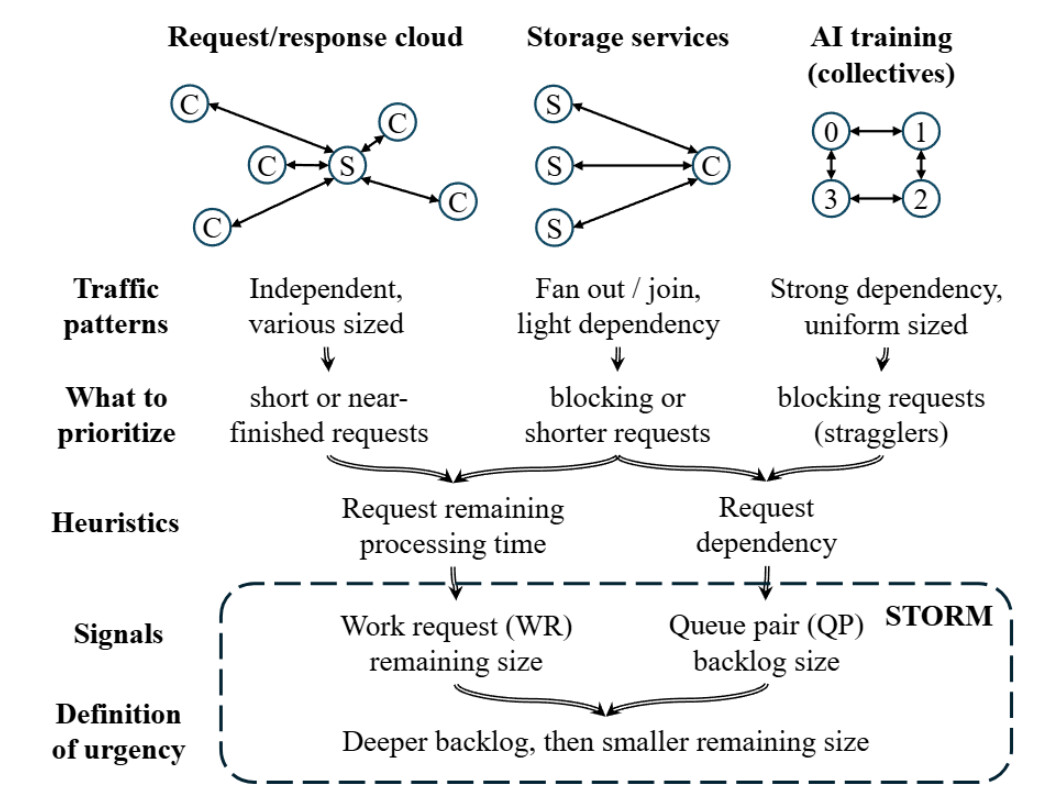
Introduction: Remote Direct Memory Access (RDMA) is now used by a broad range of datacenter workloads, including request-response services, storage fan-out/join pipelines, and distributed AI training. Although the RNIC decides when requests are transmitted and which network priority they receive, production deployments commonly assign a service a single priority class and use fair sharing within that class. This policy is a poor fit for workloads with very different scheduling objectives. Short independent requests benefit from shortest-remaining-processing-time (SRPT) scheduling, while storage and collective workloads are dominated by head-of-line blocking and dependency-driven stragglers. Existing TCP-oriented schedulers often infer flow size or require upper-layer information, and application-level coflow or collective schedulers leave the final RDMA arbitration unchanged. STORM asks whether an RNIC can provide useful request scheduling using only metadata it already observes, without application hints or a full dependency graph.
Key idea and contribution: STORM identifies two RNIC-visible signals: the remaining bytes of the head-of-line work request and the number of logical transactions queued behind it in the same queue pair (QP). It combines them into a simple urgency order: prioritize the QP with the deeper backlog, and break ties using the smaller remaining request size. Remaining size preserves the benefit of SRPT for independent traffic, while backlog acts as a local proxy for dependency criticality. A QP with queued work behind its current request is potentially blocking more progress, so finishing that request can release multiple operations.
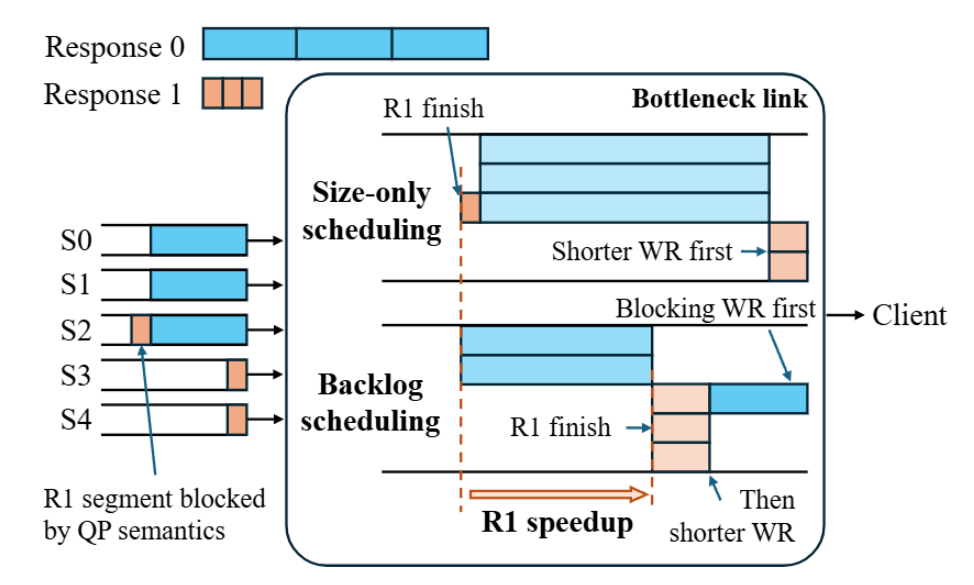
The default design maps this continuous urgency signal onto three existing network priorities. Requests no larger than one bandwidth-delay product (BDP) are sent immediately at the highest priority. For larger requests, the sender transmits an initial BDP to avoid startup stalls, using a backlog-reserved priority when the QP has queued work and a lower priority otherwise. Beyond the first BDP, the receiver maintains a small active set and issues coarse-grained transmission grants. By default, at most one super-BDP QP is active in the backlog priority and one in the other priority. The receiver selects candidates by backlog first and remaining size second. This is eligibility control rather than per-packet pacing, so the underlying congestion-control mechanism can still regulate the sending rate.
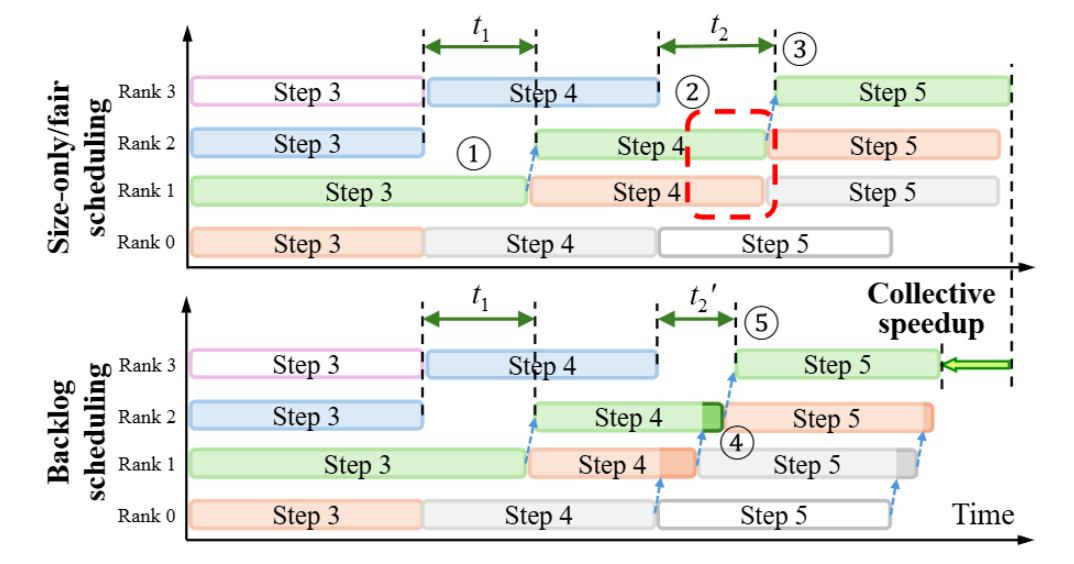
STORM schedules logical transactions rather than raw WQEs, grouping fragmented work requests with a shared identifier or, as a fallback, a short temporal grouping rule. The prototype extends the Coyote FPGA RoCEv2 NIC with counters, comparisons, per-QP state, priority tagging, and a two-slot receiver controller. The design is intended to work with both in-order RoCEv2 and transports that tolerate reordering; the in-order version uses conservative promotion guards to avoid inducing packet reordering. The main contribution is therefore a NIC-resident, transport-agnostic scheduling layer that turns RDMA-native metadata into an enforceable urgency signal with a very small priority budget.
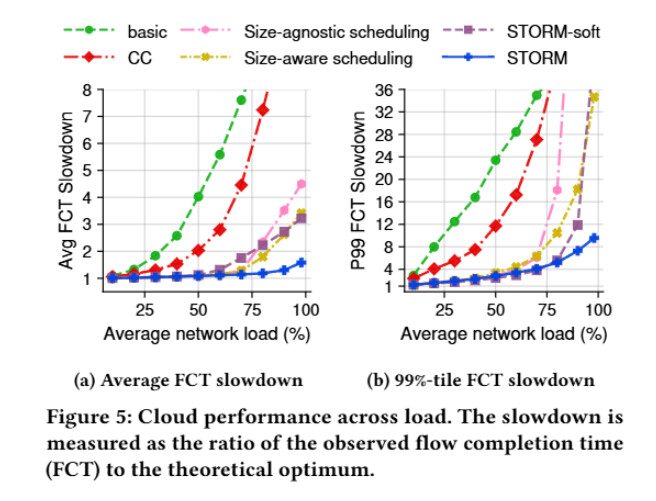
Evaluation: The authors evaluate STORM using an extended ns-3 simulator with a 128-host, 100 Gbps spine-leaf network, five cloud traffic distributions, and SimAI traces for GPT-3 and LLaMA training. They compare against congestion-control schemes, size-agnostic and size-aware schedulers, and a software-only STORM variant. Under heavy cloud load, STORM achieves the lowest average and P99 FCT slowdown. In the reported 80% load sensitivity case, average/P99 slowdown decreases from 9.560/43.571 for the basic fair-sharing configuration to 1.230/6.355 for the default three-priority STORM configuration. Across the evaluated LLM workloads, STORM reduces iteration time by roughly 10%, with improvements of up to 12%; collective microbenchmarks show gains of up to about 10% for AllReduce and 15% for ReduceScatter. The Alveo U250 FPGA implementation adds only 0.16% LUT, 0.05% registers, and 0.15% BRAM relative to the available resources, with no observed throughput penalty. A four-server ConnectX-6 testbed reports 8%-53% completion-time speedups, although it implements only the sender-side priority assignment because current RNIC APIs do not expose enough control for the full receiver-side algorithm. This result is significant because it shows that request ordering inside an RDMA NIC, even within one existing service class, can improve both cloud tail latency and collective training time without changing applications or reserving a large number of priority queues.
Q: Does STORM need to know which application is running, or whether the traffic belongs to a collective, in order to detect dependencies?
A: No. The authors deliberately make STORM application-agnostic. The NIC does not receive a full dependency graph or a collective identifier. It only observes that additional work has accumulated behind the current head-of-line request in a QP. That backlog is used as a local indication that the current request may be blocking further progress. Thus the dependency signal is inferred entirely inside the NIC, although it is an approximation rather than explicit application-level dependency information.
Q: Could STORM be implemented using programmable congestion-control mechanisms on a commodity NIC?
A: Potentially, on newer programmable NICs such as ConnectX-7 or ConnectX-8. The authors could not implement the full mechanism on their ConnectX-6 hardware, because the available NIC API does not expose sufficient hooks for receiver-side active-set scheduling and grants. Their real-hardware evaluation therefore validates the priority-based part of STORM, while the complete receiver-coordinated design is primarily evaluated in simulation.
Personal thoughts: I like the way STORM finds a scheduling signal that is both workload-relevant and naturally available at the RNIC. The paper does not try to reconstruct a complete application dependency graph. Instead, it uses QP backlog as a deliberately local and inexpensive approximation, then combines it with exact request size. This gives one policy a sensible behavior across three otherwise different regimes: short independent requests, storage requests blocked at a gatekeeper QP, and collective stragglers. The event-driven implementation and the very small FPGA resource cost also make the design more credible than a scheduler that requires per-packet global optimization.
The main limitation is the gap between the conceptual design and current commodity hardware. The paper’s strongest end-to-end gains come from the simulated receiver-side active-set and grant mechanism, while the testbed only emulates priority tagging. Backlog can also be a noisy dependency proxy: a deep QP may contain independent batched work, and application libraries must group fragmented WQEs correctly. Strict-priority queues may cause starvation under adversarial mixes, and receiver feedback is delayed by at least an RTT. Follow-up work should evaluate full STORM on a programmable RNIC, use real storage dependency traces rather than only size distributions, and study fairness and multi-bottleneck behavior when several QPs accumulate backlog simultaneously.