Title: Achieving Network Efficiency Through Service Collaborative Capacity Sharing and Enforcement
Authors: Vinayak Dangui (Meta); Guyue (Grace) Liu (Peking University); Alaleh Razmjoo, Guanqing Yan, Mahesh Nayak, Mansi Babbar, Brian Bierig, Tejas Birajdar, Prabhakaran Ganesan, Lilian Liu, Matt Maia, Jerry Yang, Shrinivas Petale (Meta); Satyajeet Singh Ahuja, Abhinav Triguna (Meta Platforms, Inc.); Ying Zhang (Meta)
Reviewer: Xing Fang (SNG fifth-year PhD student)
Introduction
This paper from Meta and Peking University presents SCOPE, the Service-Collaborative netwOrk capacity sharing Planner and Enforcer. Instead of optimizing traffic engineering only inside the network, SCOPE creates a closed loop connecting network capacity, service placement, resource cost, and runtime traffic enforcement. Network and service teams jointly decide where to deploy compute and storage, how much bandwidth to request, and how workloads should adapt when capacity is scarce. The framework has operated in Meta’s production environment for more than five years.
AI training, inference, and content services are rapidly increasing Meta’s inter-region traffic. In 2024, Meta expanded WAN capacity by 70%, yet inter-region traffic grew by roughly 2.5 times over the same period, driven largely by machine-learning workloads. Some ML teams expected a further fivefold increase in demand, while fiber, datacenter space, and power constrained the rate of physical network expansion. Even continued link deployment cannot allow supply to catch demand indefinitely.
The problem is made harder because compute, storage, and network resources are often planned by different teams. A new region may already contain servers and GPUs before the required WAN capacity is available, leaving expensive compute underused because inter-region bandwidth is missing. Simply publishing current spare bandwidth is not enough: network planning must also account for link failures, maintenance windows, and the SLOs of different workloads.
Dependencies among services further amplify the issue. Scribe’s read service, for example, depends on a separate low-priority transport service. In one incident, read latency for a critical Ads workload increased not because Scribe exceeded its own quota, but because the downstream transport service generated excess traffic, was downgraded to traffic without an SLO, and suffered heavy loss. A traditional per-service quota cannot represent this dependency or identify which service should bear the network cost.
Historically, Meta spread backbone cost evenly across server hardware. Services that consumed large amounts of WAN bandwidth therefore had little incentive to optimize, and service teams could not make explicit tradeoffs among adding compute, using caches, compressing data, or buying more network capacity. At the same time, more granular services and traffic classes increase the complexity of host-side enforcement and troubleshooting. The challenge is therefore not just computing a larger allocation, but giving network and service teams a shared, credible view of capacity, cost, and enforcement.
Core Ideas and Contributions
The authors’ core insight is that no single algorithm can solve the problem. Quotas without cost signals give service teams little reason to optimize. Prices without realistic capacity and failure models are difficult to trust. Demand declarations without runtime enforcement give services little reason to honor their requests. SCOPE therefore models the relationship between network and service teams as a continuously repeated, closed-loop contract.
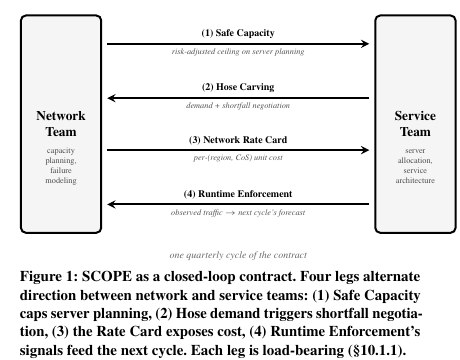
Figure 1: SCOPE forms a four-leg loop between network and service teams: safe capacity, Hose Carving, the network rate card, and runtime enforcement.
Information flows in four alternating directions. The network team first publishes the safe capacity that each region and service class can reliably support, constraining server planning. Service teams then submit aggregate Hose demands, which the network uses to calculate grants and negotiate shortfalls. A rate card translates bandwidth in different regions and service classes into costs that service owners can understand. Finally, host-side systems enforce the allocations and feed actual traffic, downgrades, and losses into the next planning cycle. Without any one of these four components, the loop is difficult to sustain.
This collaboration also depends on an important assumption: Meta’s services are internal teams that ultimately share the company’s efficiency goals. They are willing to change their architectures in response to capacity and cost signals and have little reason to deliberately misreport demand. Safe-capacity calculation, demand modeling, and enforcement can still apply in an external multi-tenant cloud, but informational showback alone may not be enough; formal billing or a market mechanism may also be required.
Safe capacity. SCOPE defines safe capacity as the maximum traffic that can meet its SLO despite link failures and maintenance. It calculates this value separately by region, service class, and traffic direction, combining physical capacity, permitted link utilization, and maintenance headroom. The production system uses water-filling: it incrementally adds simulated traffic to each region, rolls back the latest increment when an SLO is violated, and marks the region as saturated. The process typically converges in five to ten simulation rounds. Every week, the teams compare simulated results with real traffic and loss measurements and jointly investigate discrepancies rather than automatically changing the model.
Hose Carving. Meta uses the Hose model to describe a service’s aggregate ingress and egress demand in each region instead of fixing a complete traffic matrix in advance. A traditional method must generate many Dominating Traffic Matrices (DTMs) from the high-dimensional Hose polytope. Their number grows quickly with the region count, and they cover extreme states that production traffic may never reach. SCOPE first applies geometric carving, constraining the feasible space by the angle between historical traffic and an anchor matrix. It then uses PCA to find the main directions of real traffic variation, shrinking the isotropic cone into a tighter hyperellipsoid aligned with the principal components.
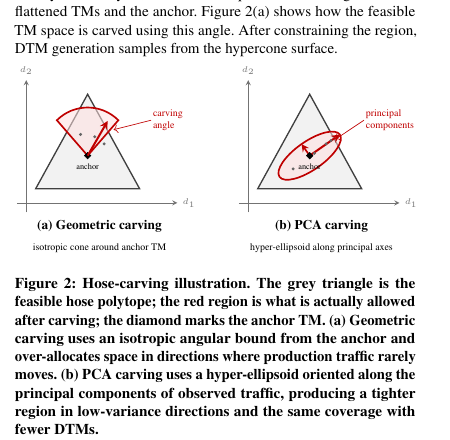
Figure 2: Geometric carving applies a uniform angular bound, while PCA carving produces a tighter feasible region along the dominant directions of observed traffic.
Fewer than 50 principal components capture more than 95% of traffic-matrix variance and produce about 100 DTMs, roughly an order of magnitude fewer than the uncarved approach while retaining nearly complete coverage. This tighter, more realistic demand space reduces conservative reservation and allows quarterly bandwidth grants to be computed within practical time.
Network rate card. SCOPE calculates the marginal network cost per Gbps for each region and service class. The rate covers not only links, optics, and fiber, but also the failure redundancy required by the class and the capacity it displaces from higher-priority traffic. Network Rate Translation converts service-level metrics such as QPS and storage operations into bandwidth. SCOPE uses showback rather than direct chargeback: each service sees its monthly network cost but does not immediately pay less by declaring less demand, reducing the incentive to underreport.
Grants and runtime enforcement. SCOPE divides the day into four six-hour windows and forecasts and grants capacity separately for each period, encouraging batch jobs to move away from peak hours. To handle uneven regional capacity, demand-grant equalization identifies demand constrained by bottleneck regions and reduces requests on those paths, releasing capacity for other regions. In the paper’s three-region example, total granted bandwidth rises from 14 Tbps to 22 Tbps.
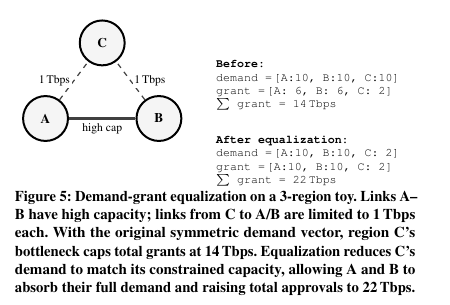
Figure 3: Two links involving Region C are the bottleneck. Reducing demand to and from C allows A and B to use their high-capacity link fully, increasing the total grant from 14 Tbps to 22 Tbps.
The host-side enforcement system marks traffic above quota as Non-Conforming and transports it without an SLO guarantee. To prevent critical and batch traffic within one service from being downgraded together, policies can protect traffic by source port, destination port, or Usecase ID. Work-conserving sharing within a service class makes unused quota immediately available to other services while continuing to protect sensitive workloads.
Experimental Evaluation
SCOPE has operated in Meta’s production environment for more than five years, covering dozens of regions, hundreds of critical services, tens of thousands of jobs, and more than 52,000 hosts, while managing traffic at approximately O(1000T) scale. Over the past year, capacity planning, service optimization, and runtime enforcement together reduced global traffic by more than 500 Tbps. Service coverage for the Silver and Gold traffic classes is now close to 85%.
Hose Carving raises bandwidth approval from roughly 75% to above 90%. In a representative scenario, adding demand-grant equalization, Carving, and off-peak grants in sequence increases approval from 73% to 97%. Across O(100) services, average approval remained at 97%–99% over the past year. Even the bottom decile, whose approval previously ranged from 40% to 60%, now exceeds 90%. Equalization usually converges in two rounds and never more than three. It stays within 2% of a full ILP recomputation while reducing runtime from tens of minutes to seconds.
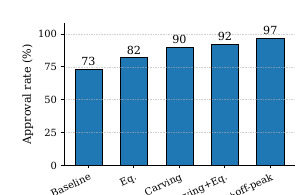
Figure 4: Equalization, Hose Carving, and off-peak grants progressively raise bandwidth approval from 73% to 97%.
Production measurements of safe capacity broadly agree with max-flow results. Simulated values can differ from live observations by a factor of two to three in some capacity-constrained regions, but reserved headroom and weekly calibration prevented any SLO violation caused by ICP/Gold safe-capacity prediction error during five years of operation. Under runtime enforcement, protected and in-quota traffic continues to see essentially zero loss even when Non-Conforming traffic experiences heavy drops. Work-conserving sharing within a class reduces remarking by as much as 100 times.
Service-side optimization also produced substantial gains. Scribe reduced network consumption fourfold through caching, centralized reads, and fewer messages. Datacenter-affinity routing in Service Router lowered cross-datacenter traffic by 15%. Instagram moved eventually consistent ML training traffic from Gold to Bronze, saving tens of millions of dollars. Incremental transfer reduced News Feed traffic by 40%, while dictionary compression halved some high-priority small-message traffic. The gains are strongly long-tailed, however: the top quarter of services accounts for about 80% of total savings.
Q&A
Q1: Since this is an internal pricing system, does it use dynamics that differ from conventional pricing to steer services toward greater network efficiency?
A1: An internal network team has roughly two options. It can price capacity according to the planning output, so the price reflects what services request, or it can deliberately steer prices toward a desired efficiency outcome—for example, charging more for higher classes of service and using that revenue to subsidize lower classes. SCOPE currently follows the first approach and has not yet used pricing itself as a steering mechanism, although the latter remains an option to explore.
Q2: Is traffic cheaper when a service sends it during a low-demand period?
A2: No. Because the planning cycle is generally quarterly, although it now runs more frequently in practice, the price remains constant throughout the day. Instead, SCOPE exploits off-peak capacity through higher quotas and work-conserving sharing. For example, if Gold bandwidth is idle while Silver demand exceeds its quota, Silver traffic can use the otherwise idle Gold capacity.
Personal thoughts
What I like about SCOPE is that it does not reduce network efficiency to a traffic-engineering algorithm. It translates network capacity into planning constraints and cost information that service teams can act on directly. Much bandwidth waste originates not in network devices, but in poor cache placement, data-replication choices, or traffic-class selection. Optimization becomes possible only when the relevant teams can see the network cost of those decisions.
The approach nevertheless depends on shared goals and long-term cooperation among internal teams; external tenants may not respond voluntarily to showback signals. The paper’s savings also come mainly from a small number of large consumers, so the marginal benefit of onboarding many small services may be limited. For another network, identifying its largest bandwidth consumers and establishing a collaborative process may be more practical than reproducing every SCOPE component.