Title: OBM: Optimal Shared Packet Buffer Management in Switches
Authors: Dan Mani Binu, Jason Lei, Vishal Shrivastav (Purdue University)
Introduction
Datacenter switches share packet-buffer memory across output ports so that a busy port can temporarily use capacity left idle elsewhere. The buffer-sharing policy therefore has a direct effect on burst absorption, packet loss, and flow completion time. Most commercial switches use drop-tail schemes such as Dynamic Threshold (DT) because their threshold logic is easy to implement at line rate. The drawback is that they reserve room for ports that may become active later, and their best parameter settings depend on the workload. Push-out schemes can use the entire shared buffer by evicting packets that are already stored, but the best-known online policy, Longest Queue Drop (LQD), has traditionally been considered too difficult to implement at modern switch speeds.
OBM asks whether that implementation barrier can be removed rather than worked around. It also addresses a practical issue that classic LQD does not model: modern switches carry several traffic-priority classes. A direct use of LQD can therefore create priority inversions. The paper combines a priority-aware version of LQD with a hardware design that can perform its push-out operations at line rate.
Key idea and contribution:
OBM first extends LQD with priority-aware admission and eviction. It keeps LQD’s fairness across output ports and its throughput guarantee, while preferring higher-priority traffic within the same output port. With only one priority class, the policy reduces to standard LQD.
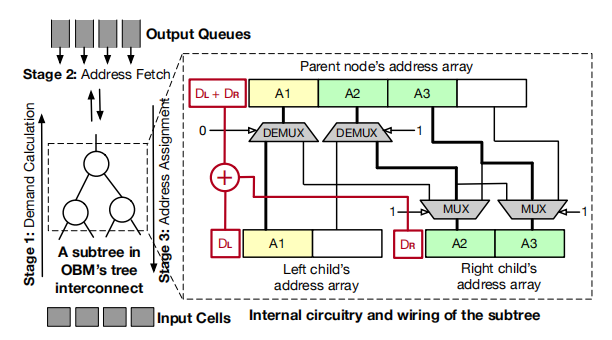
The implementation works at the granularity of fixed-size buffer cells instead of variable-size packets. OBM stores cell addresses with partial contiguity, which lets the hardware fetch several addresses from the selected queue in parallel while keeping fragmentation bounded. A pipelined tree-based interconnect then assigns those addresses to arriving packets without using a large full crossbar. These choices make the push-out path fast enough for line-rate operation and keep hardware cost modest as the port count grows.
Evaluation
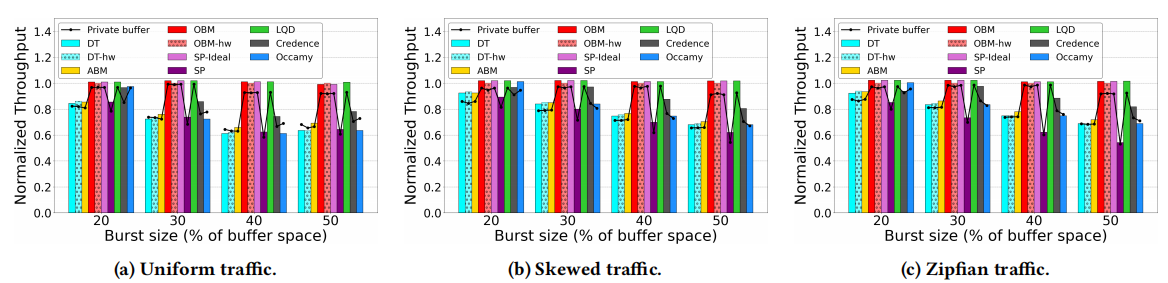
The authors implement OBM in Verilog on an AMD Alveo U200 FPGA as an 8-port, 25 Gbps-per-port switch with a 5 MB shared buffer, and they also synthesize the design with a 15 nm ASIC flow. Under uniform, skewed, and Zipfian burst workloads, the FPGA closely matches the software model. OBM achieves up to 64% higher switch throughput than DT, 52% higher than ABM, 35% higher than Credence, 30% higher than Occamy, and 45% higher than Selective Pushout. With one priority class, its behavior stays close to ideal LQD. The paper measures fragmentation overhead as the share of input packets that are dropped or trigger a push-out even though aggregate buffer capacity is still available; this occurs for roughly 0.3%, 0.05%, and 0.1% of packets under uniform, skewed, and Zipfian workloads, respectively.
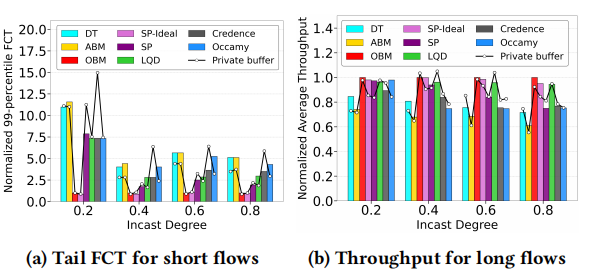
The FPGA design runs at 450 MHz and uses 1.7% of the LUTs, 1.3% of the flip-flops, and 2.4% of the BRAM of the reference switch design. ASIC synthesis estimates about 1.98 mm2 for a 512-port instance at 1.07 GHz. The network-level experiments use a 144-host leaf-spine topology with 100 Gbps access links, DCTCP or Swift, and Incast/Websearch workloads. For a single priority class, OBM gives 2-18 times lower short-flow tail FCT than practical Selective Pushout without reducing long-flow throughput. With three priority classes, it also outperforms classic LQD, reaching 2-12 times lower short-flow tail FCT in the reported settings.
Q&A
Q: Was OBM also implemented on an RMT switch, and what would make such an implementation difficult?
The authors explained that OBM was implemented on an FPGA, while software simulation was used for the network-wide evaluation. They do not currently consider a direct RMT-switch implementation feasible because the RMT pipeline does not support retrieving the multiple buffer cells required by the LQD-style push-out operation from the tail of a long queue.
Personal thoughts
What I find most convincing is that the paper does not stop at showing that LQD is a better algorithm. It changes the algorithm only where deployment requires it, then redesigns the packet manager around the actual cell-based buffer organization. That makes the hardware contribution and the buffer-management contribution depend on each other in a useful way. The priority-aware extension also matters because it targets a feature that real switches already need instead of evaluating only a single-class idealization.
The main limitation is the gap between the prototype and a production high-radix switch. The FPGA system is 8 x 25 Gbps, while the 512-port result comes from ASIC synthesis rather than a fabricated chip. OBM can also experience rare priority inversions because the queue state may change between demand calculation and address fetch; the paper reports about 0.3% even in a stress setting, so the effect is small but not eliminated. A useful next step would be an implementation inside a modern multi-terabit traffic manager, with production queueing features and sustained mixed workloads.